Blog
Page 30 of 59
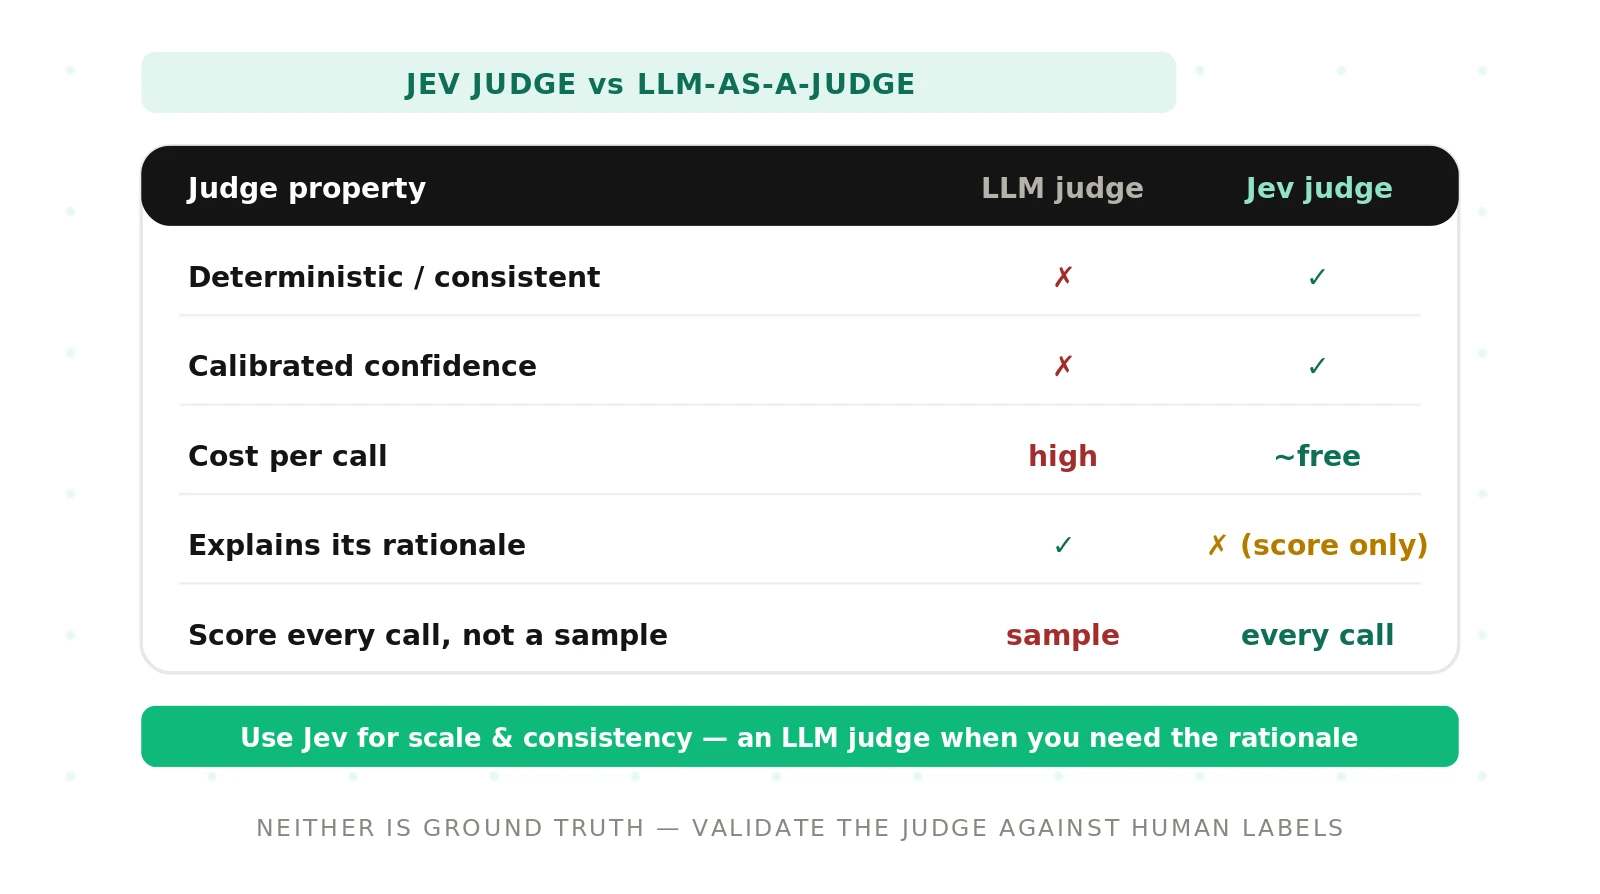
Jev as a Judge: A Calibrated Alternative to LLM-as-a-Judge
Jev as a judge matched human labels on all 500 pass/fail decisions in a small early LangChain study (5 examples, 100 repeats each), at $0.34 vs $28.17 for Claude. Then build and validate a Jev judge.
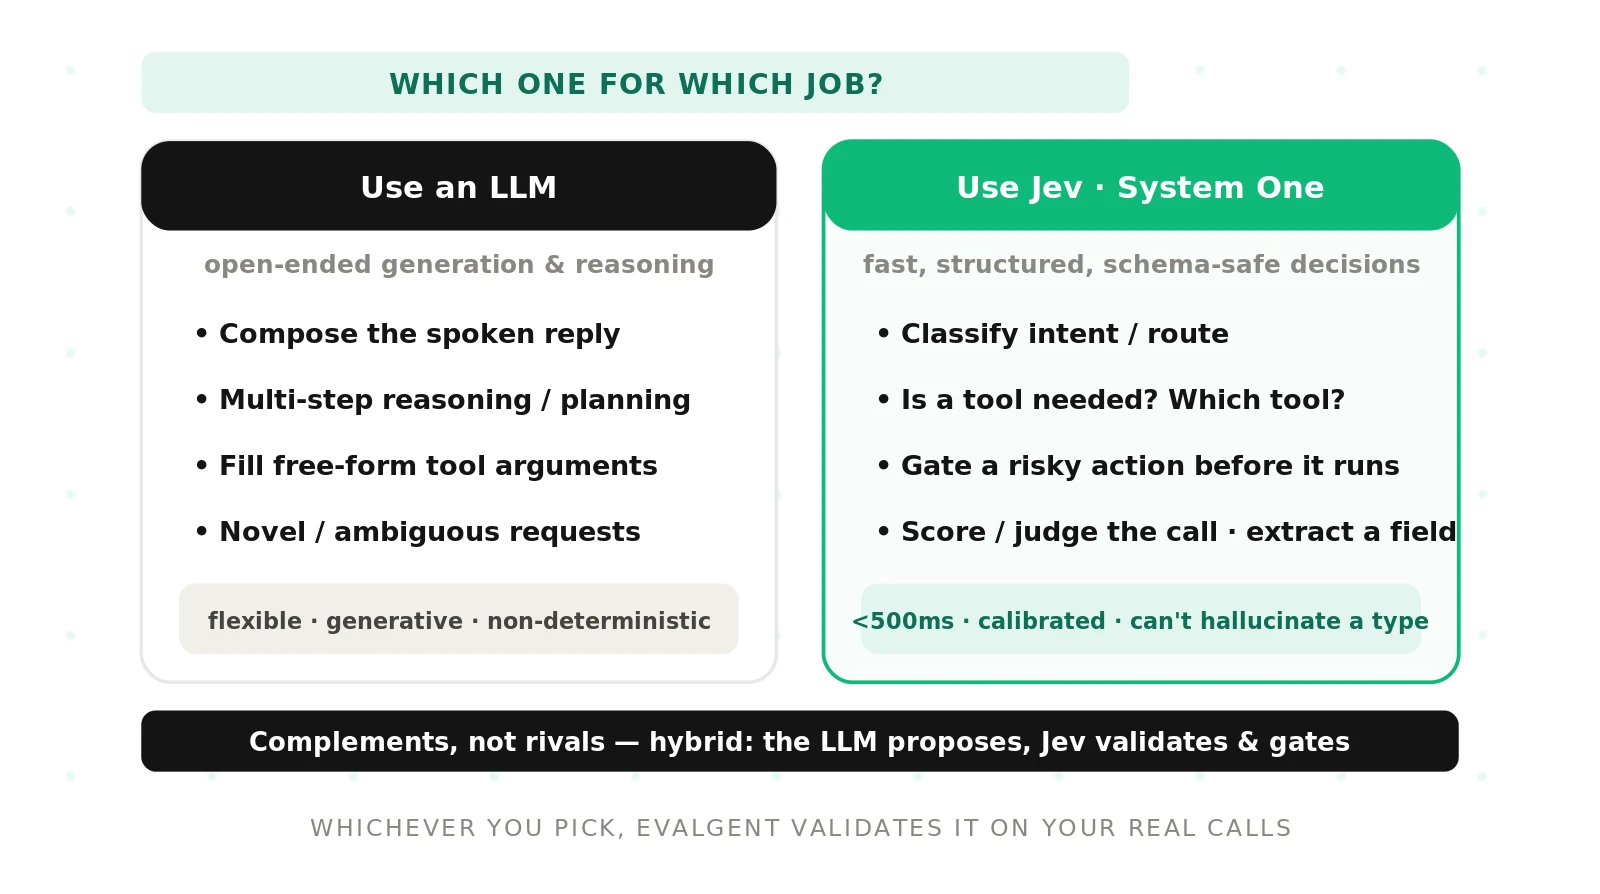
Jev vs LLM: The Key Differences, and When to Use Each
Jev vs LLM: an LLM writes text, Jev returns typed, calibrated decisions in milliseconds. 8 differences, side-by-side code, and the Jev alternatives.
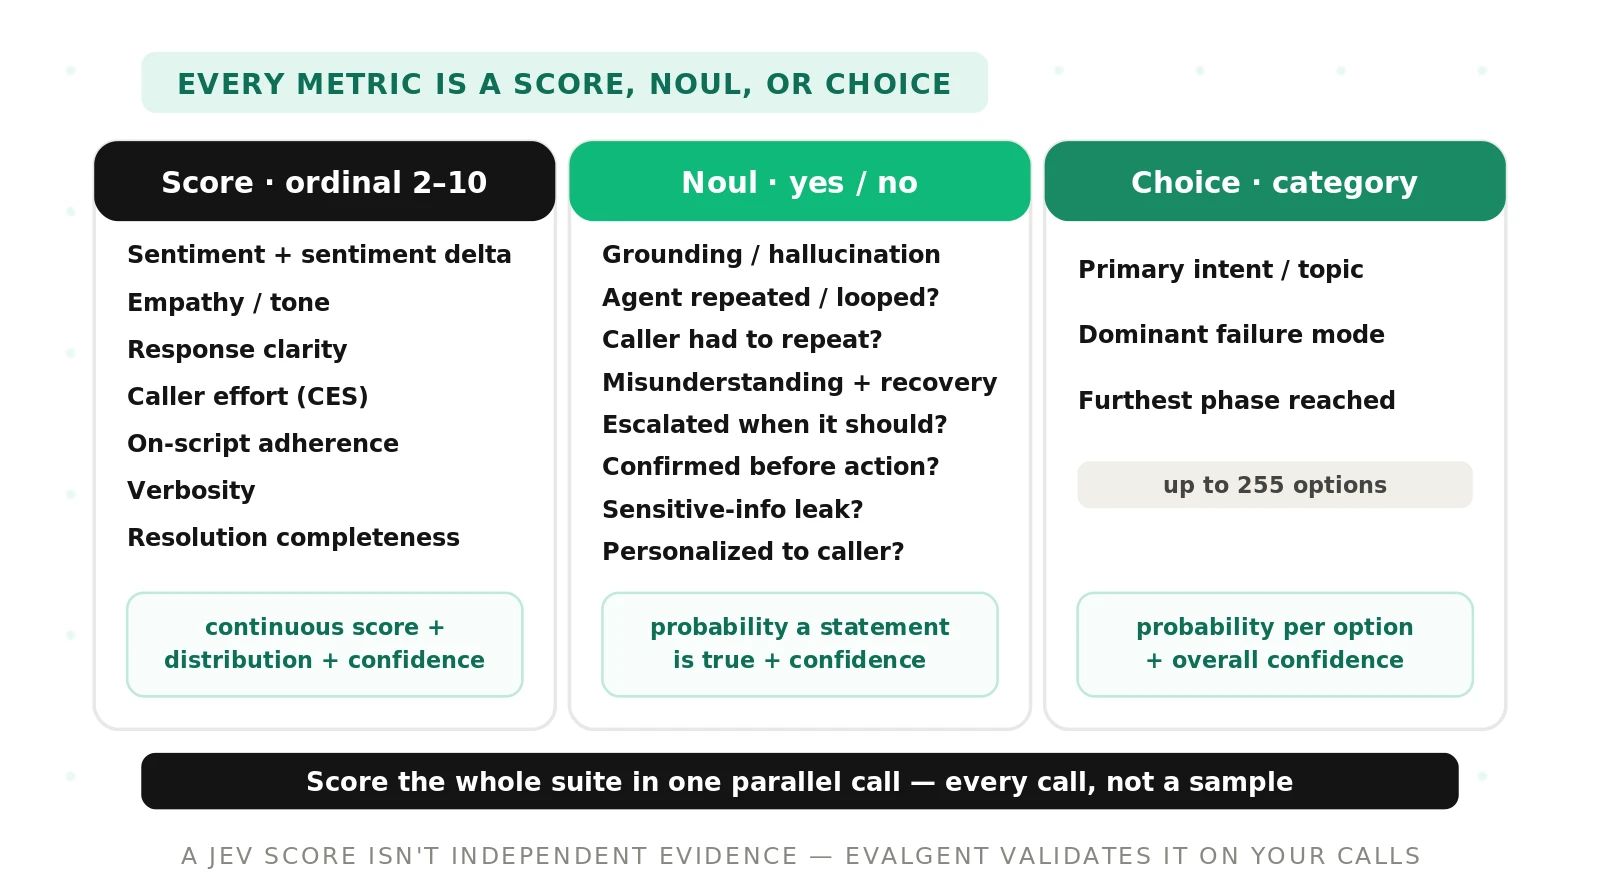
Jev Score, Noul and Choice: Voice Agent Metrics You Can Score
Jev Score, Noul and Choice explained: every voice agent metric as a real Jev question, with the JSON you send, the response, and Python to roll it up.
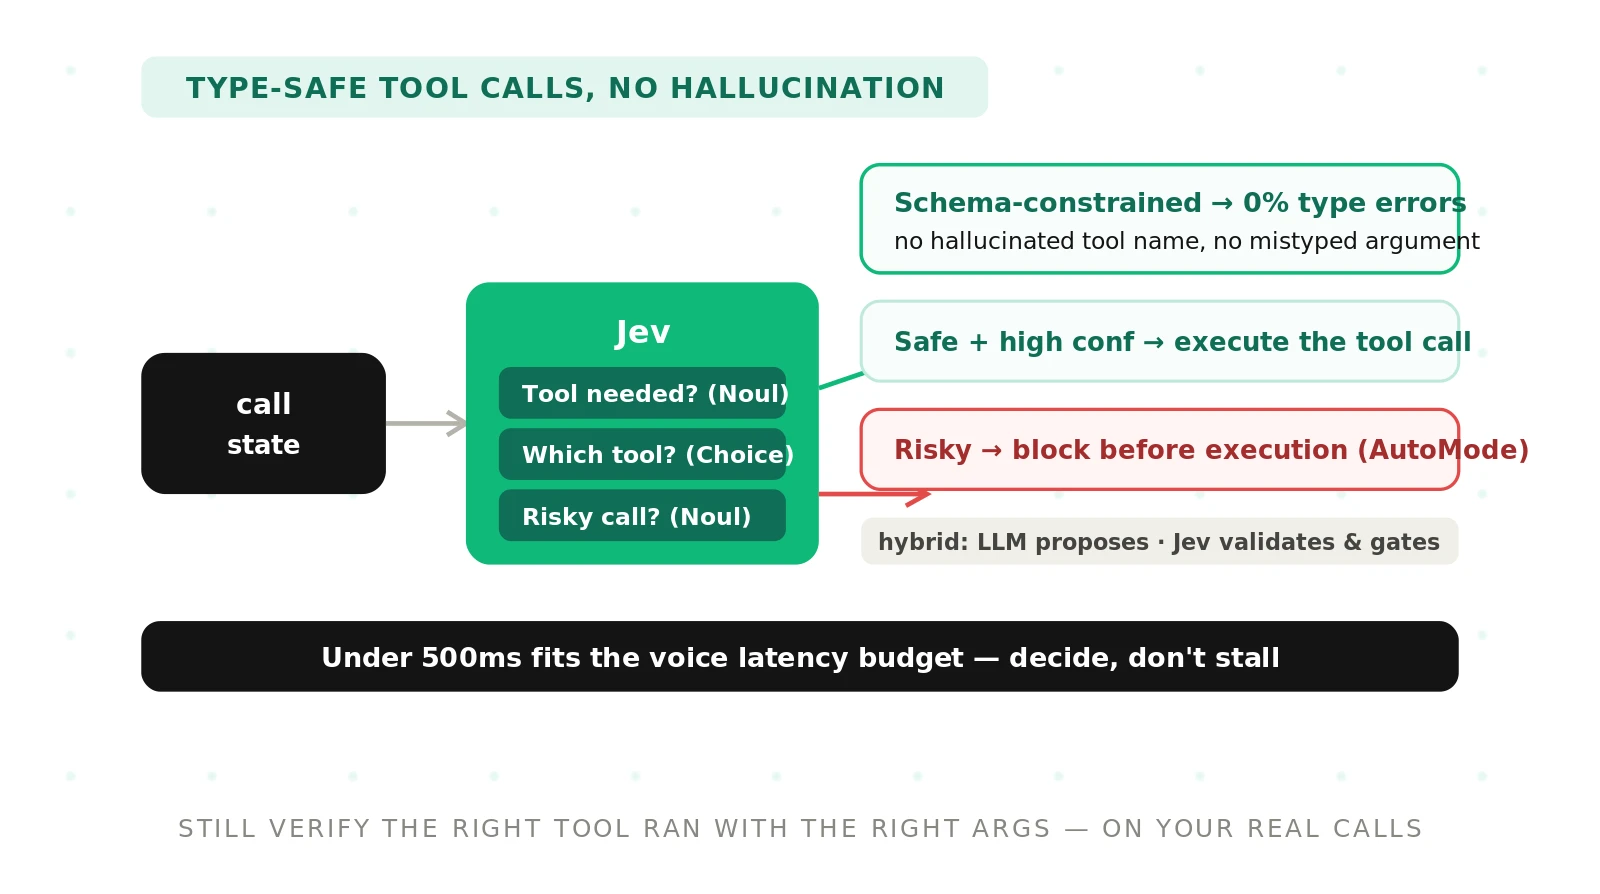
Jev for Tool Calling in AI Voice Agents
Jev cannot emit a hallucinated tool name or a mistyped value. Real requests, Python, and latency math for picking and gating tool calls in voice agents.
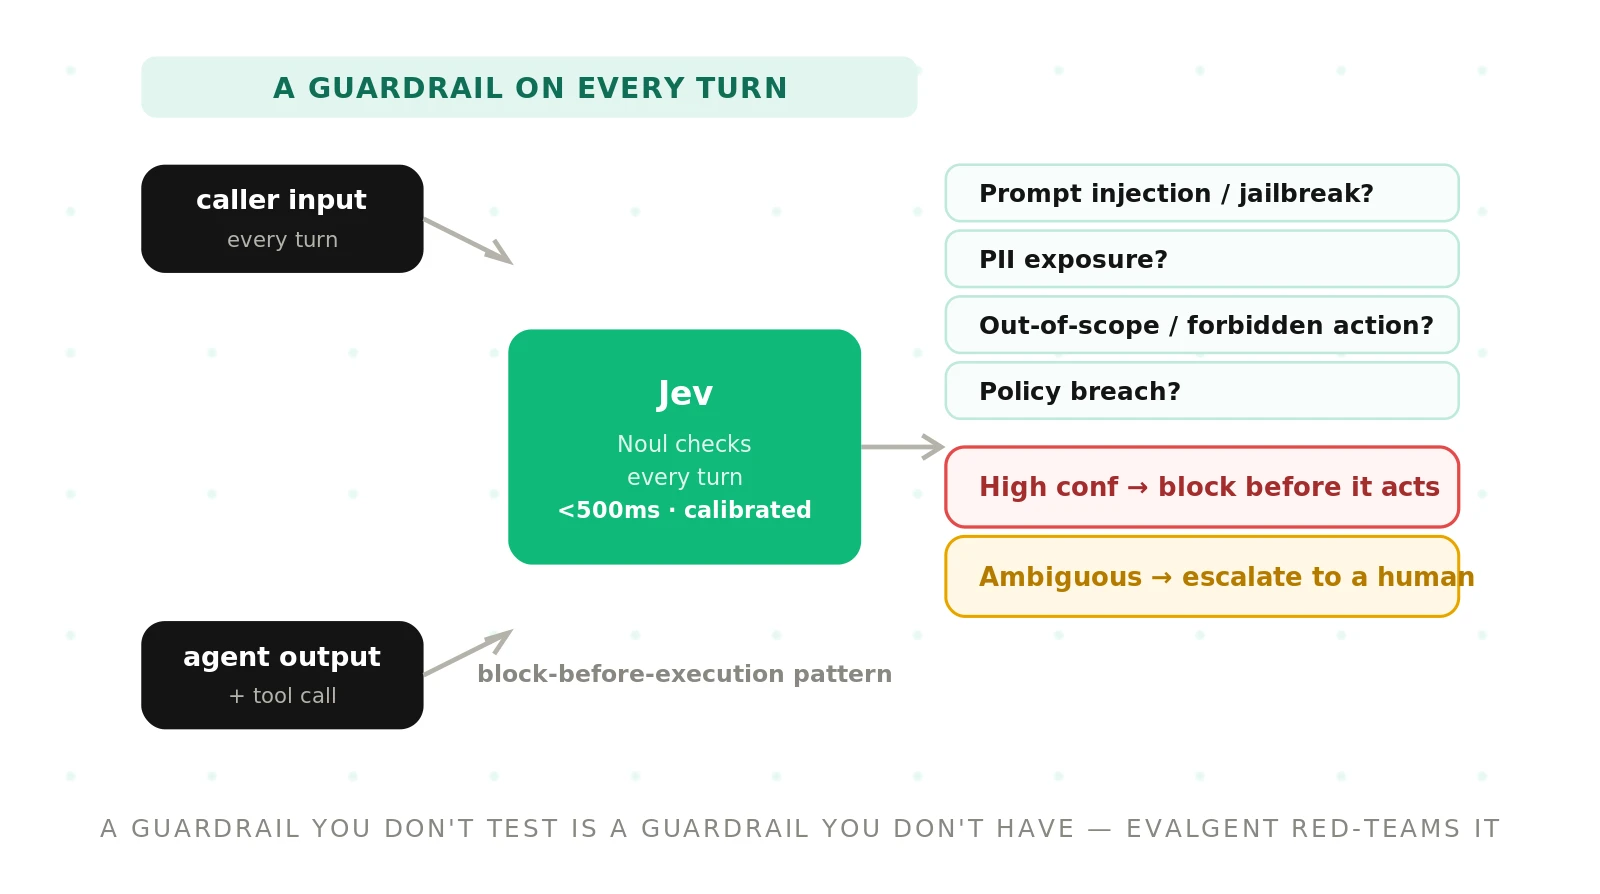
Jev for Voice Agent Guardrails and Jailbreak Detection
Jev voice agent guardrails check caller turns and tool calls in one fast call. Get code, gating logic, a threat catalog, and threshold tuning steps.
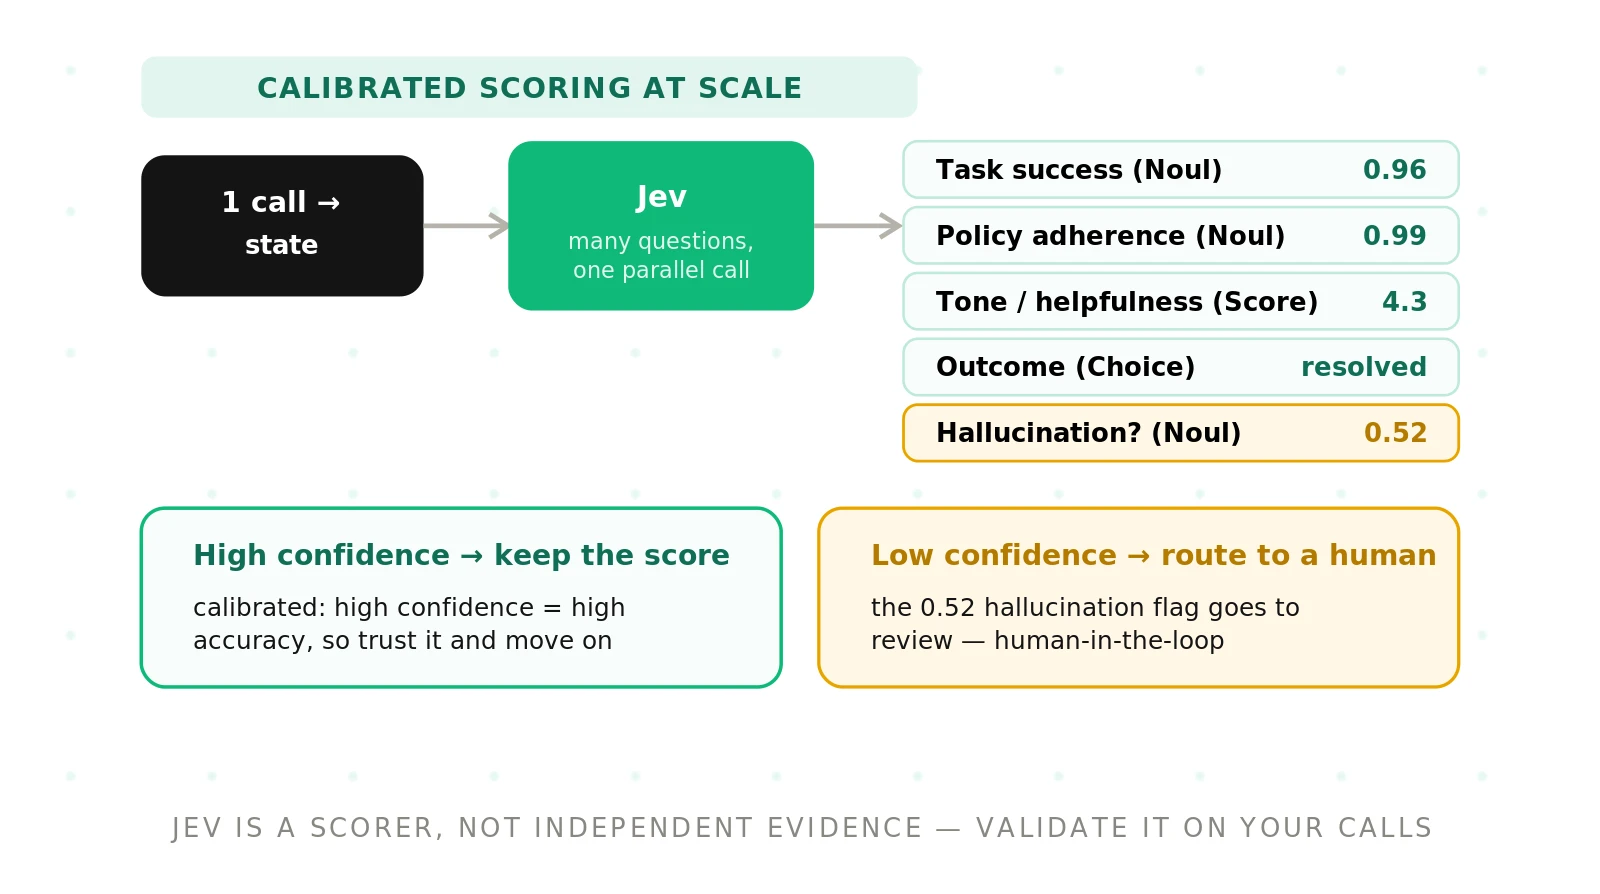
Jev for Voice Agent Evaluation: Calibrated Scoring at Scale
Jev voice agent evaluation turns each transcript into calibrated scores. Build a full rubric as Jev questions, then validate the scorer on your own calls.
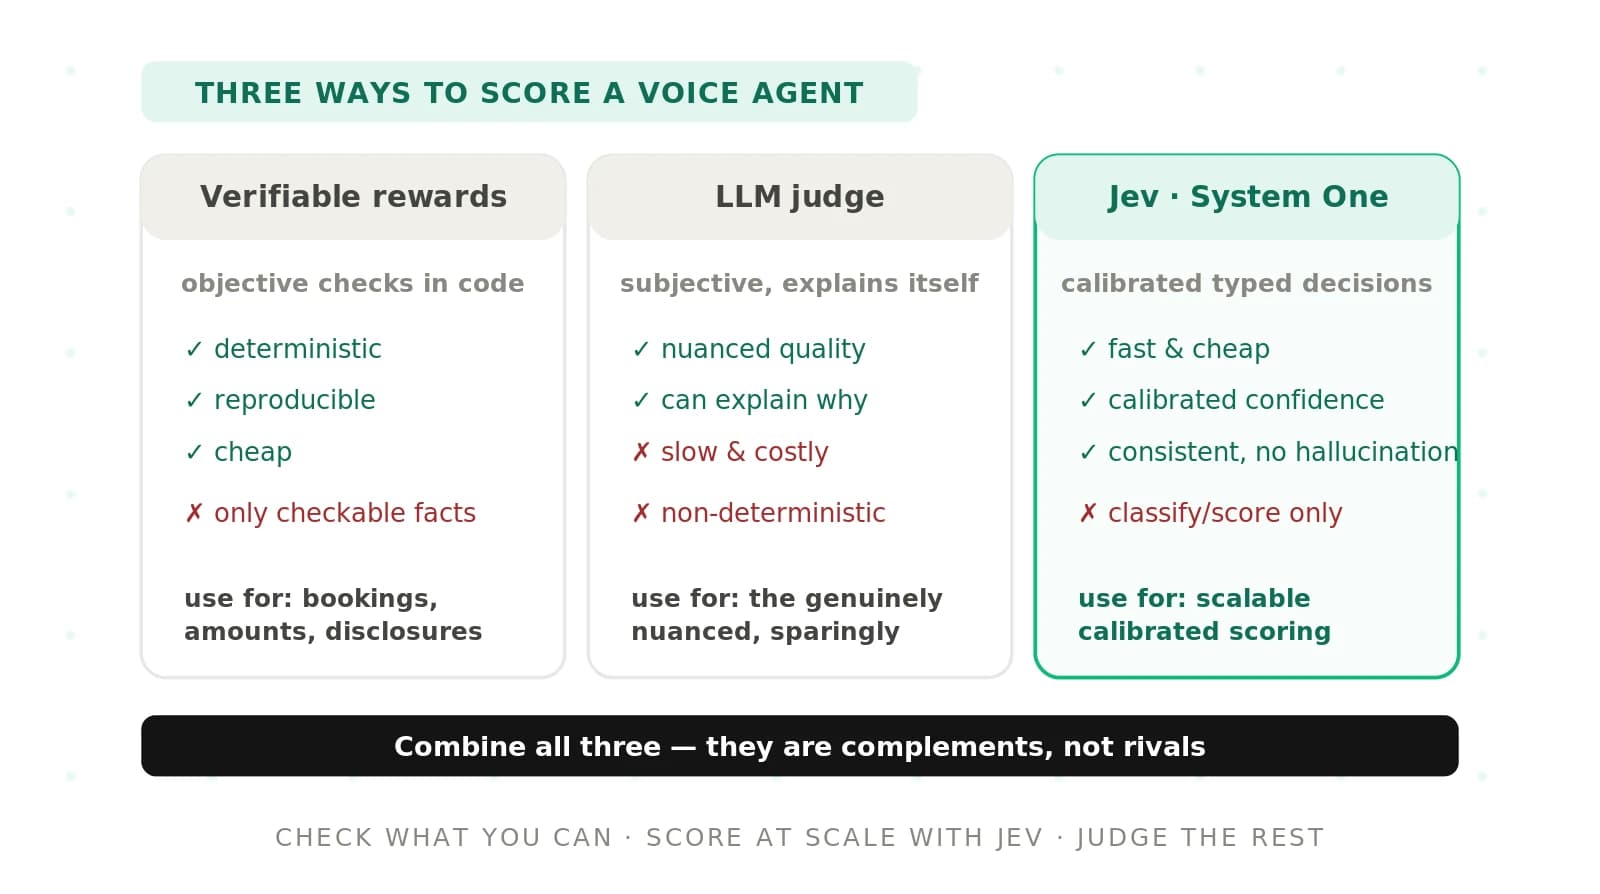
Verifiable Rewards vs LLM Judges vs Jev: 3 Ways to Score Voice Calls
Verifiable rewards vs LLM judges vs Jev: one voice call scored three ways in code, with agreement, variance, and cost compared, and how to layer all three.
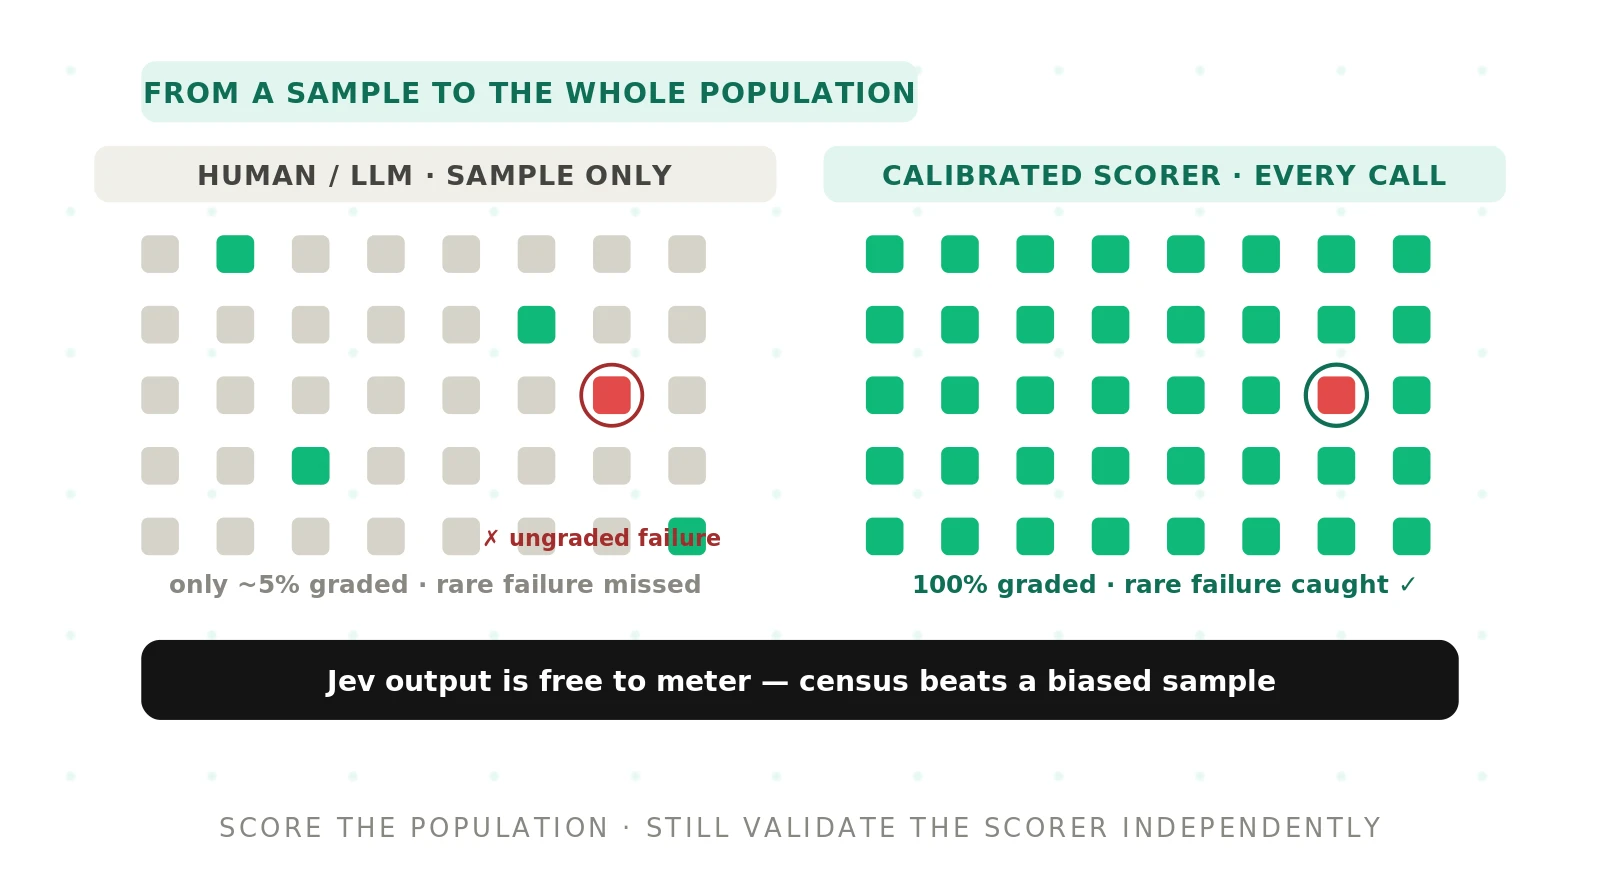
Score Every Call, Not a Sample: Voice-Eval Economics
Scoring every voice agent call now costs cents per 1,000 calls. See the worked math and the insights full coverage unlocks that a 2% sample never can.
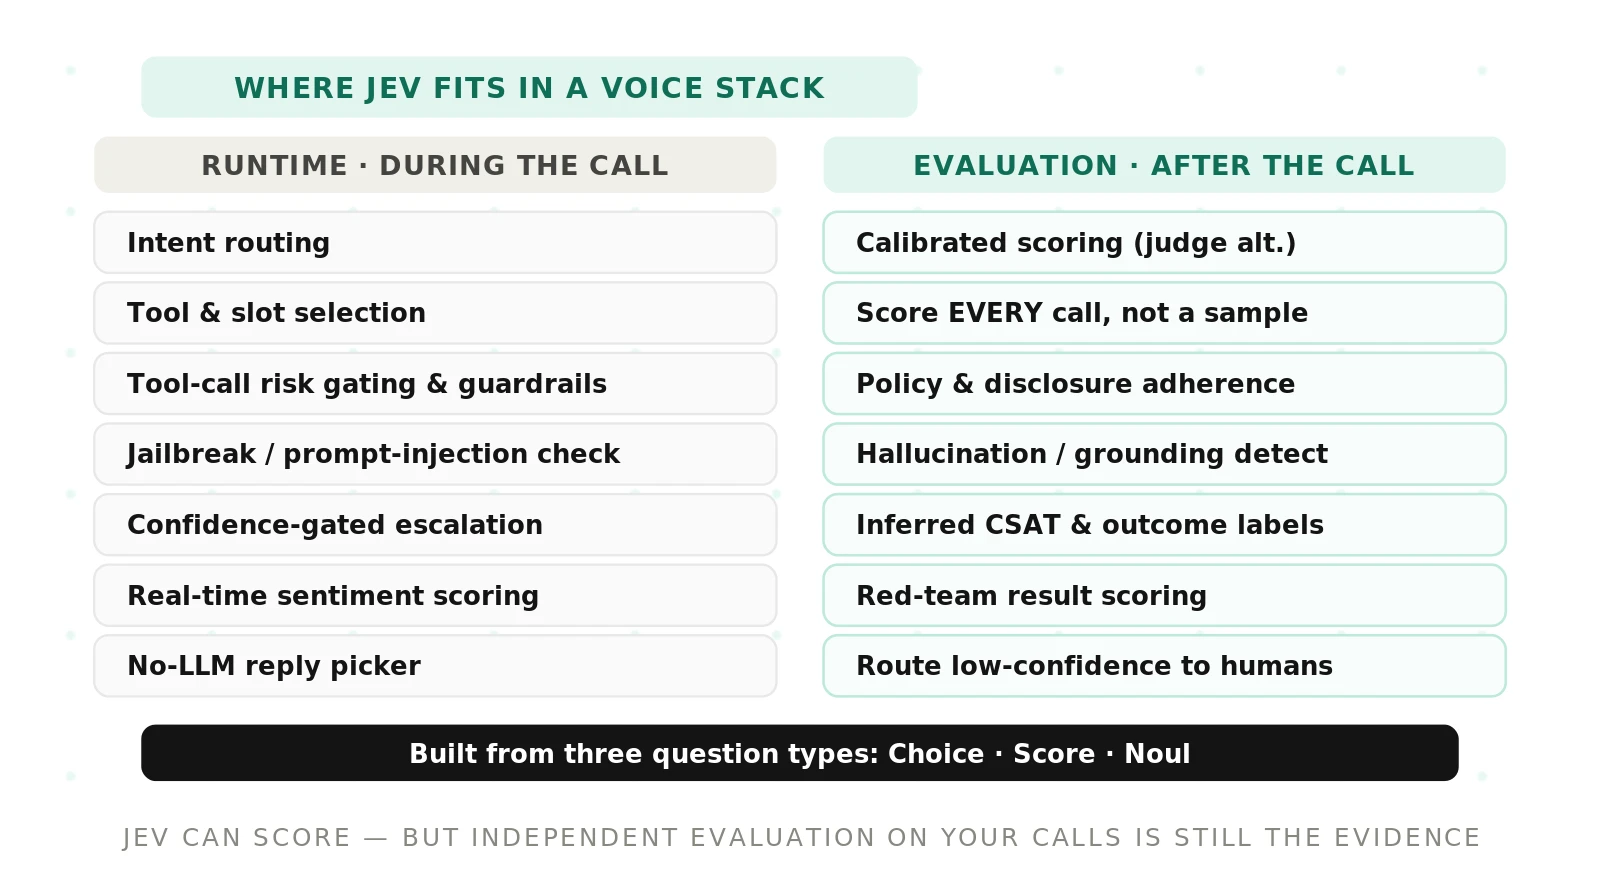
Jev Use Cases for AI Voice Agents, and How to Use Jev
Jev use cases for voice agents: 25 runtime and QA examples, and how to use Jev: send one state with several typed questions and read calibrated answers.