Blog
Page 29 of 59
Answering Machine Detection for Voice Agents: How It Works, Where It Fails, How to Test It
What answering machine detection is, how AMD works, why it hangs up on people, and the scenario set and metrics to test it before go-live.
AI Receptionist for Insurance Agencies: What It Misses and How to Test It
What an AI receptionist for an insurance agency should handle, the quote details it misses, and how to test and evaluate it before go-live.
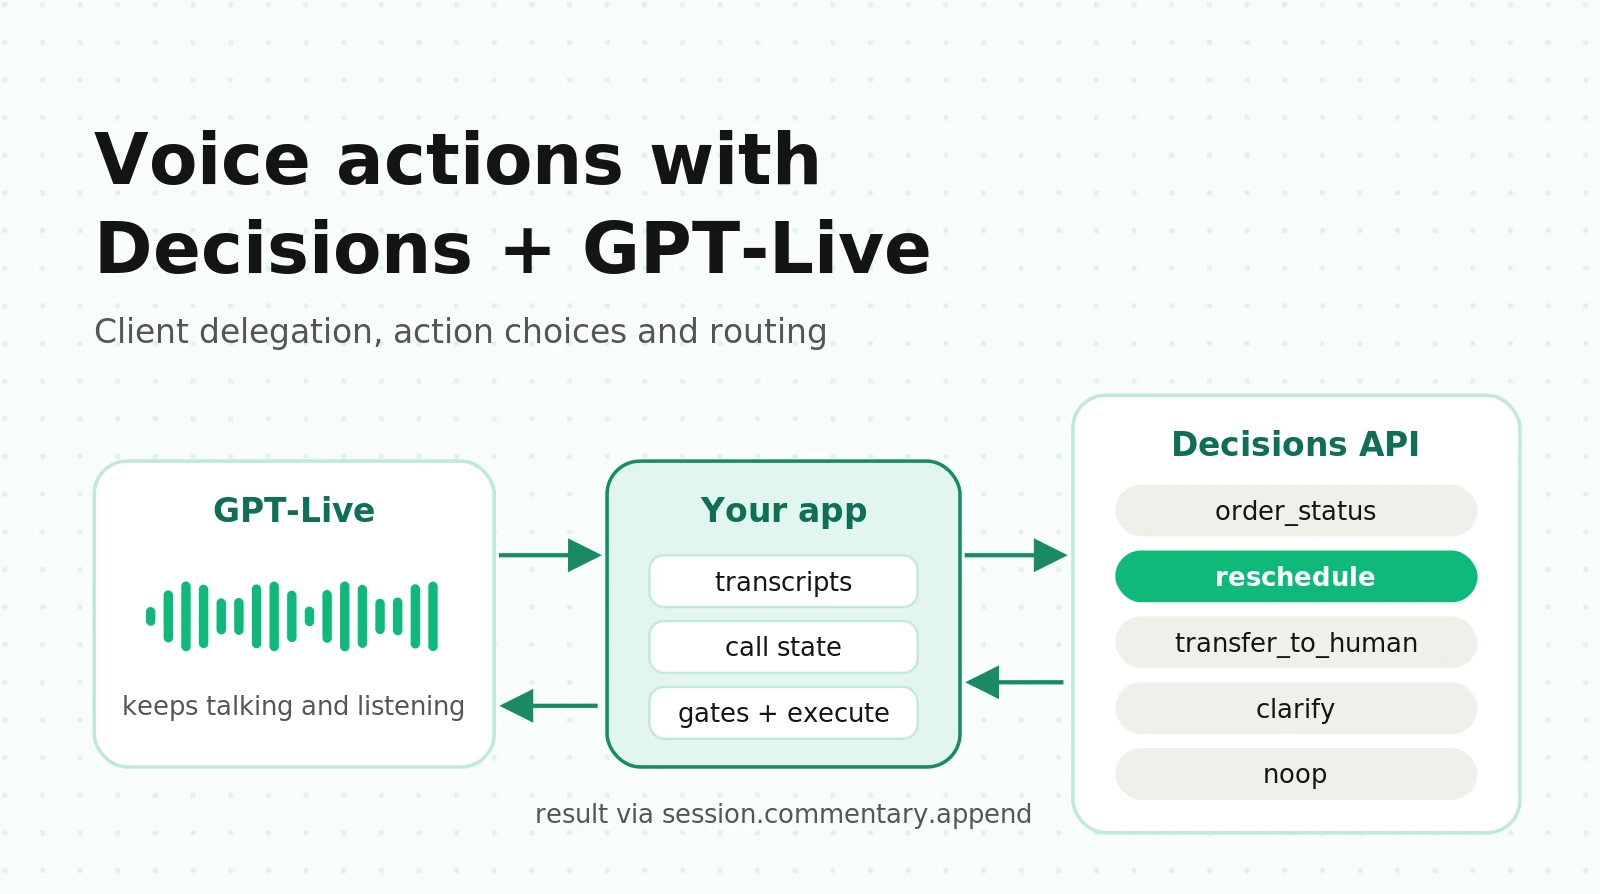
Using OpenAI's Decisions API with GPT-Live in a Voice Agent: Client Delegation, Action Choices and Routing
Wire OpenAI's Decisions API to GPT-Live with client delegation: exact events, a phone action catalog, Python code, safety gates, latency, cost and tests.
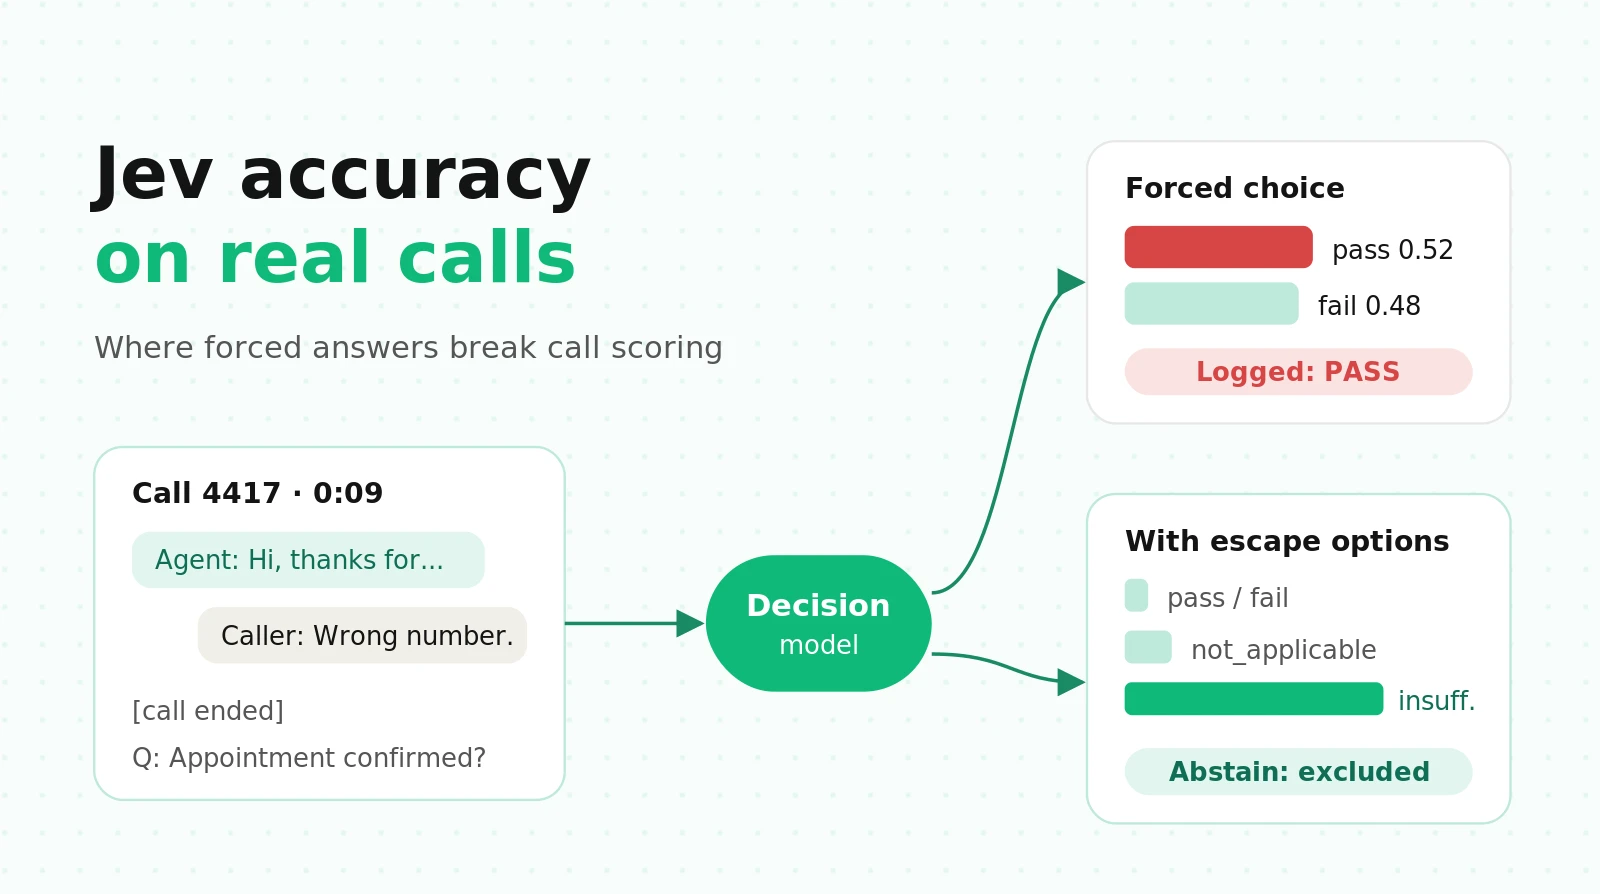
Jev Accuracy in Voice Agent Evals: Where It Fails on Calls
Jev scores clean calls well, but it can't abstain. See where Jev accuracy breaks on real calls, how forced answers skew QA metrics, and how to fix it.
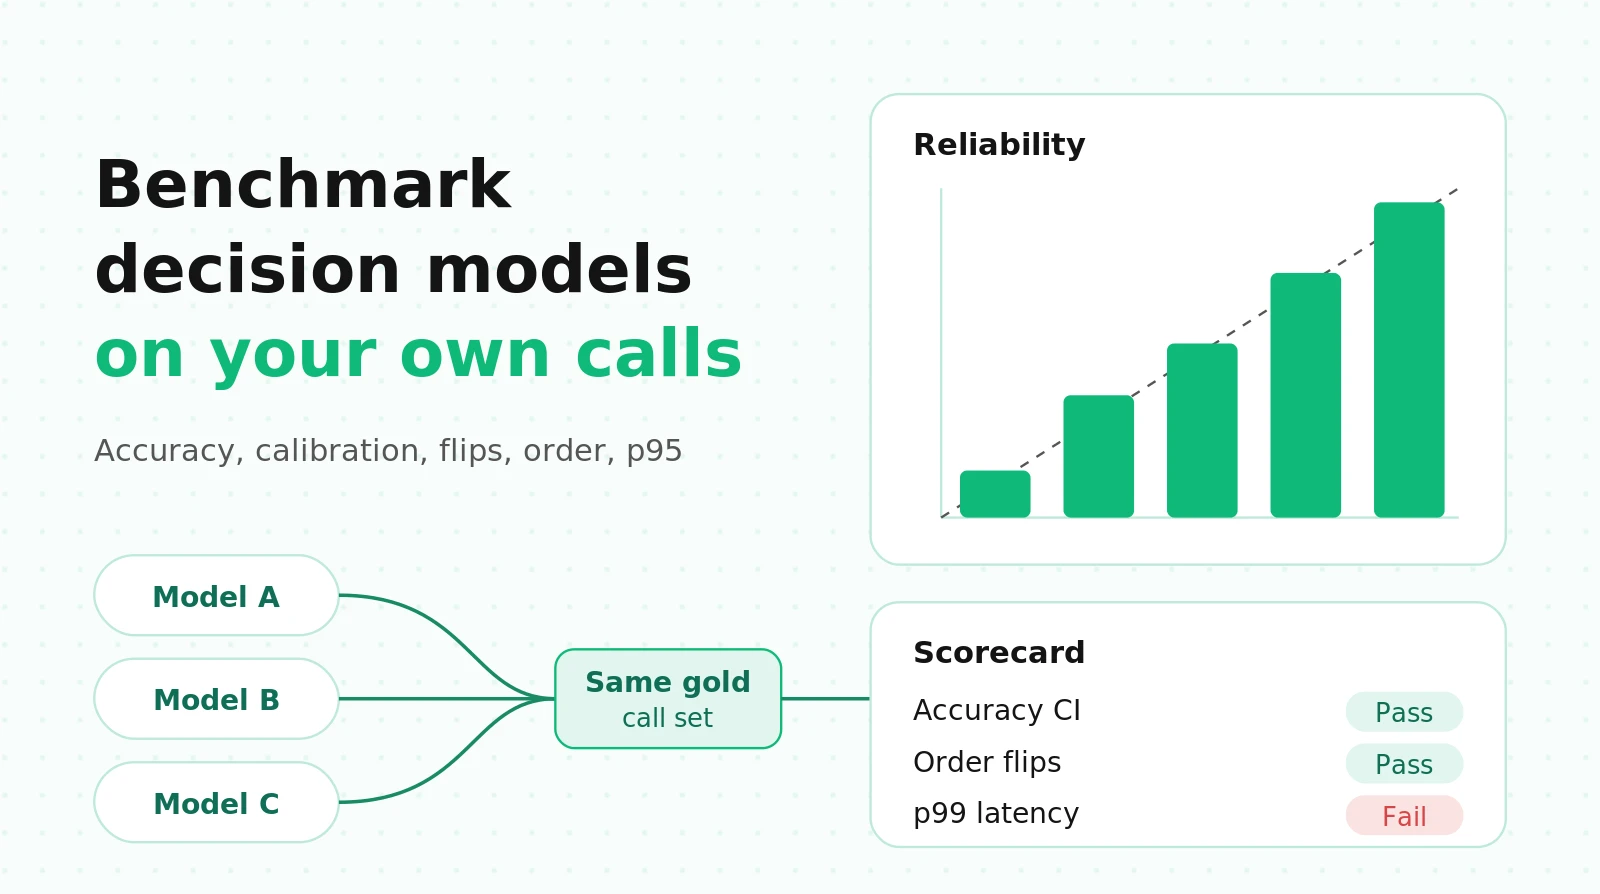
Decision Model Benchmark: How to Test Jev, OpenAI Decisions and LLM Judges on Your Own Calls
A reusable protocol to benchmark Jev, OpenAI Decisions and LLM judges on real calls: sample sizes, kappa, ECE, flips, order tests, p95 latency, cost.
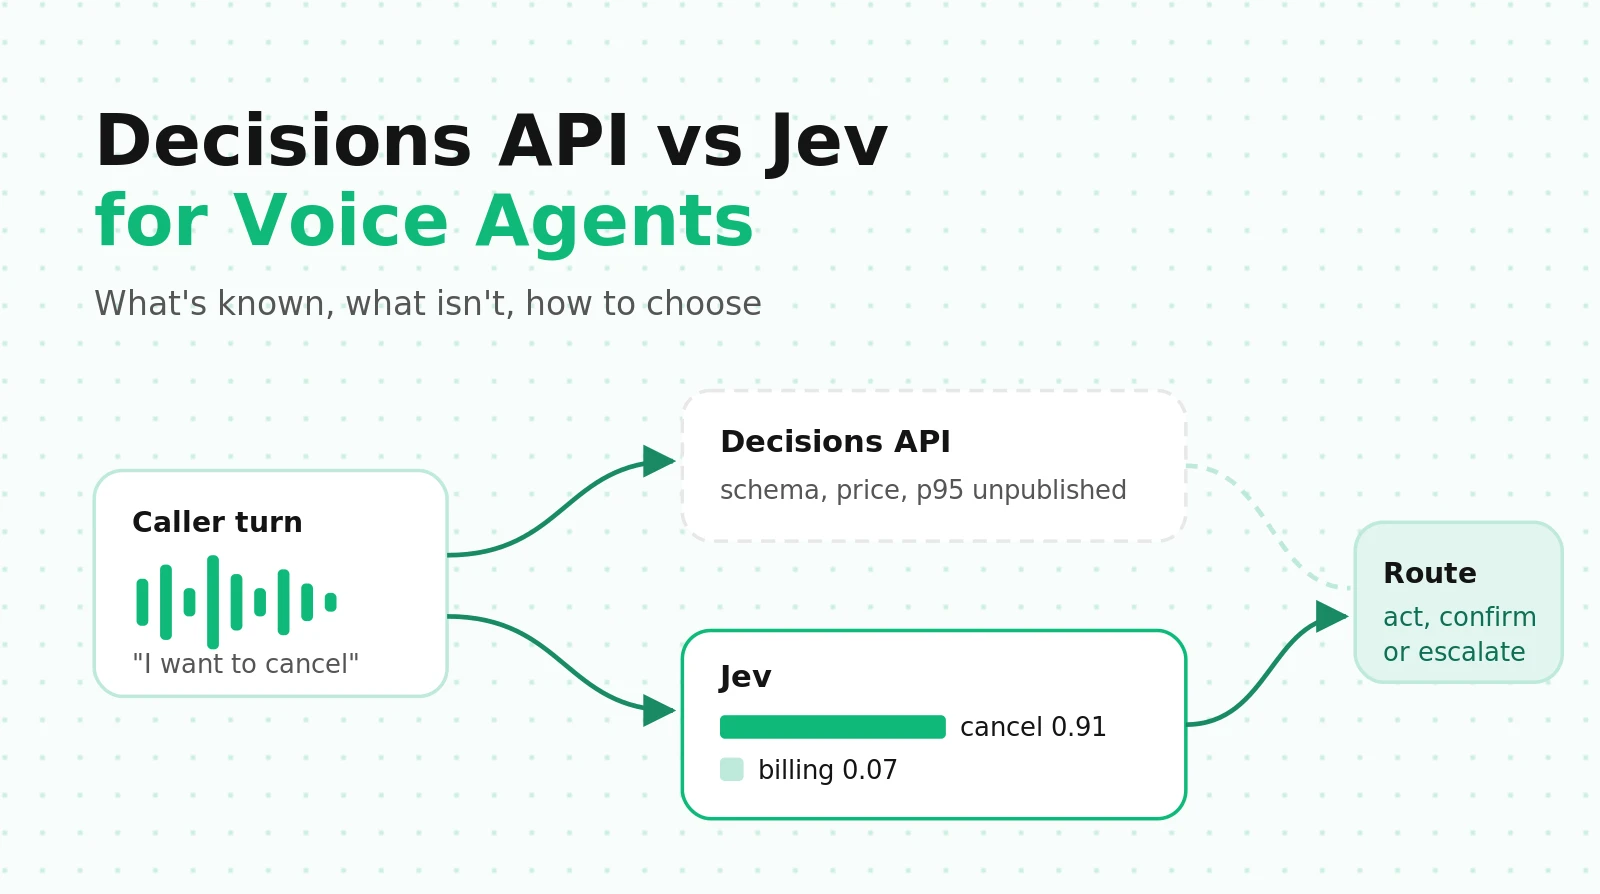
OpenAI Decisions API vs Jev: Which Is Better for Voice Agents? (2026)
Jev is about 2.4x cheaper ($0.042 vs $0.10 per 1M tokens) with published p95 latency. Decisions API adds images, refusals and ZDR. Which fits voice?
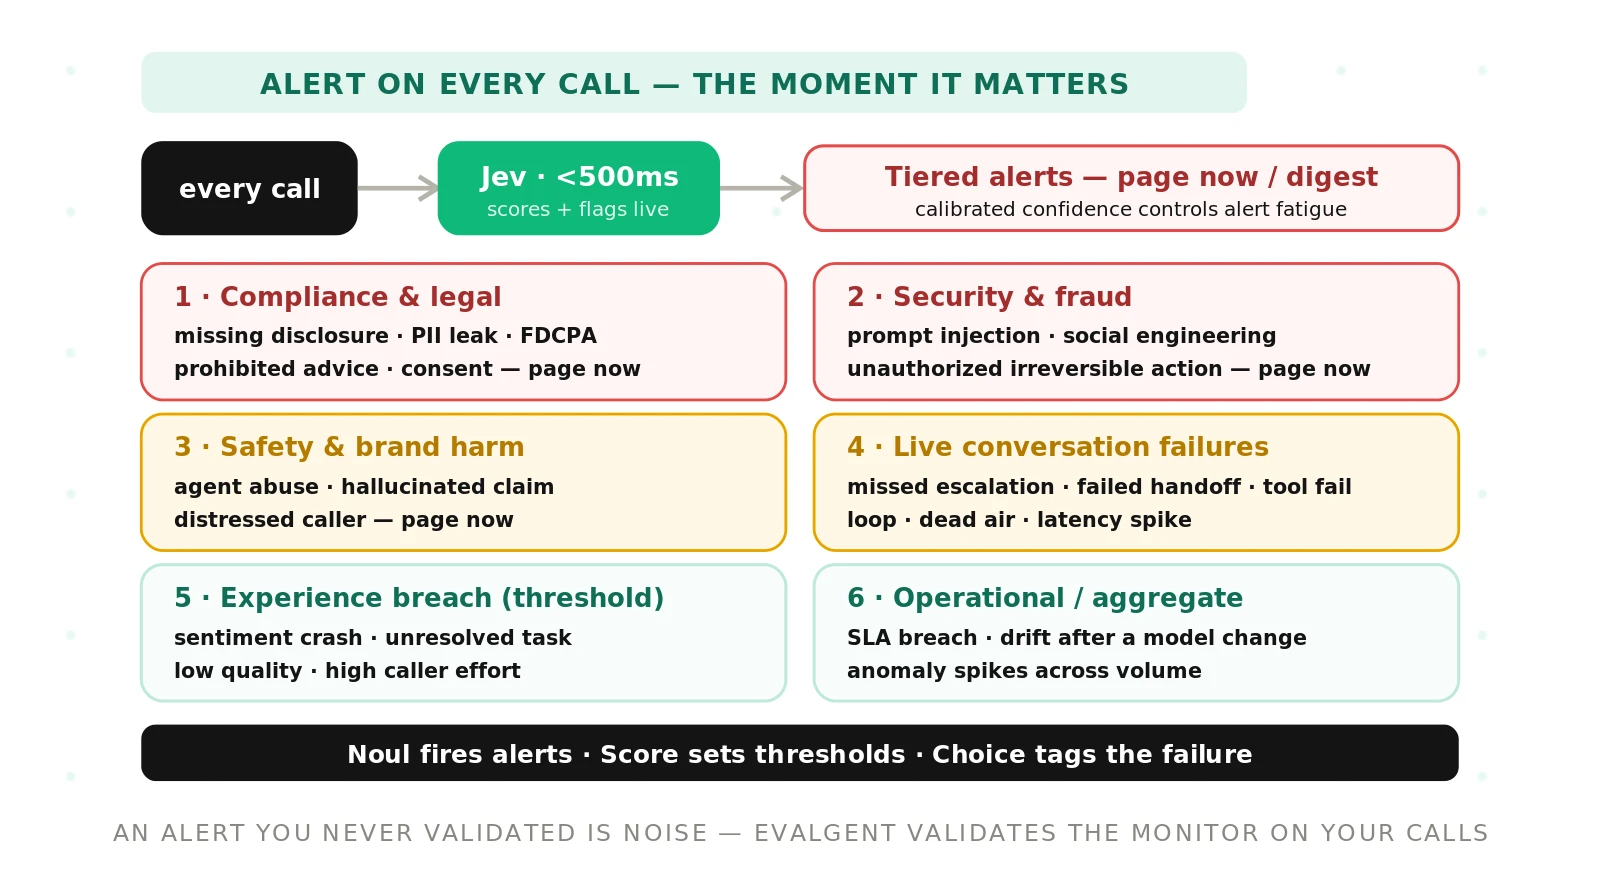
Jev for Voice Agent Call Monitoring
Jev voice agent call monitoring, hands-on: per-turn alert payloads, a Python alert router, cost math at 1M calls, and calibration checks that curb fatigue.
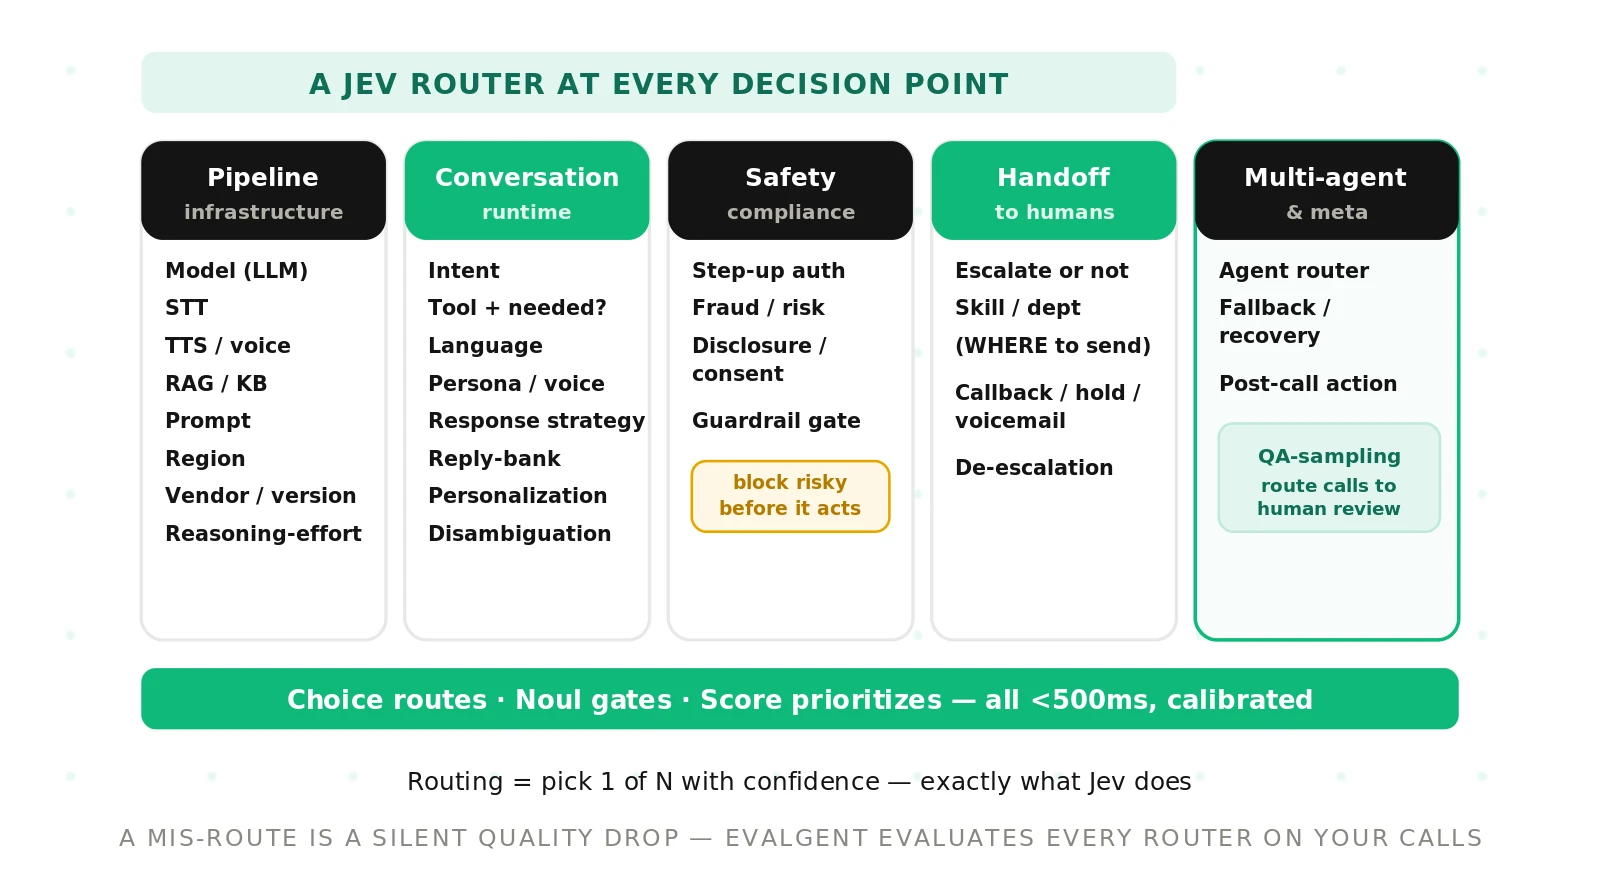
Routing Use Cases of Jev in AI Voice Agents
Jev routing use cases for voice agents: a 30-router catalog, a real Choice response decoded, reusable Python, and how to measure routing accuracy on calls.
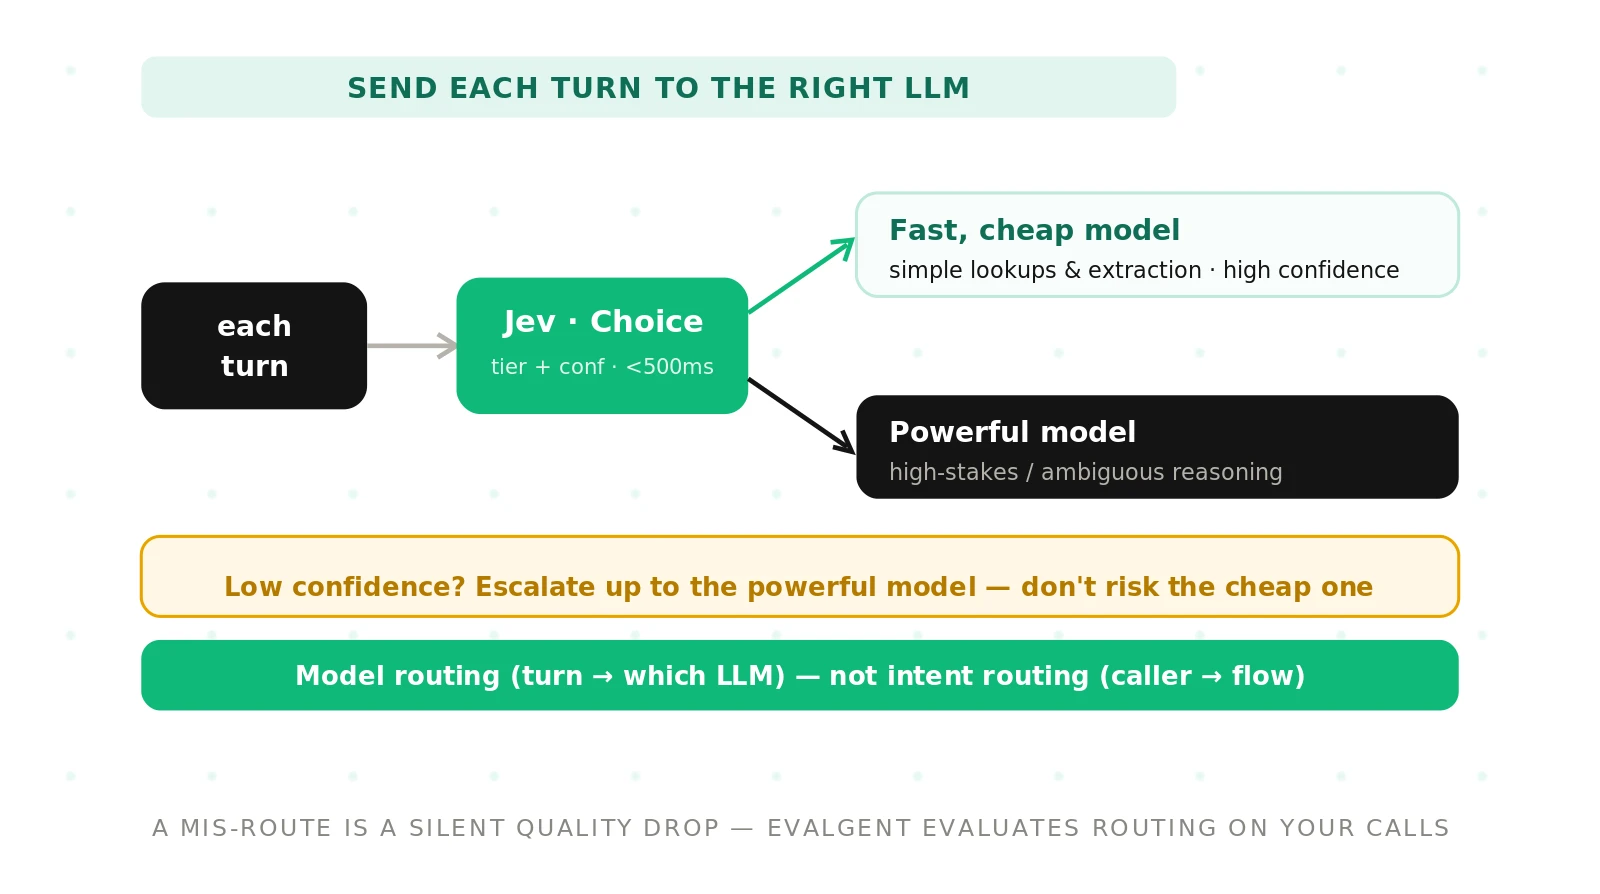
Jev Model Routing: Use Jev as a Model Router for Voice Agents
Jev model routing: use Jev as a model router that sends each voice turn to the right LLM. LangChain and API code, confidence gating, cost math, and evals.