Blog
Page 59 of 59
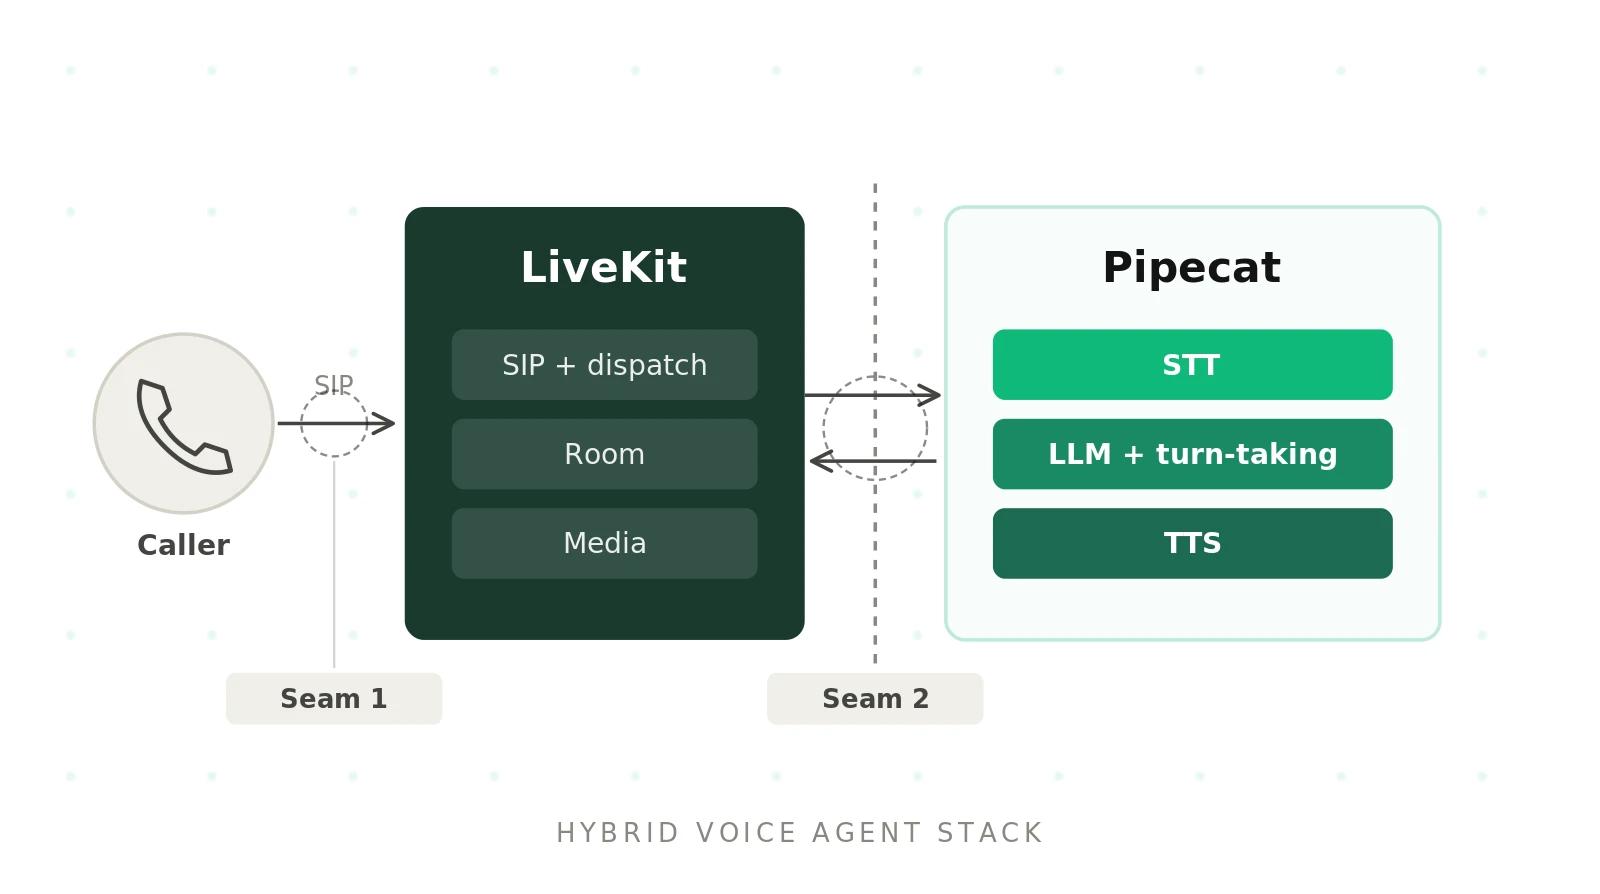
Can You Use LiveKit and Pipecat Together? The Hybrid Voice Agent Stack
Yes, LiveKit and Pipecat work together. A build guide for Pipecat on LiveKit transport: SIP dispatch, tokens, outbound calls, and the seams that break.
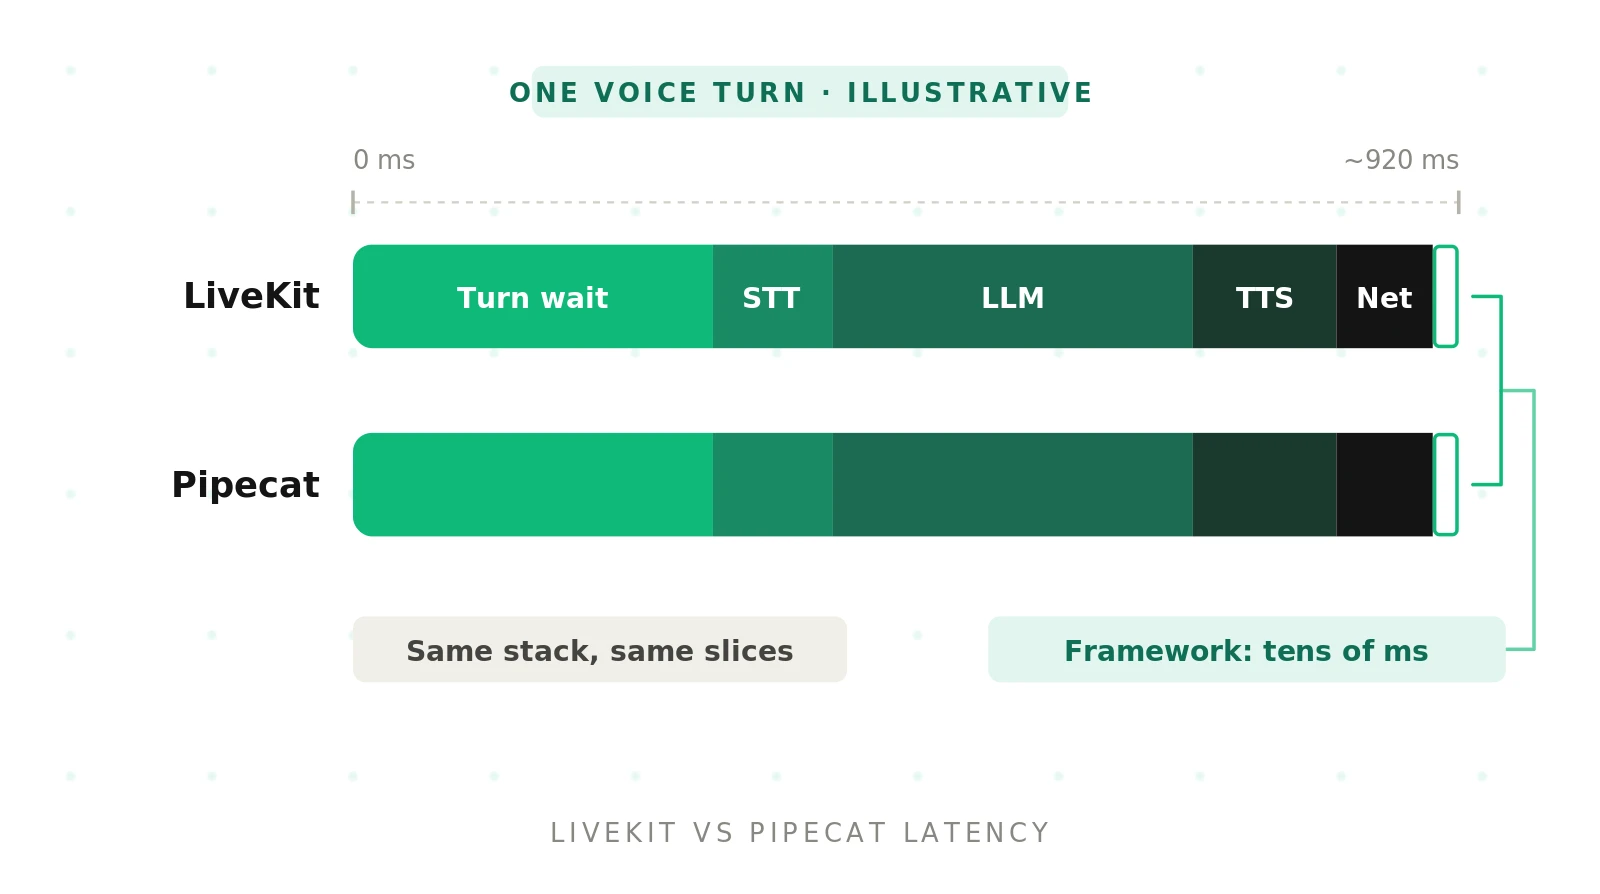
LiveKit vs Pipecat Latency: Where the Milliseconds Actually Go
LiveKit vs Pipecat latency, turn by turn: why the framework is a small slice, which knobs move p95, and how to cut delay without cutting callers off.
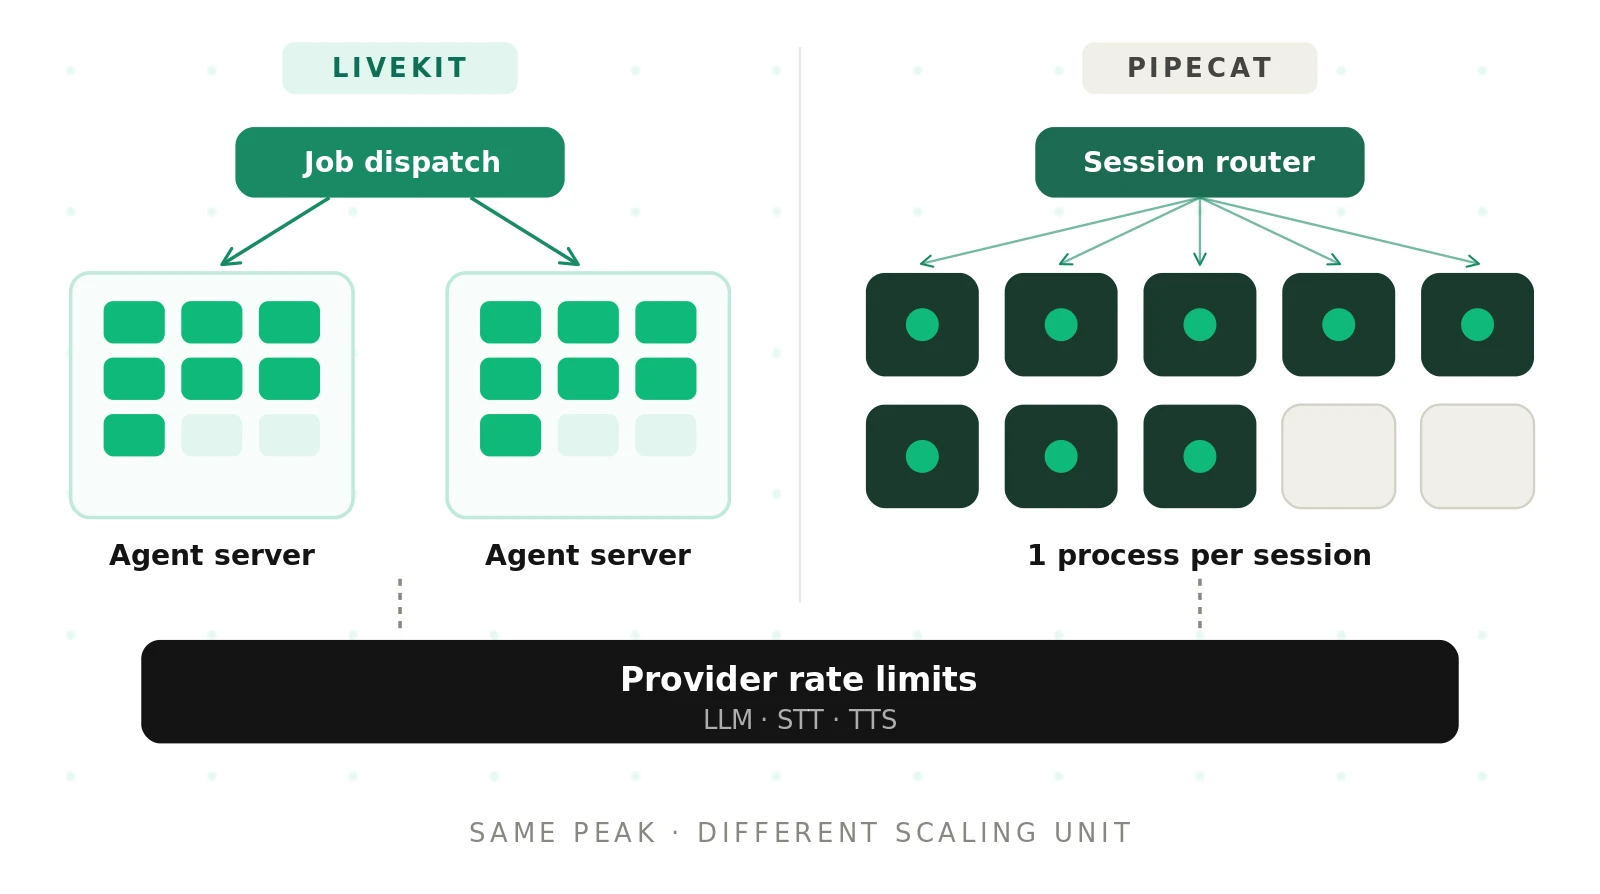
LiveKit vs Pipecat at Scale: Concurrency, Workers, and Production Load
LiveKit vs Pipecat scaling from 10 to 10,000 calls: agent servers vs per-session processes, cold starts, draining, rate limits, and a capacity worksheet.
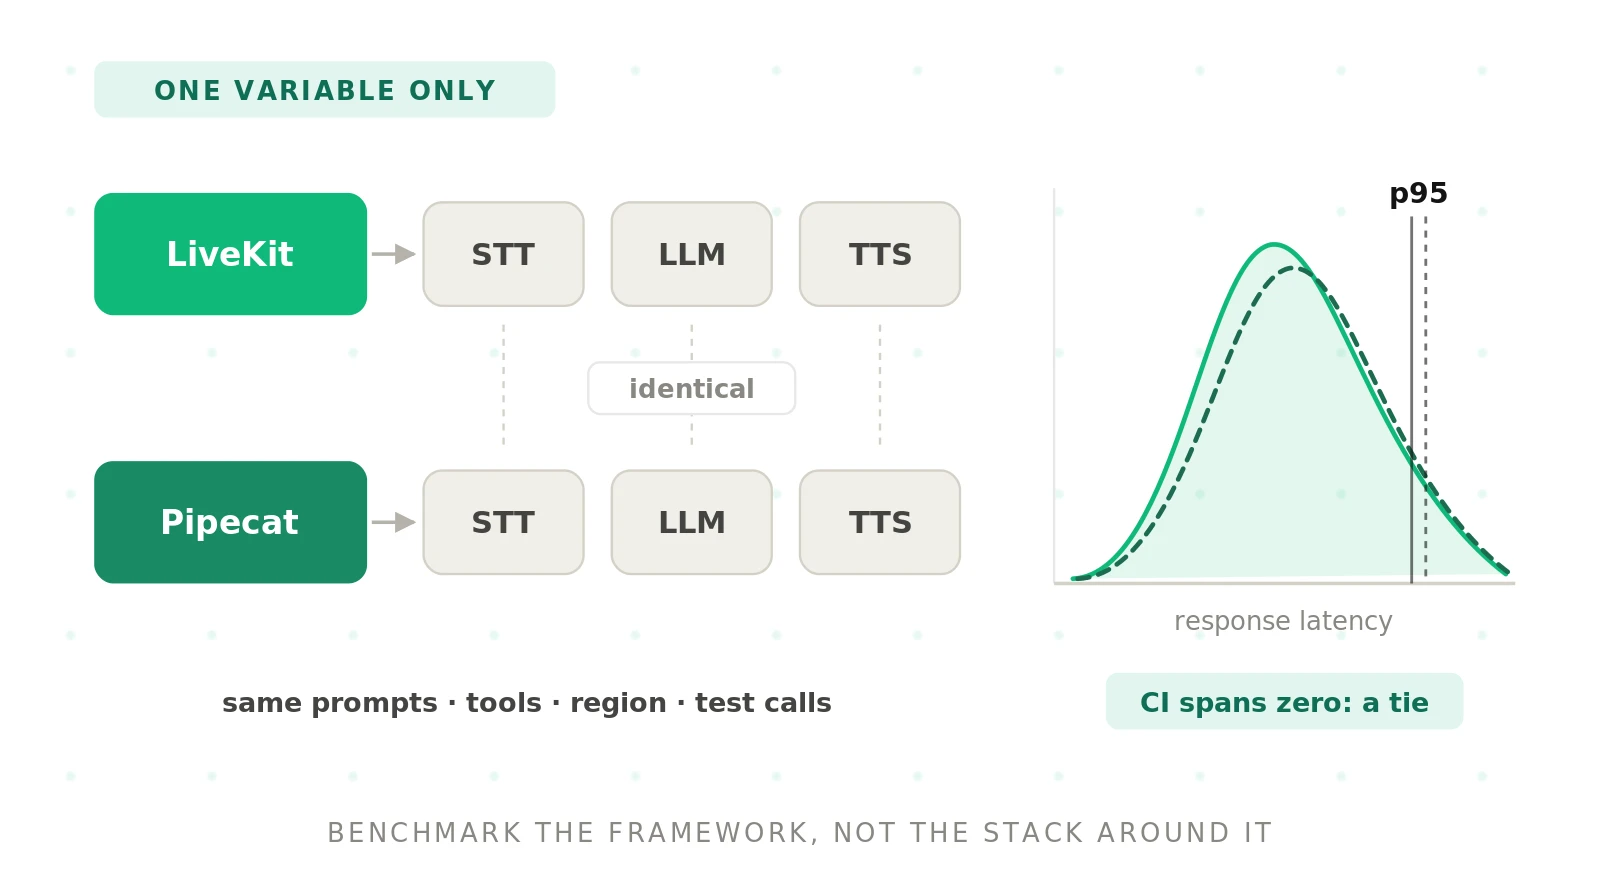
How to Benchmark LiveKit vs Pipecat on Your Own Workload
Generic LiveKit vs Pipecat benchmarks mislead. Hold STT, LLM, TTS, prompts, and region constant, vary only the framework, and measure p95 and turn quality.
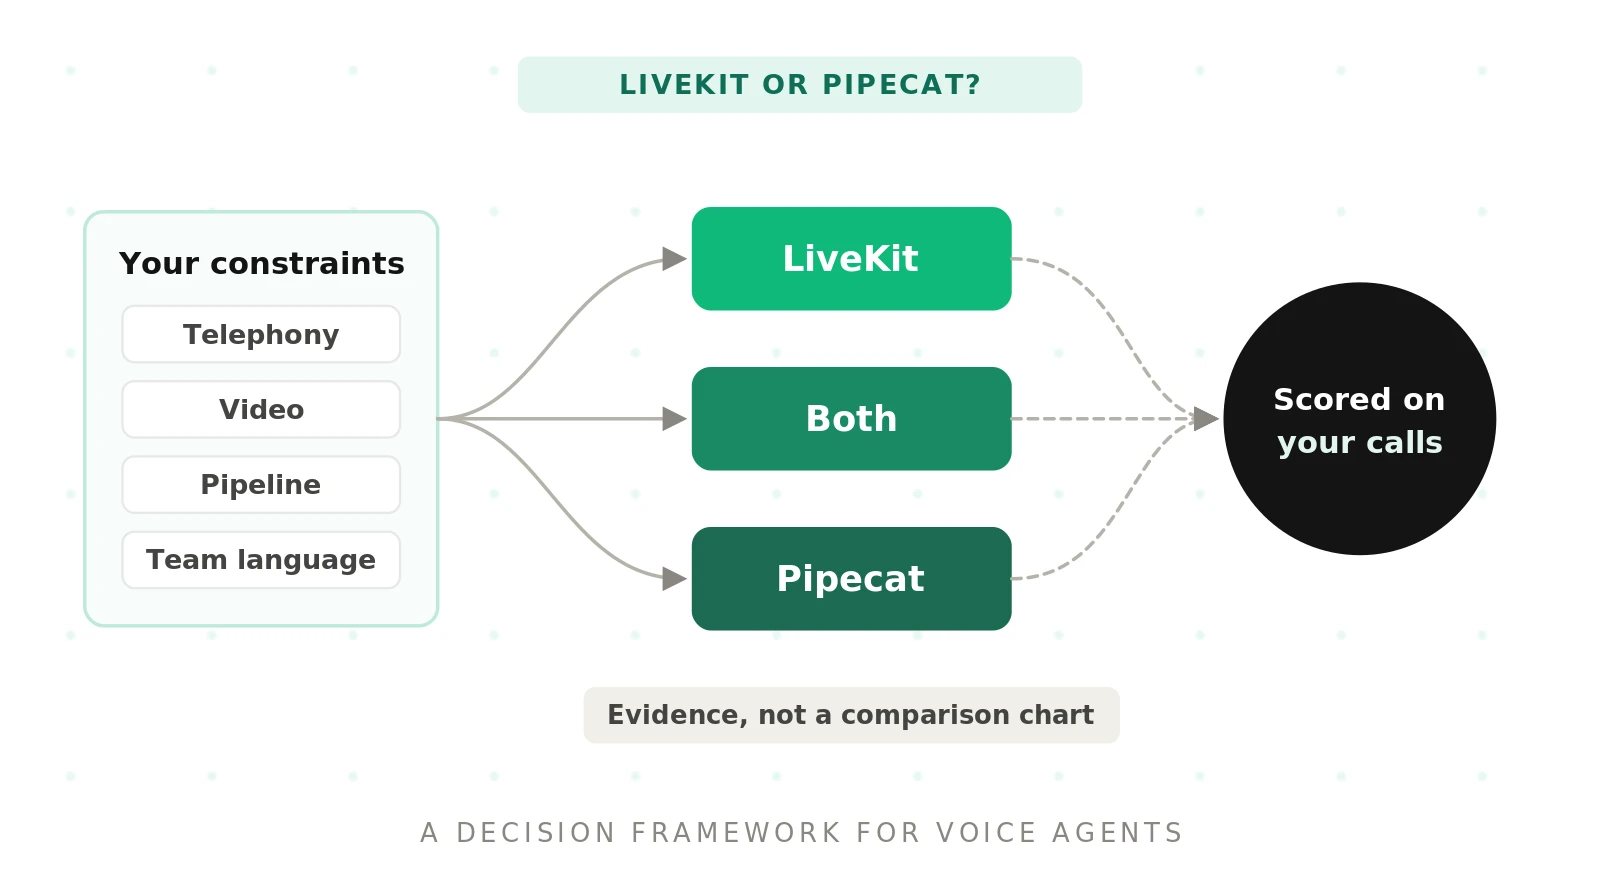
How to Choose Between LiveKit and Pipecat (A Decision Framework)
LiveKit or Pipecat? A 10-criterion decision framework with a weighted scoring worksheet, a decision tree, three worked archetypes, and a two-week POC plan.
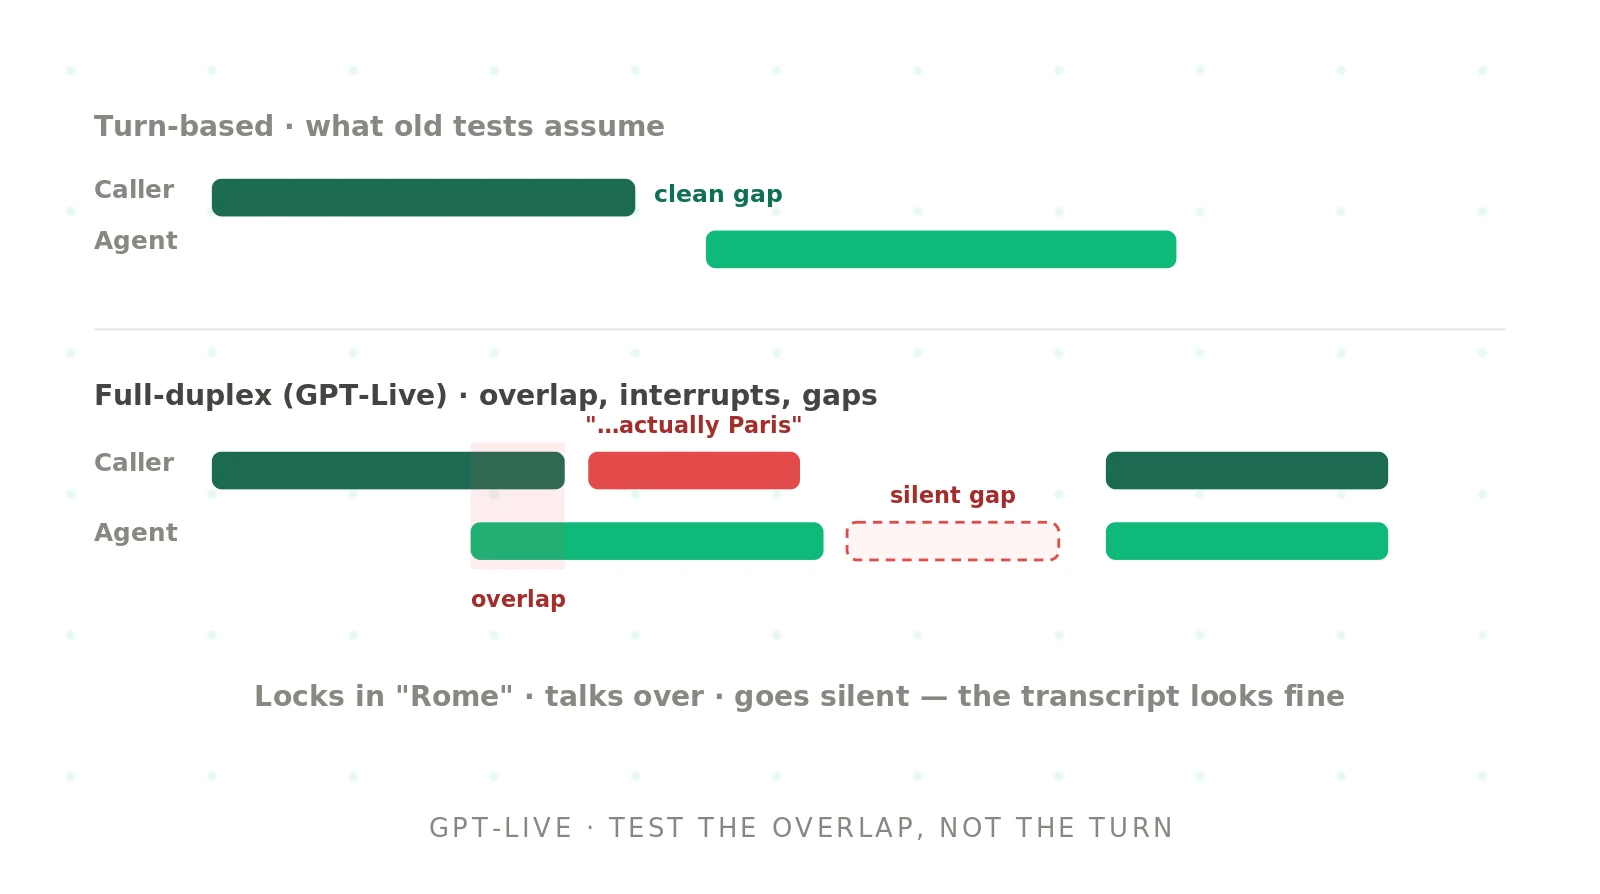
How to test GPT-Live voice agents: a complete gpt-live-1 API test plan
A hands-on test plan for GPT-Live voice agents on the gpt-live-1 API: turn-taking, barge-in, tool-call arguments, latency, cost per call, and regressions.
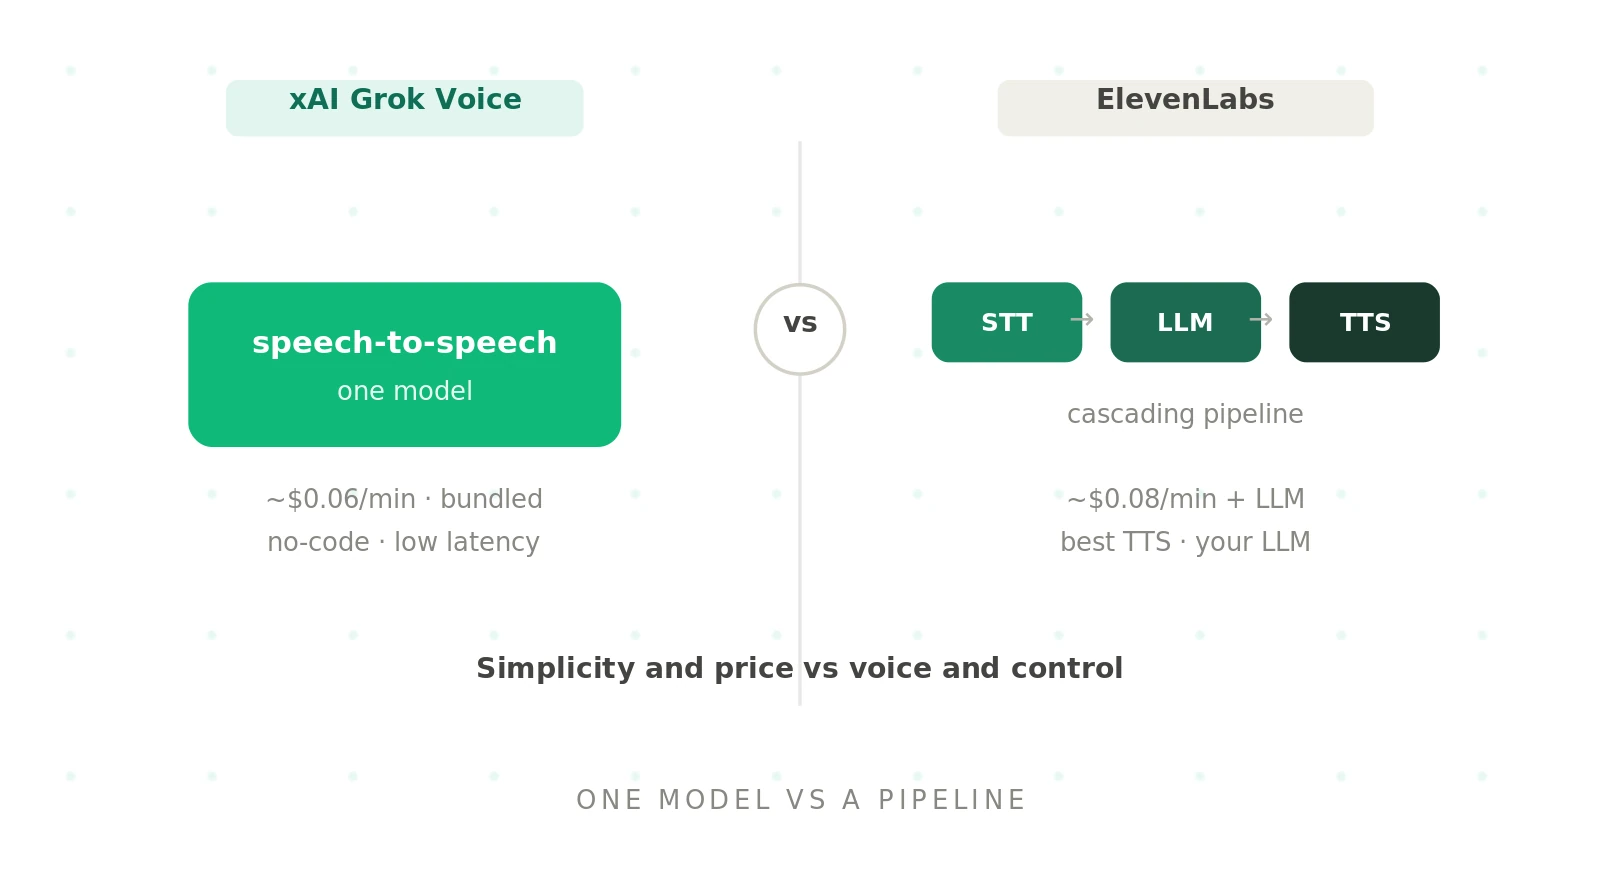
xAI Voice Agent vs ElevenLabs: Grok Voice Agent Builder pricing per minute, features, and which to choose (2026)
xAI Grok Voice Agent vs ElevenLabs in 2026: cost per minute, Think Fast 2.0, voices, languages, SIP telephony, tools, compliance, and a fair test plan.
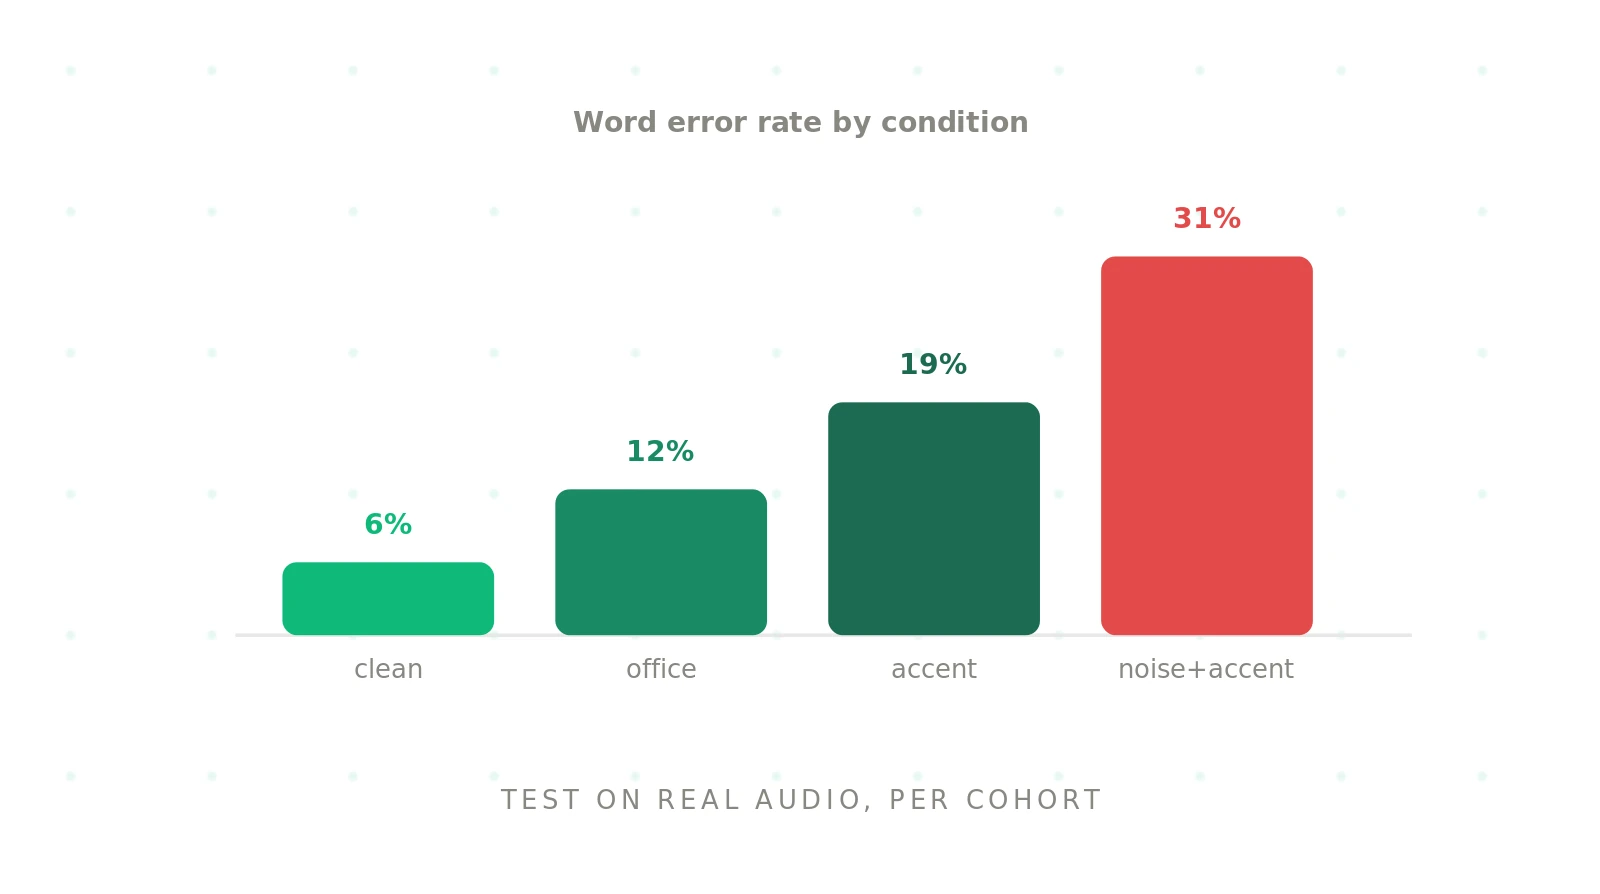
STT evaluation: how to test speech-to-text for voice agents (2026)
STT evaluation for voice agents: WER, entity accuracy, keyterm recall, latency and endpointing, plus normalization rules and a Python harness you can run.
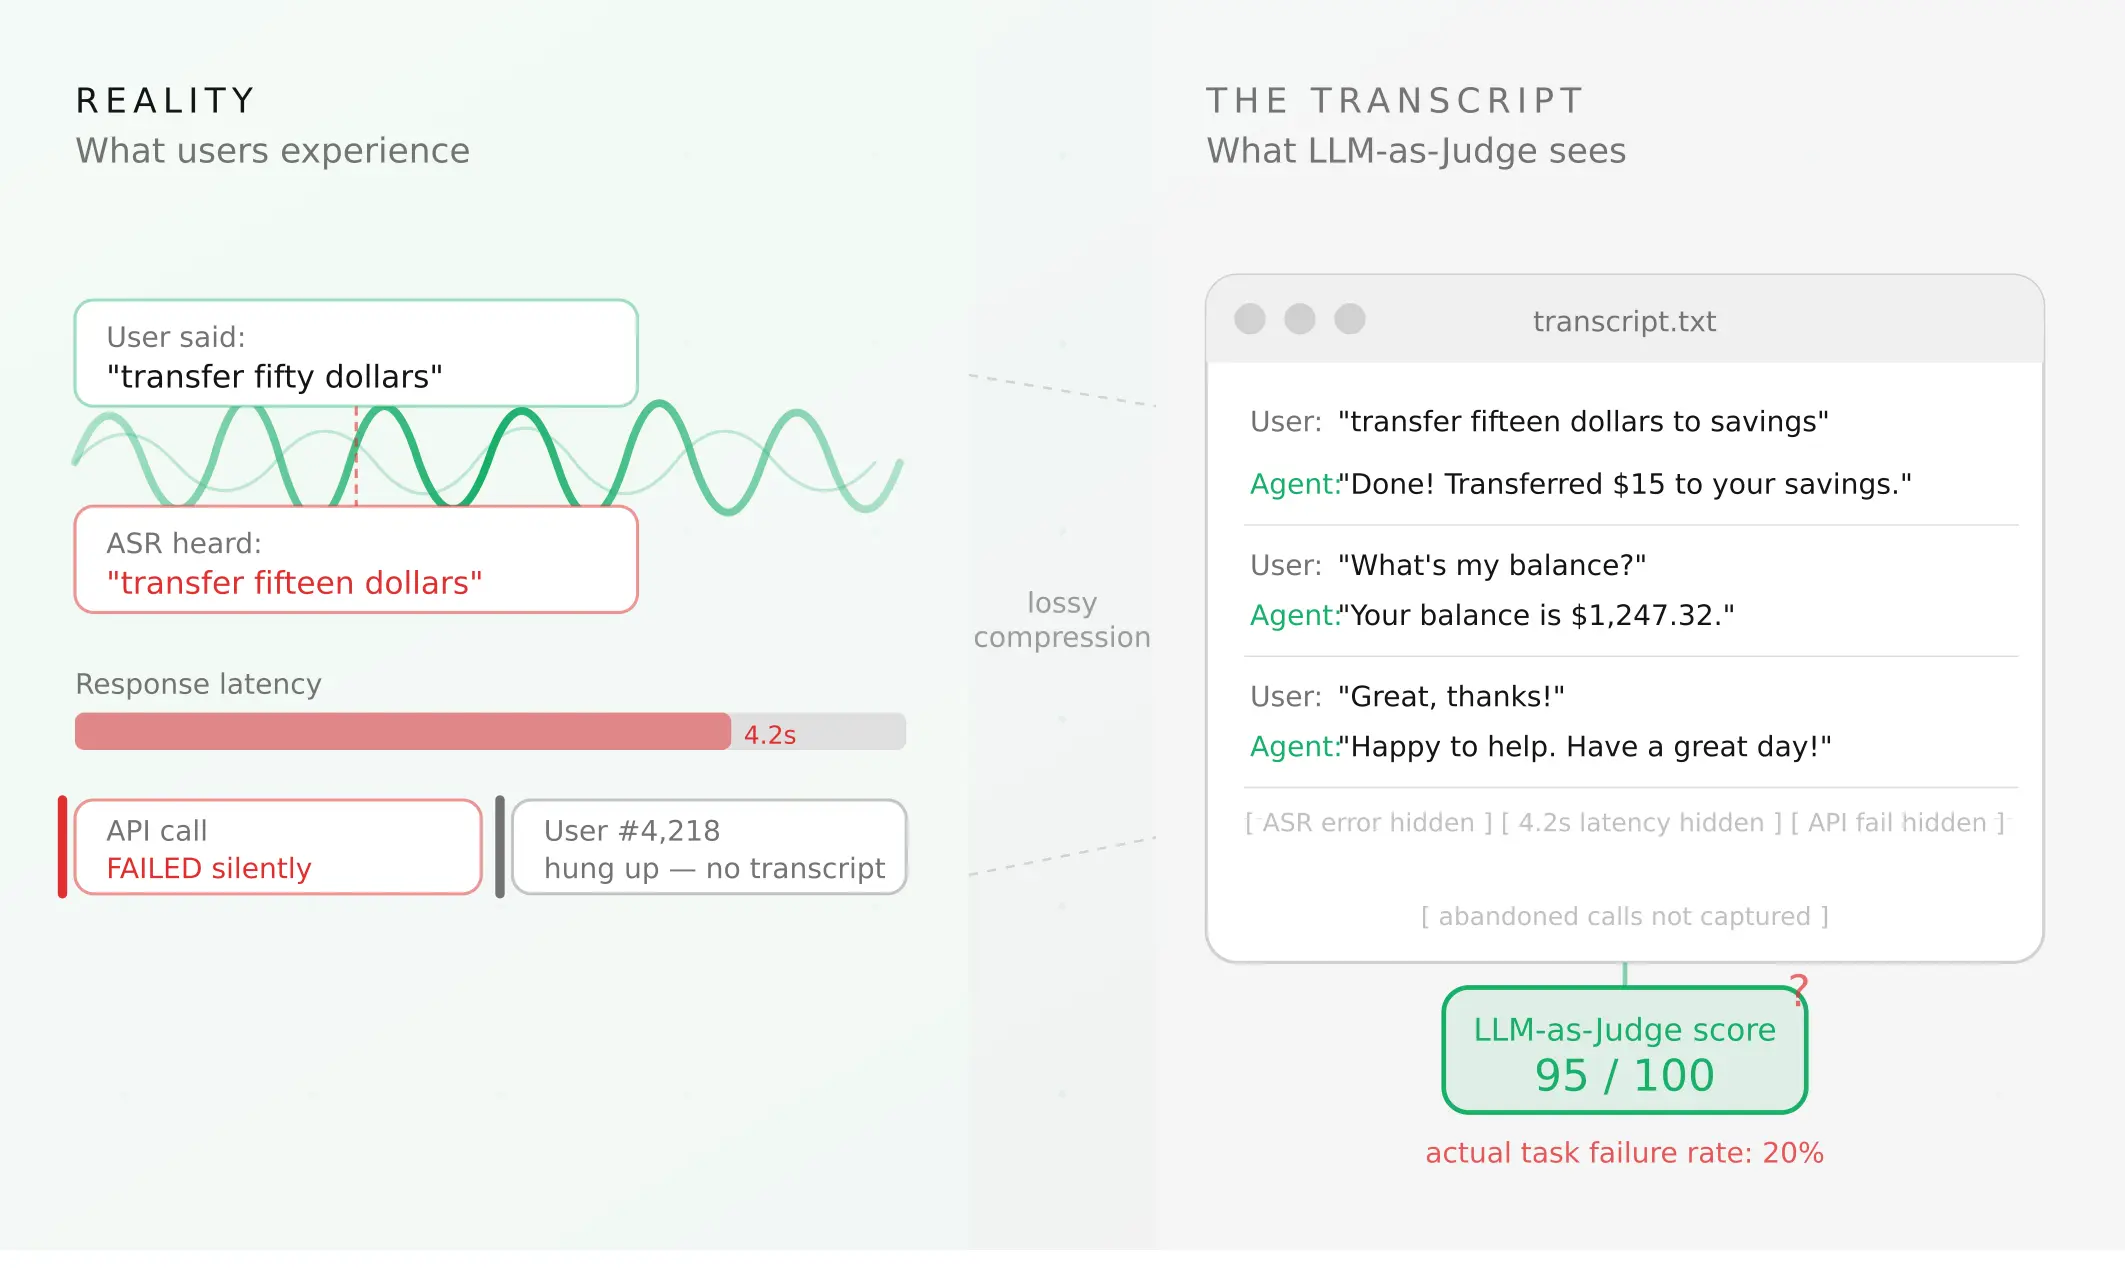
LLM-as-a-judge limits in voice AI: 9 failure modes and how to catch them
LLM-as-a-judge misses real voice agent failures. See 9 failure modes backed by research, how to catch false positives, and the fixes that hold up.