Blog
Page 20 of 47
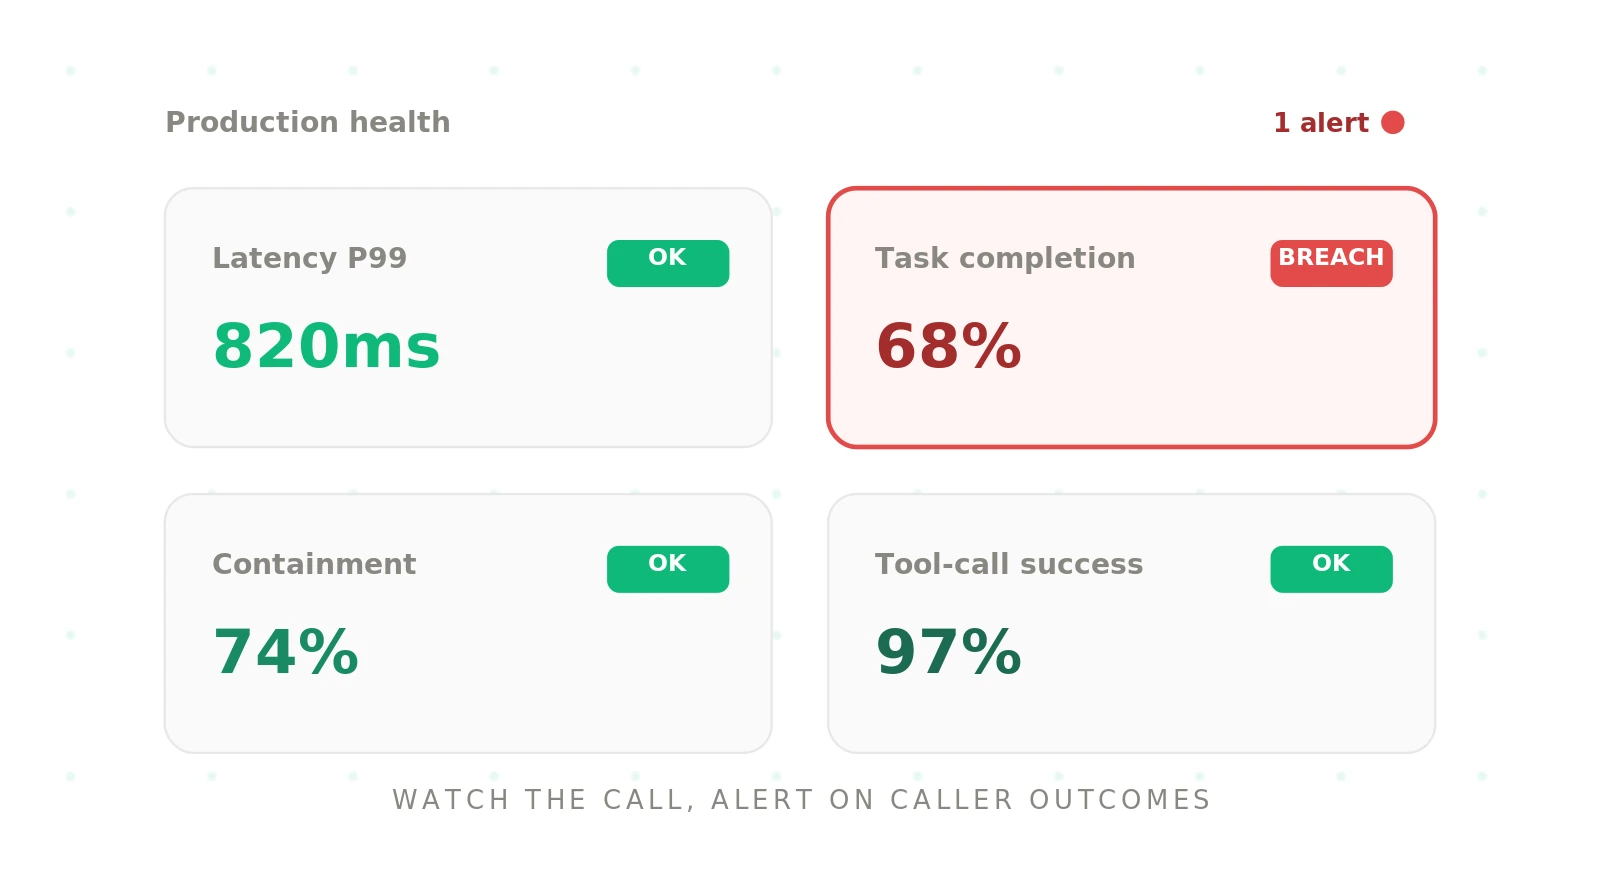
How to Monitor Voice Agents in Production: Tool Failures, Latency Spikes and Dead Air
How to monitor voice agents in production on LiveKit or Pipecat: tool-call failure rates, p95 latency per segment, dead-air detection and burn-rate alerts.
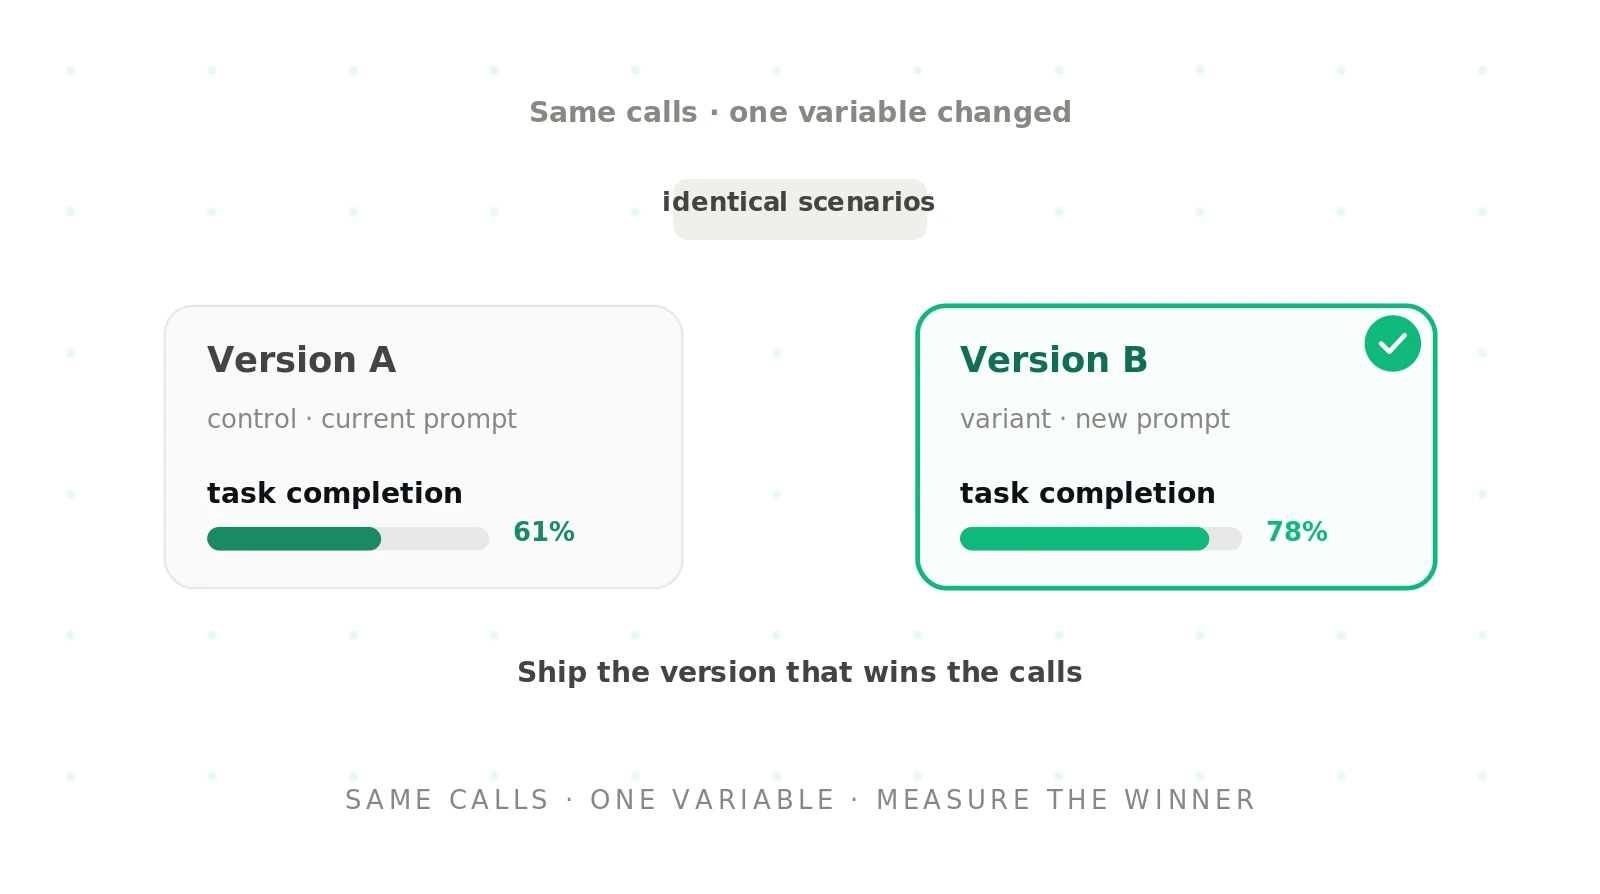
How to A/B Test Voice Agent Prompts: Offline Pairs, Live Splits, and the Sample-Size Math
How to A/B test voice agent prompts on LiveKit or Pipecat: paired offline runs, caller-level live splits, blind judging, and sample-size math that holds.
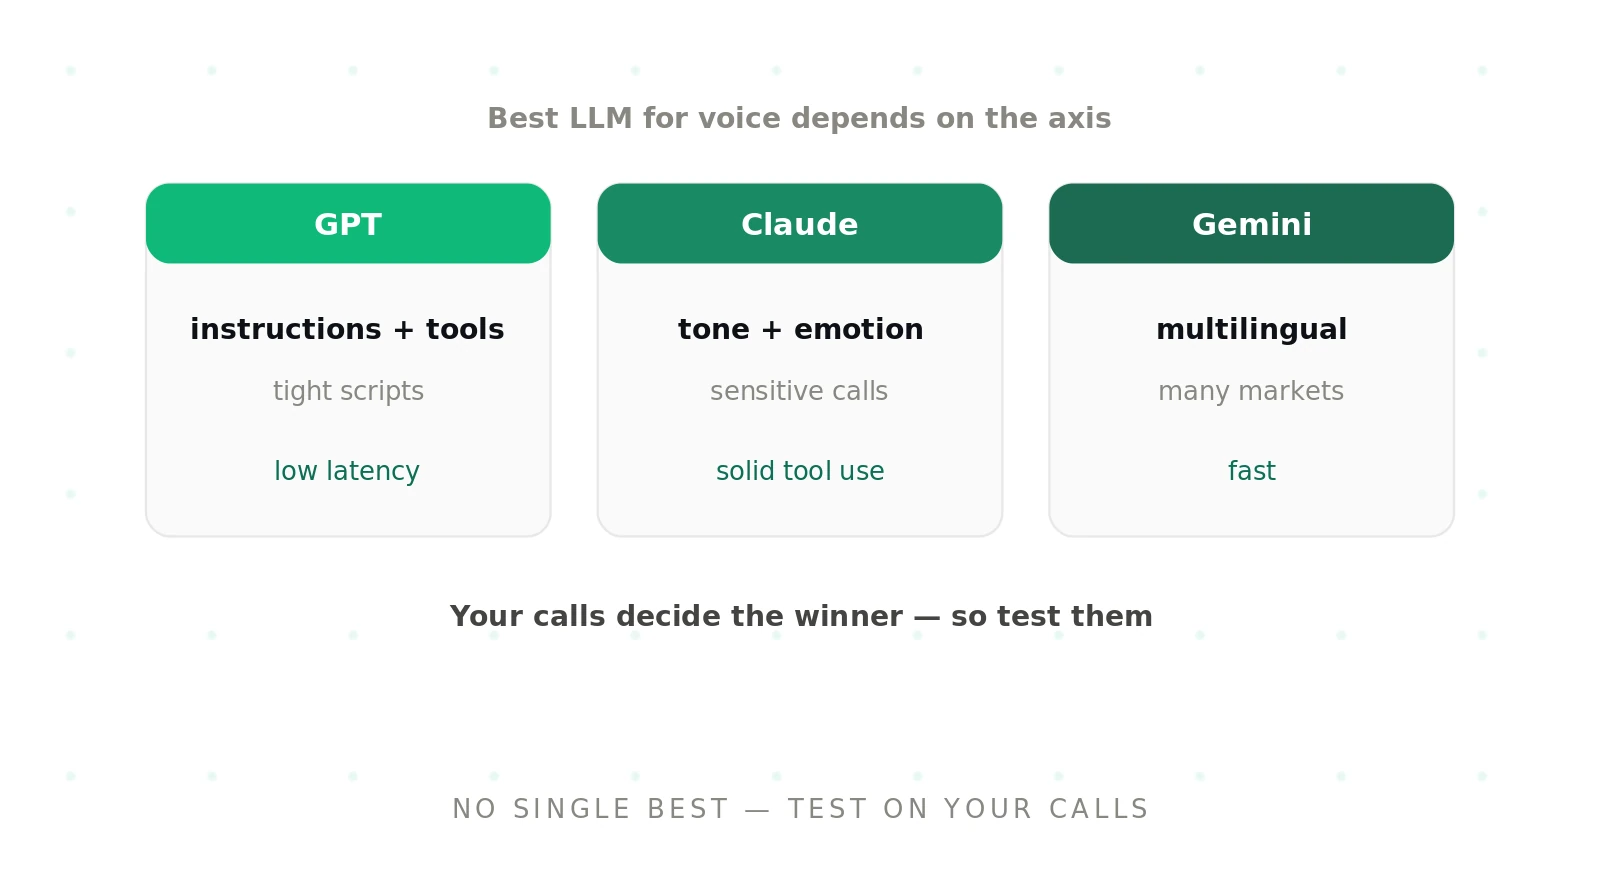
Best LLM for voice agents (October 2026): latency, tool calling, cost per minute
Best LLM for voice agents, October 2026: GPT-6, Claude, Gemini, Grok and open models compared on first-token latency, tool calling and cost per minute.
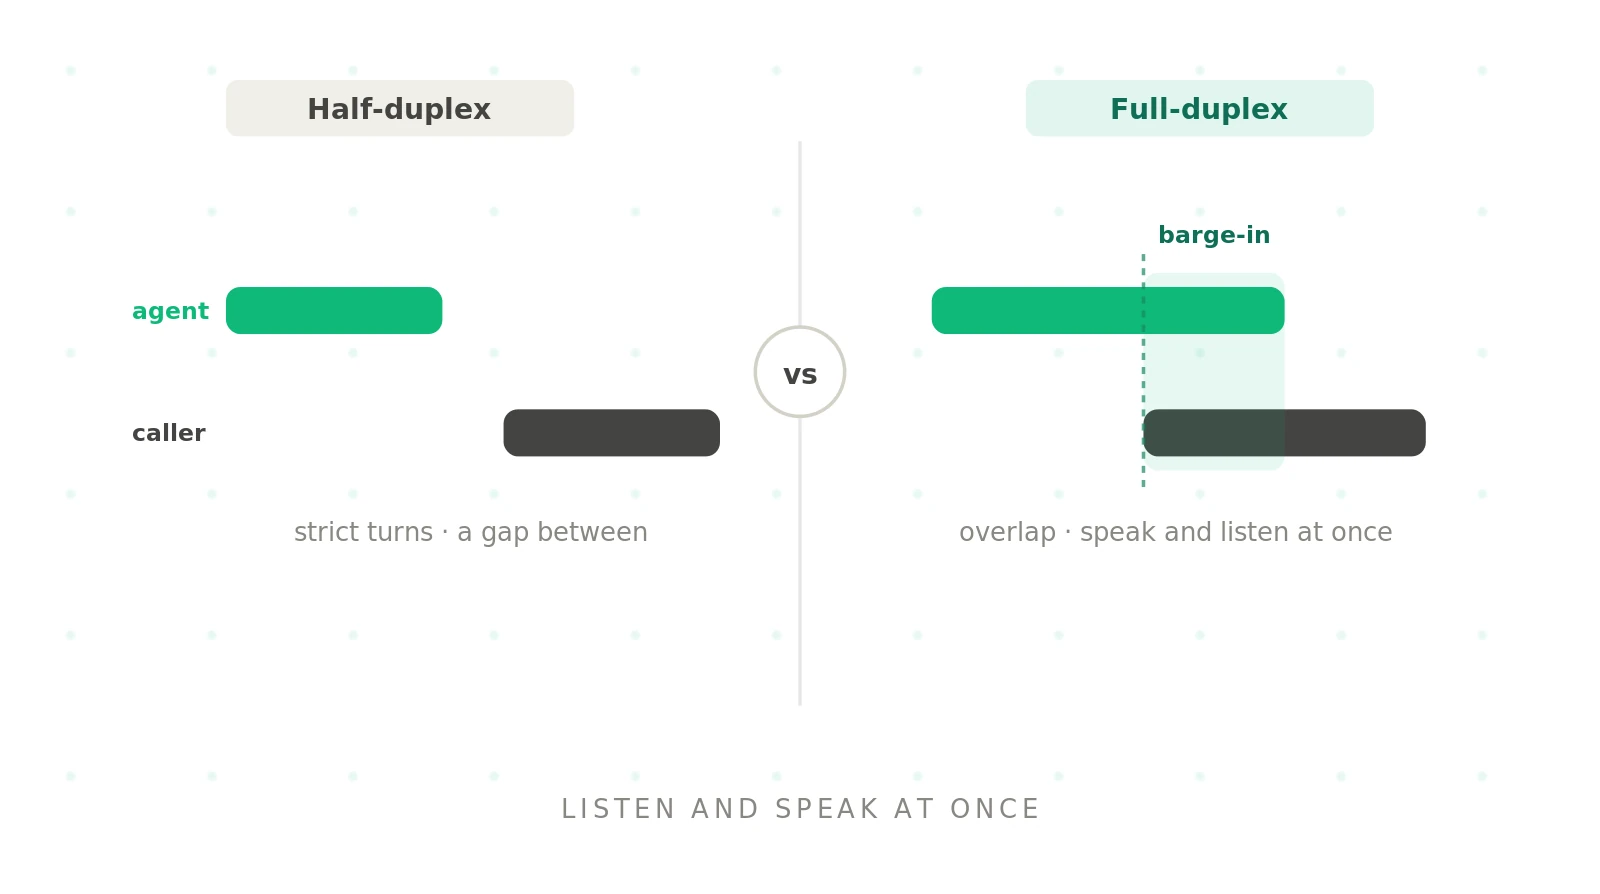
Full-duplex voice agents: turn-based vs full-duplex, models, testing
Turn-based vs full-duplex voice agents: one waits for silence, the other listens while it speaks. Compare GPT-Live, Moshi and PersonaPlex, and how to test.
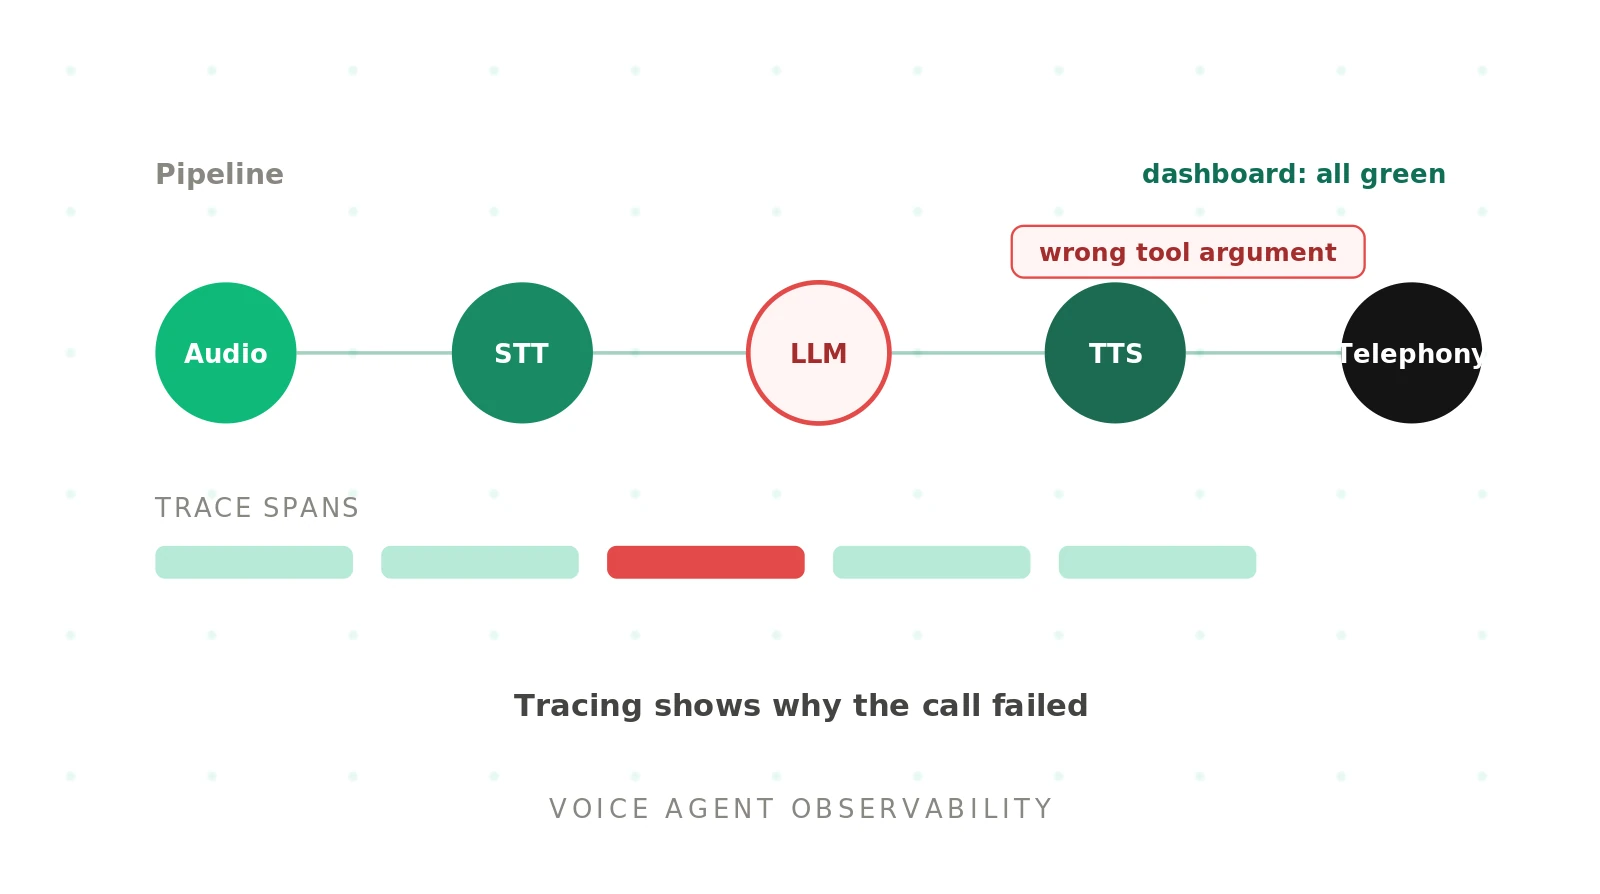
Voice agent observability tool: a 14-point buyer's and builder's checklist
What a voice agent observability tool must capture: per-turn traces, stereo audio, signal health, caller-heard latency, audit trails. Scored, testable.
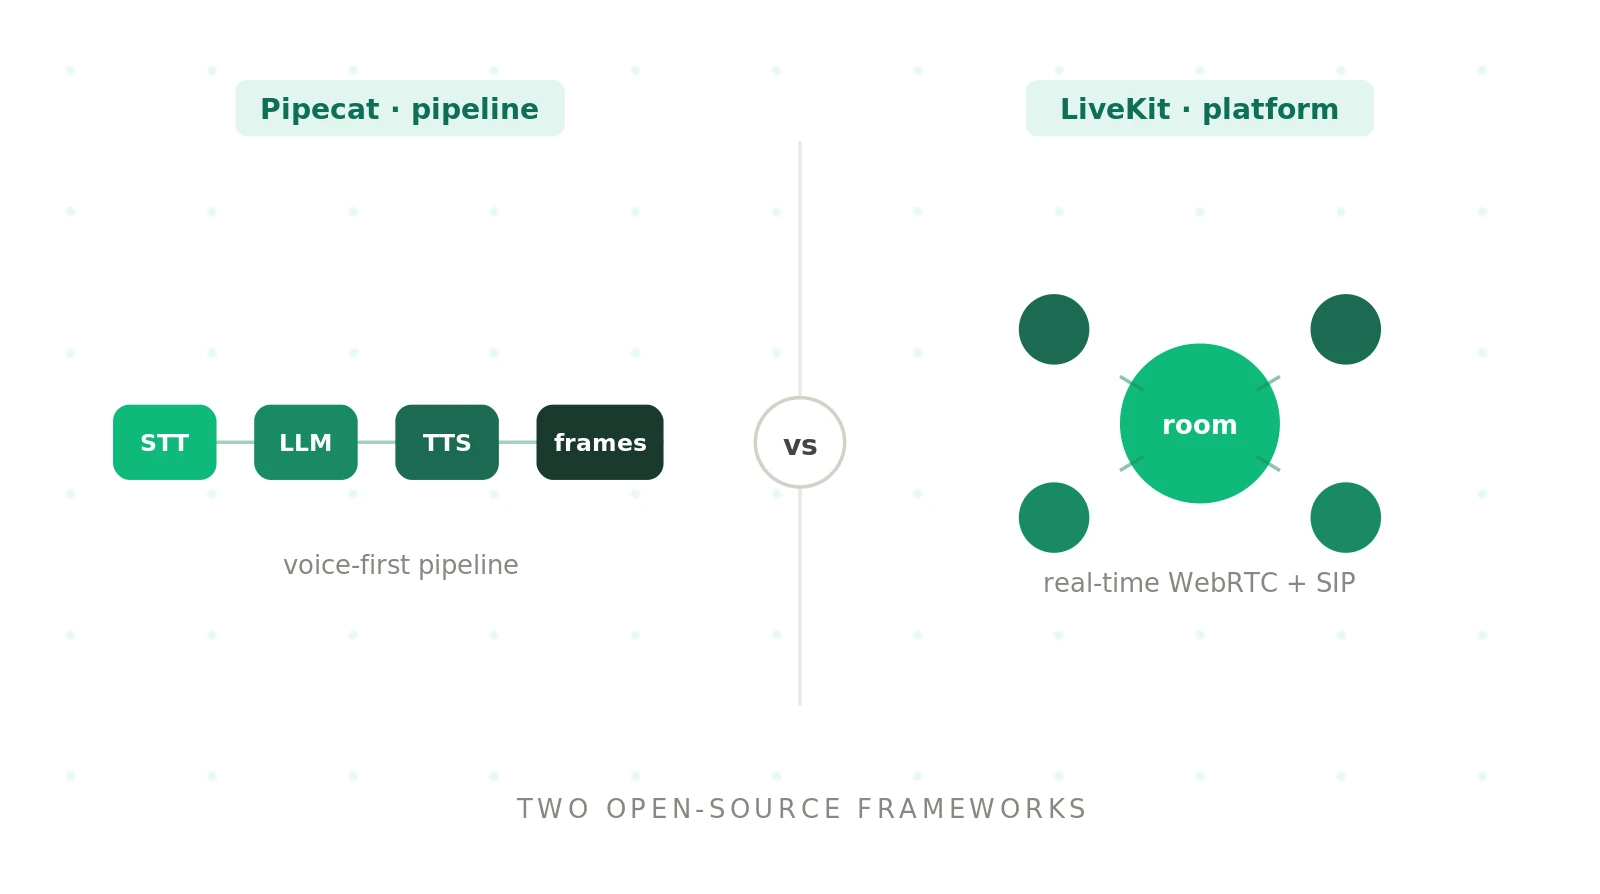
Pipecat vs LiveKit (2026): Which to Choose, and How to Prove It
Pipecat vs LiveKit: LiveKit for phone, SIP and multi-party agents; Pipecat for complex Python pipelines. Verdict table, same agent in both, 9 deep dives.
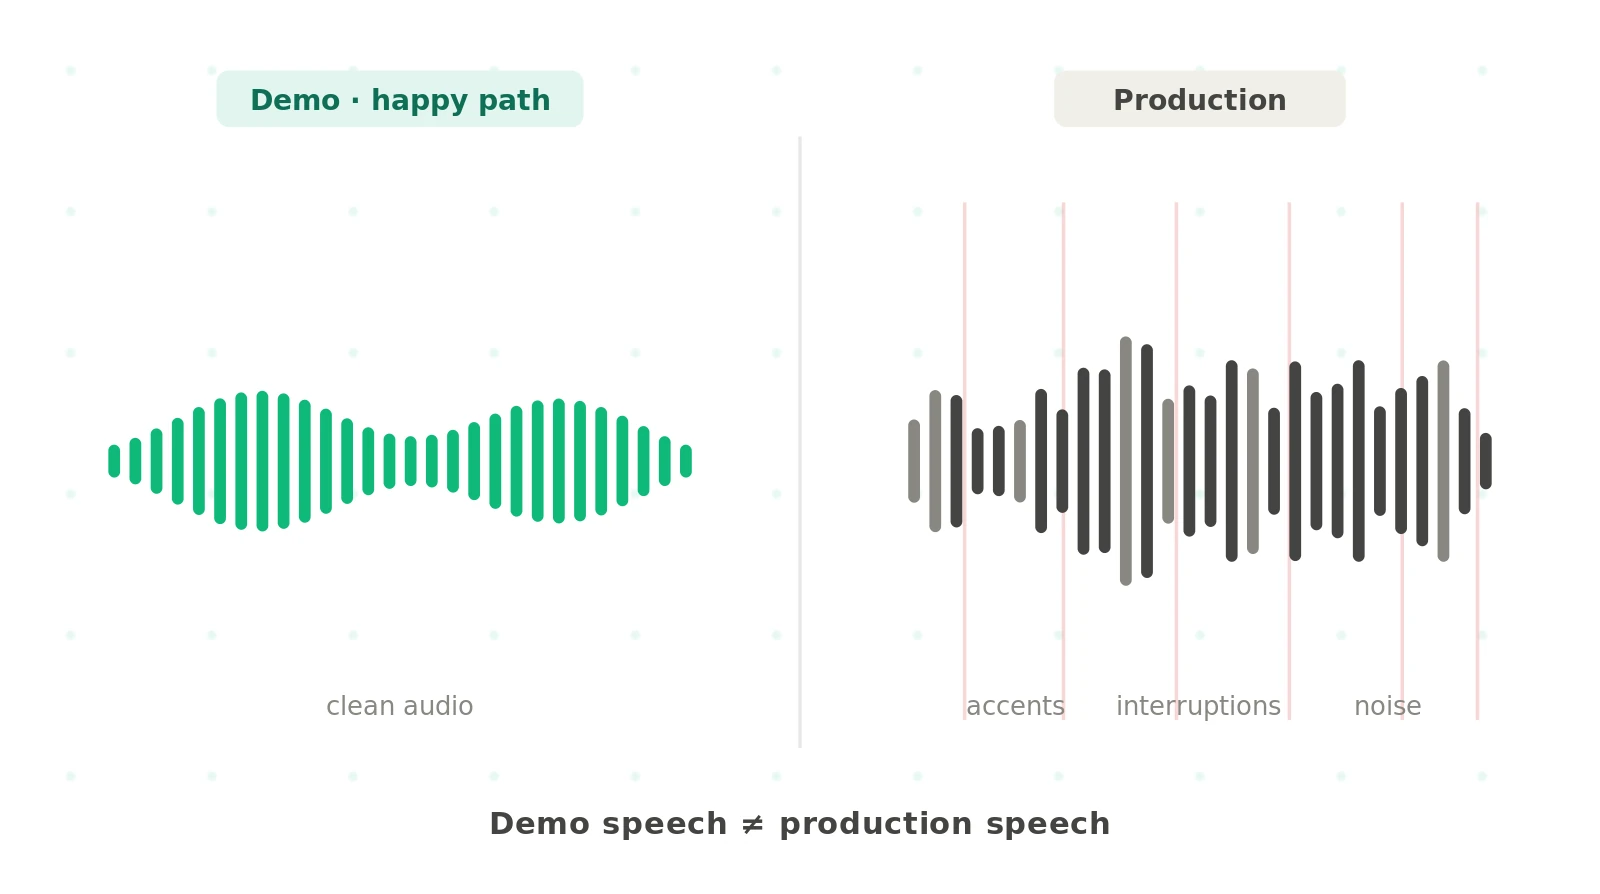
AI voice agent testing: the complete guide to layers, failure modes and regression (2026)
AI voice agent testing in five layers: unit, audio replay, simulated phone calls, load and production scoring. Failure taxonomy, thresholds and regression.
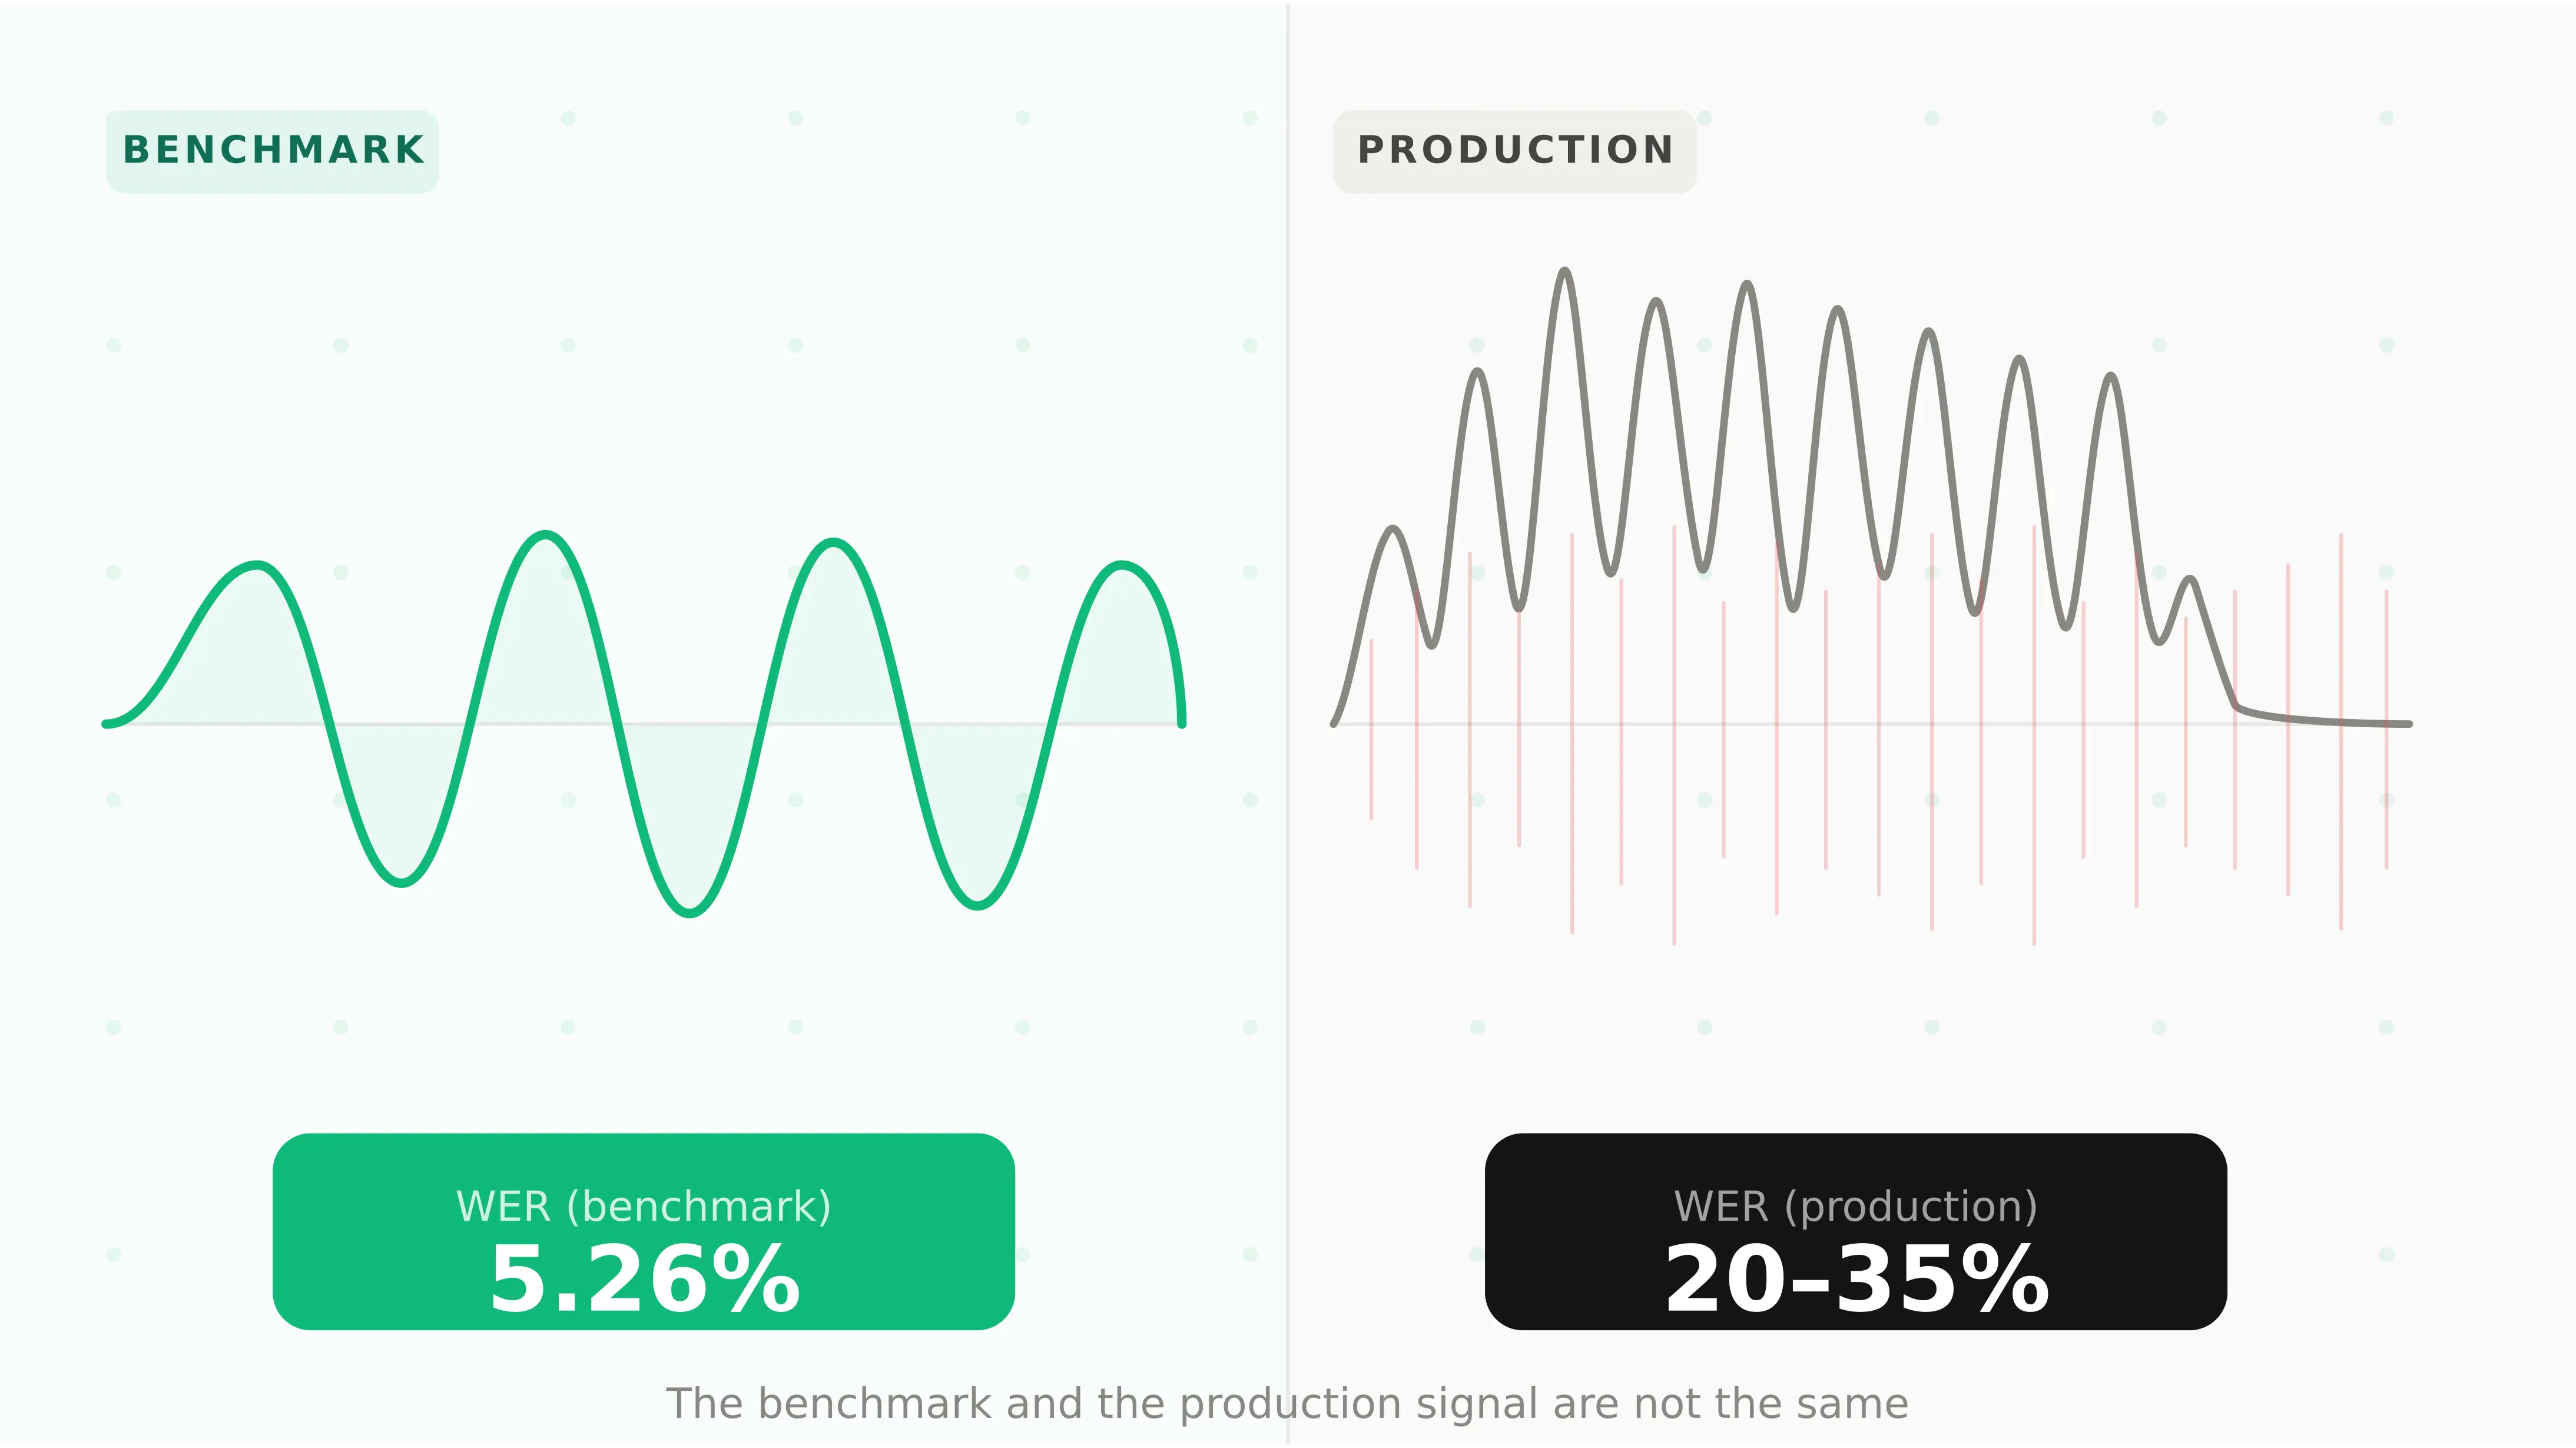
Deepgram Testing for Voice Agents: Latency, Accuracy and Load (2026)
Deepgram testing for voice agents: measure latency and WER, load test concurrency limits, and get direct answers to 11 common Deepgram questions.
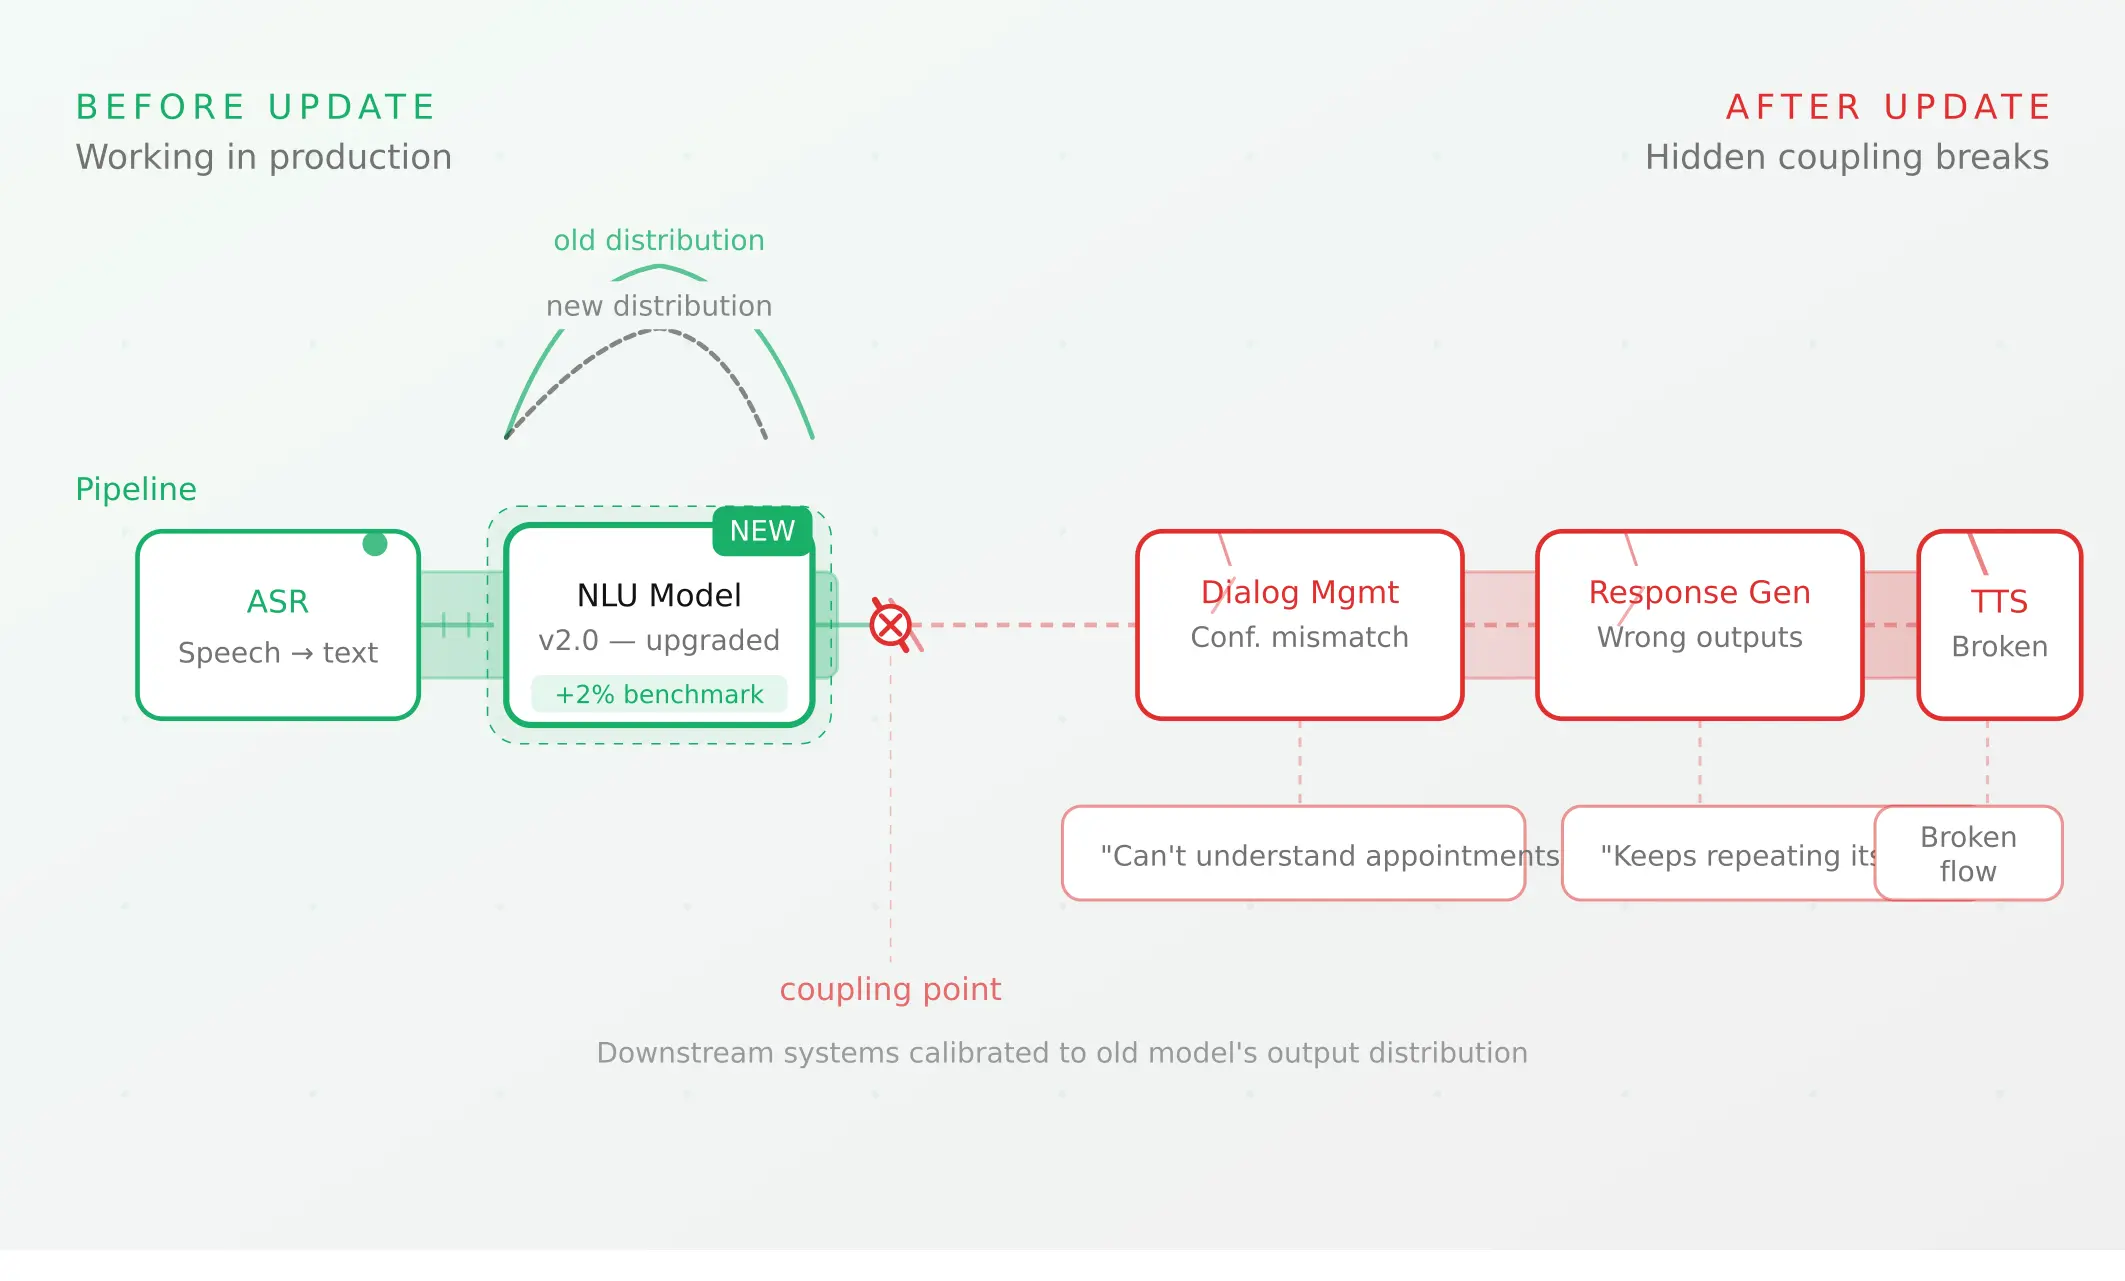
Voice agent regression testing: how to detect regressions from model updates you don't control
Voice agent regression testing for changes you don't control: pin each layer, run a nightly pinned-vs-latest canary, and use paired stats to detect drops.