Blog
Page 28 of 32
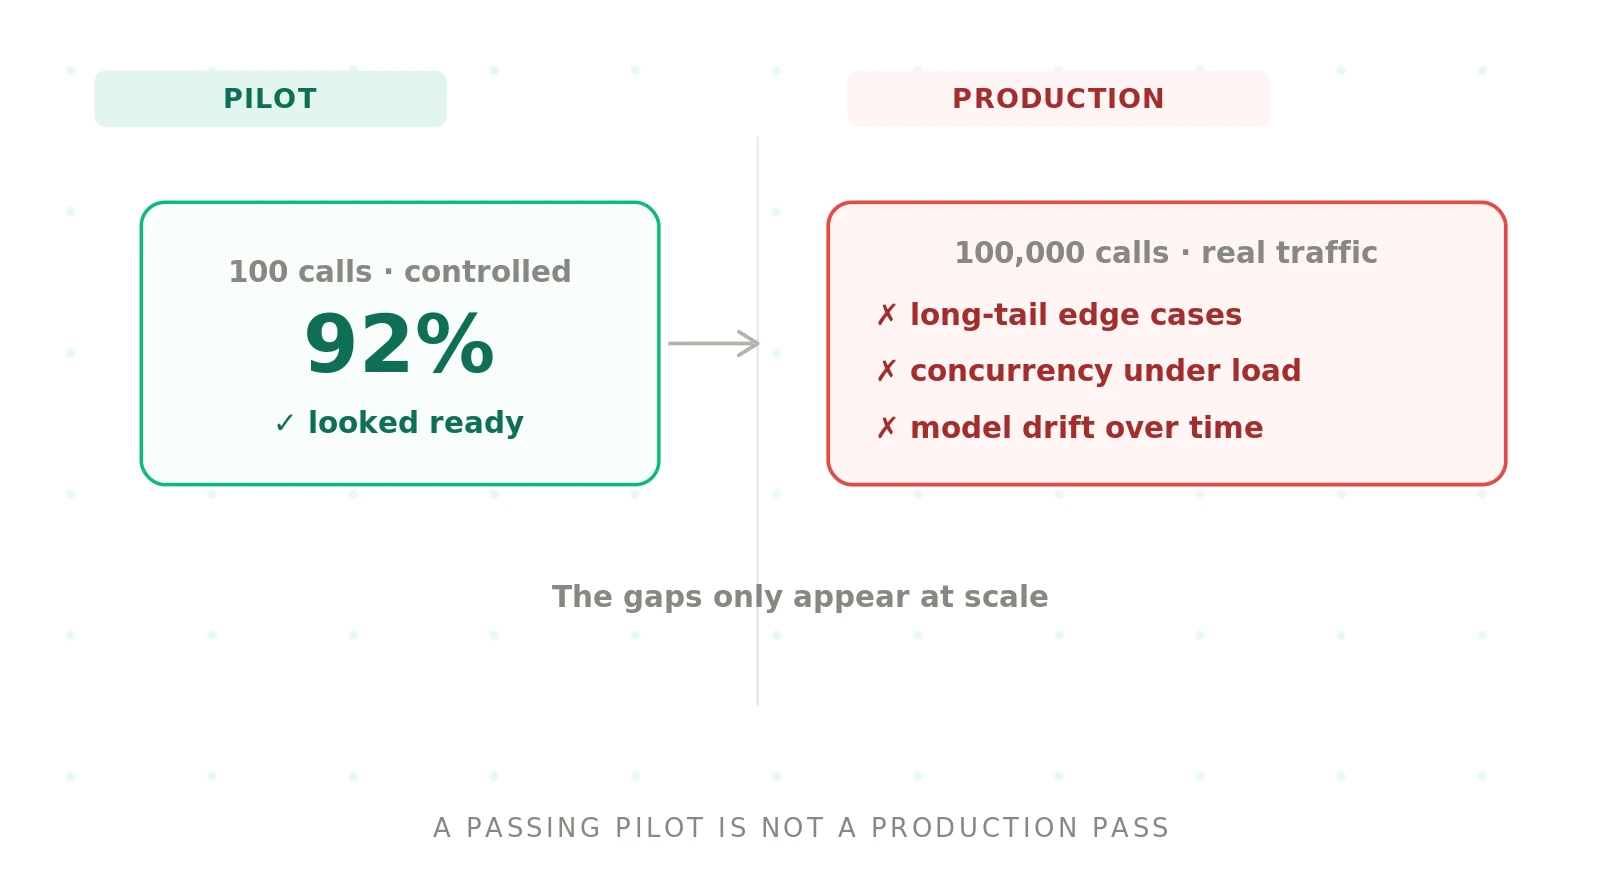
From Pilot to Production: Scoring Voice AI for Launch
A voice agent can pass a clean pilot and still fail at full volume. Here is how to score your pilot results and stage a safe launch rollout.
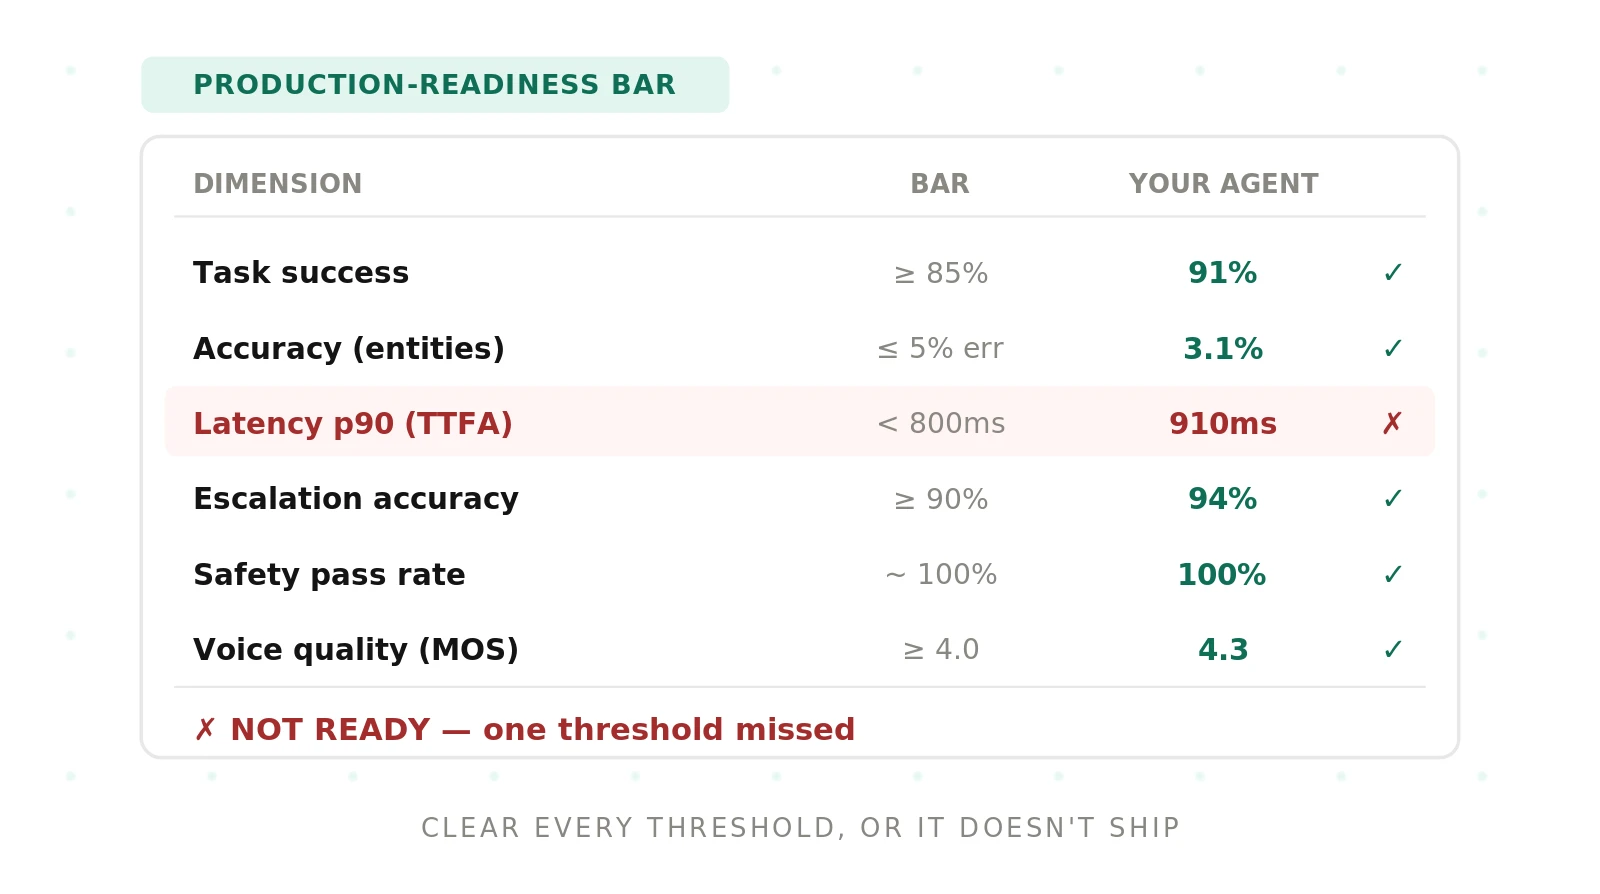
The Voice Agent Production-Readiness Bar
The production-readiness bar for voice agents: the thresholds — task success, accuracy, latency, escalation, safety — an agent must clear to go live.
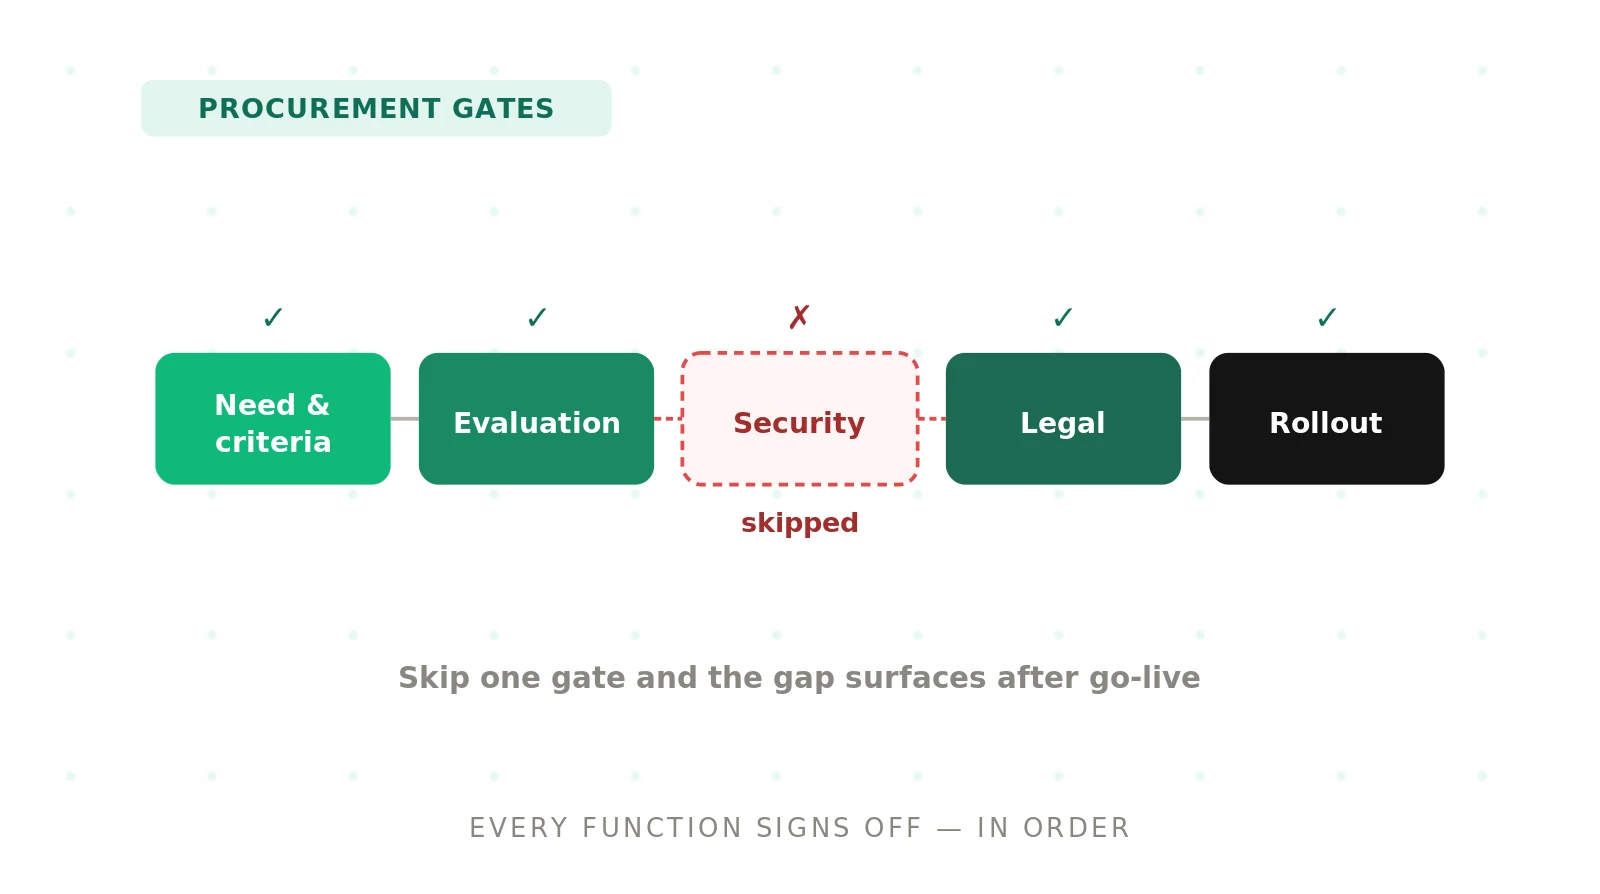
Voice AI Procurement Checklist for Enterprises
An enterprise voice AI procurement checklist: the stakeholders and gates — from need and RFP to security, legal, and rollout — so nothing is skipped.
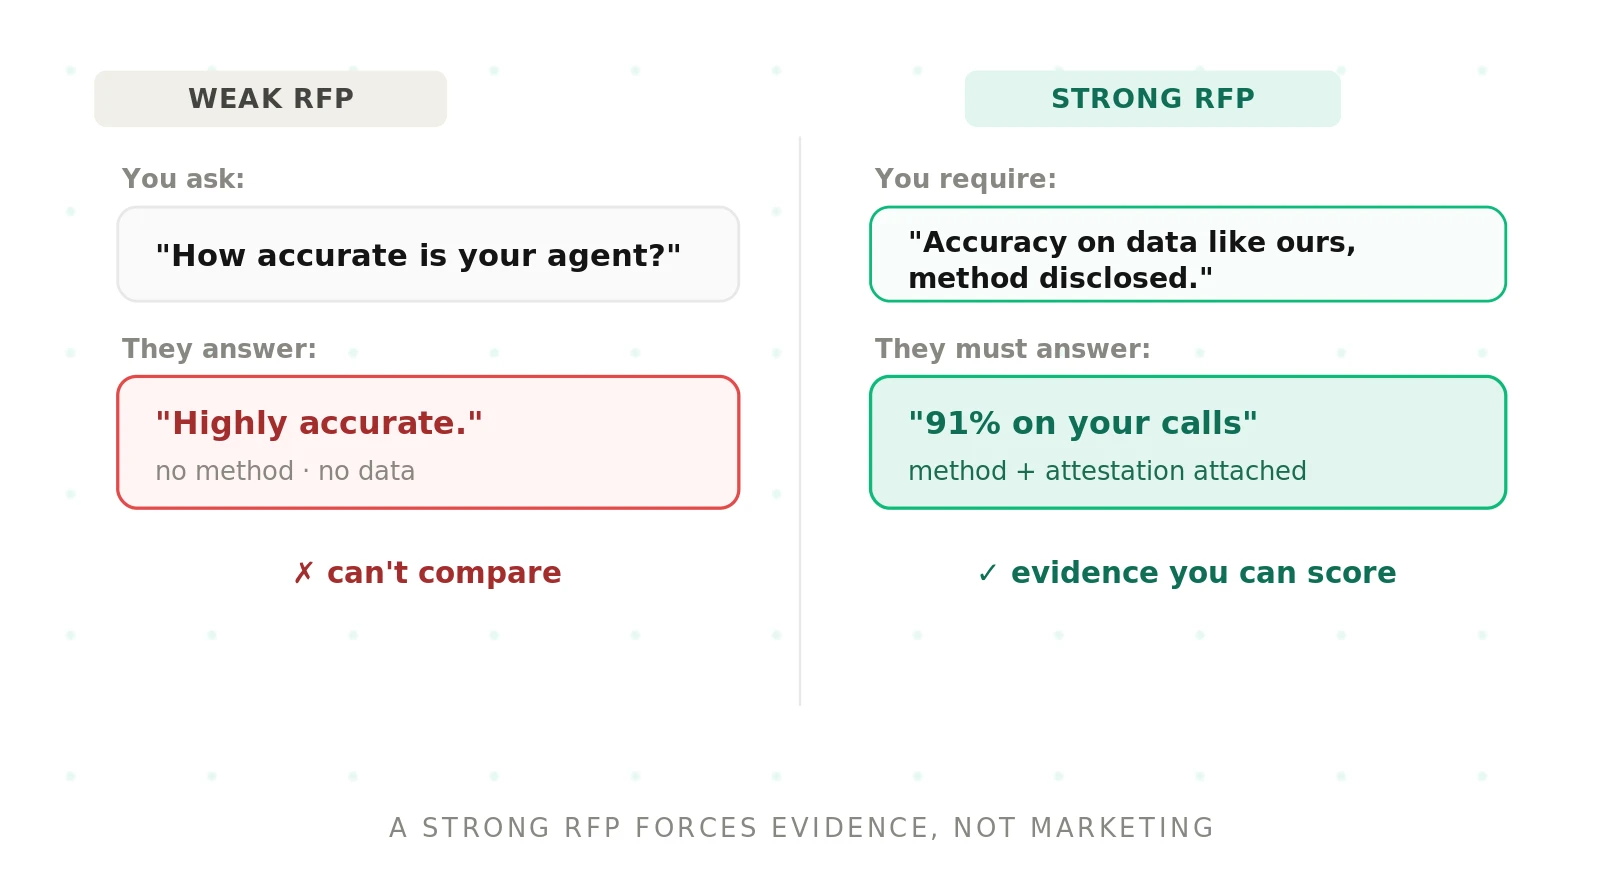
Building a Voice AI RFP: The Criteria Checklist
A voice AI RFP checklist that forces evidence, not marketing: accuracy on your data, latency percentiles, security, SLAs, pricing, and evaluation method.
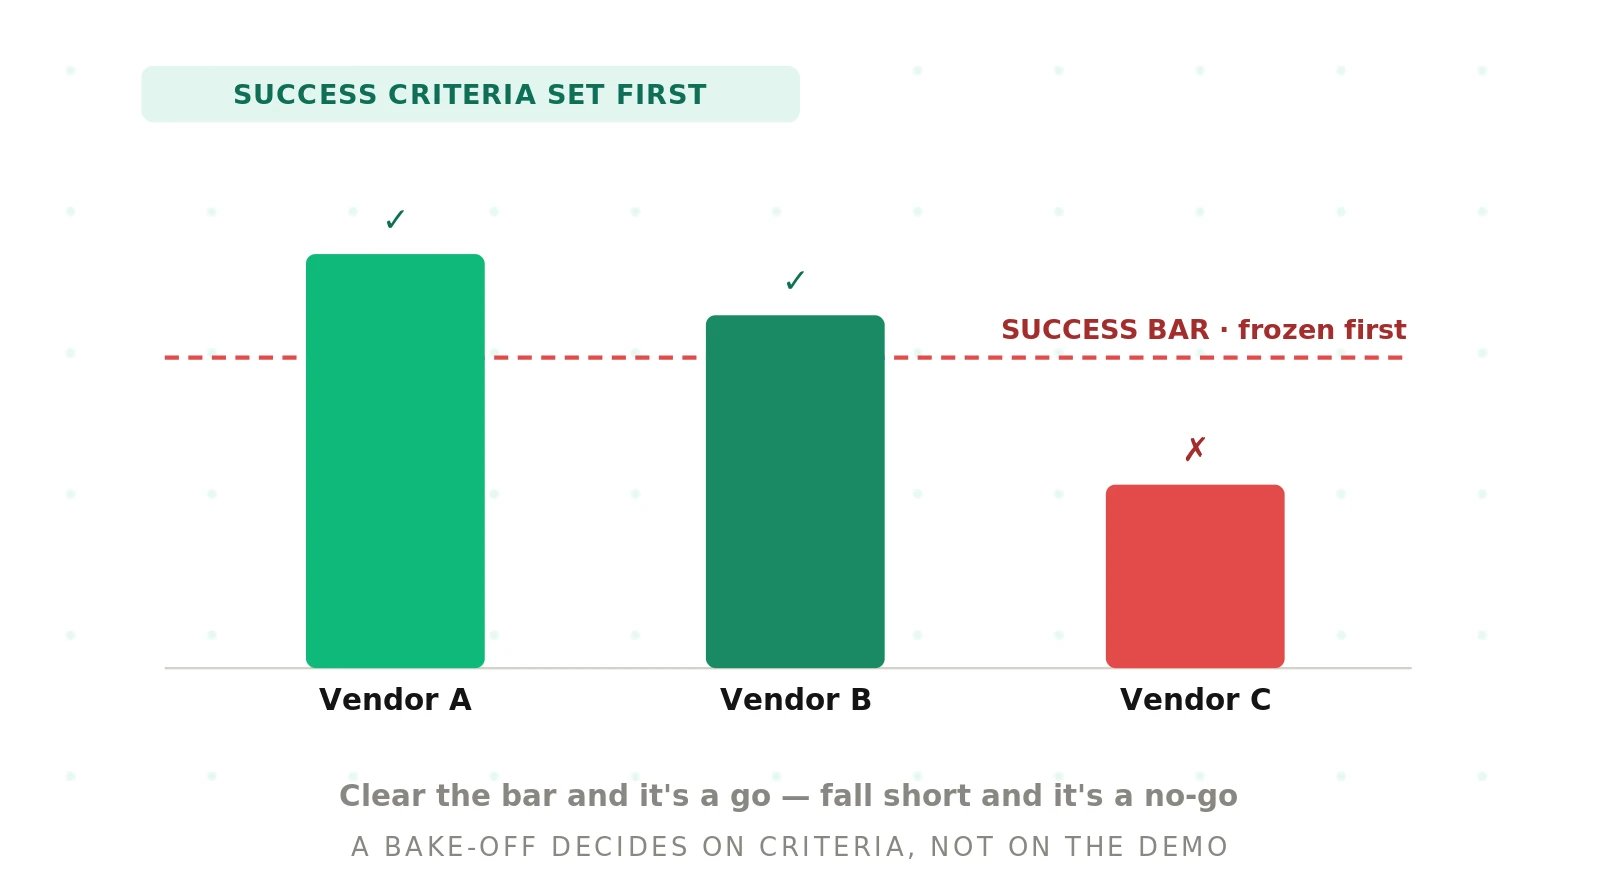
How to Run a Voice Agent Bake-Off (POC Playbook)
A playbook for a voice agent bake-off: set pass/fail criteria first, give every vendor identical conditions, run long enough, and decide on the results.
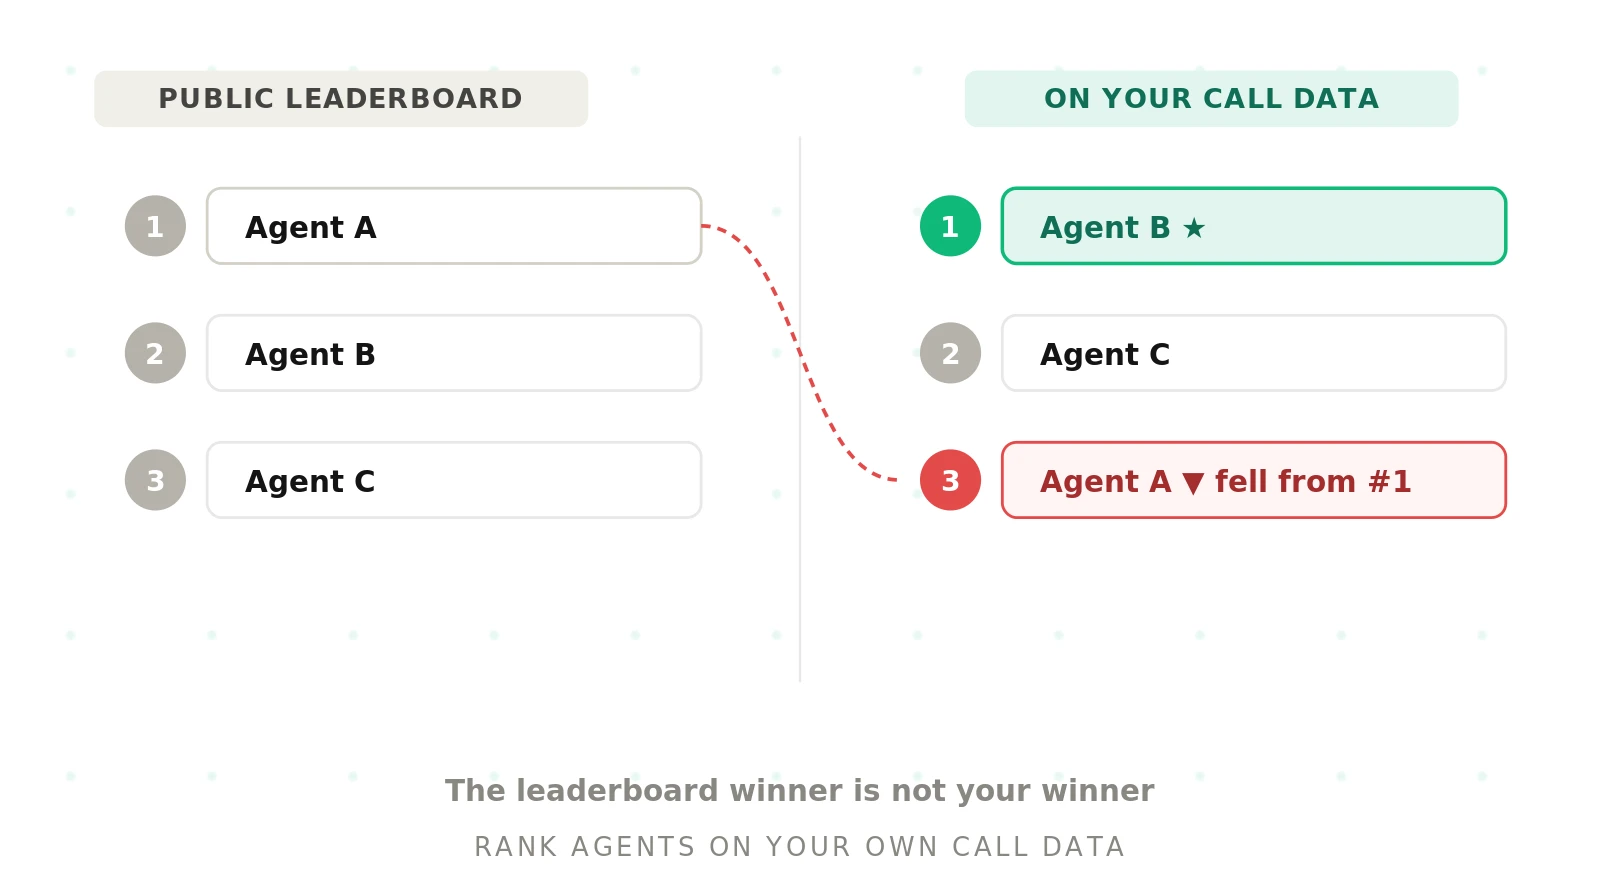
Benchmarking Voice Agents on Your Own Data
Public voice AI leaderboards don't predict your production. Why to benchmark voice agents on your own call data, and build one that fits your traffic.
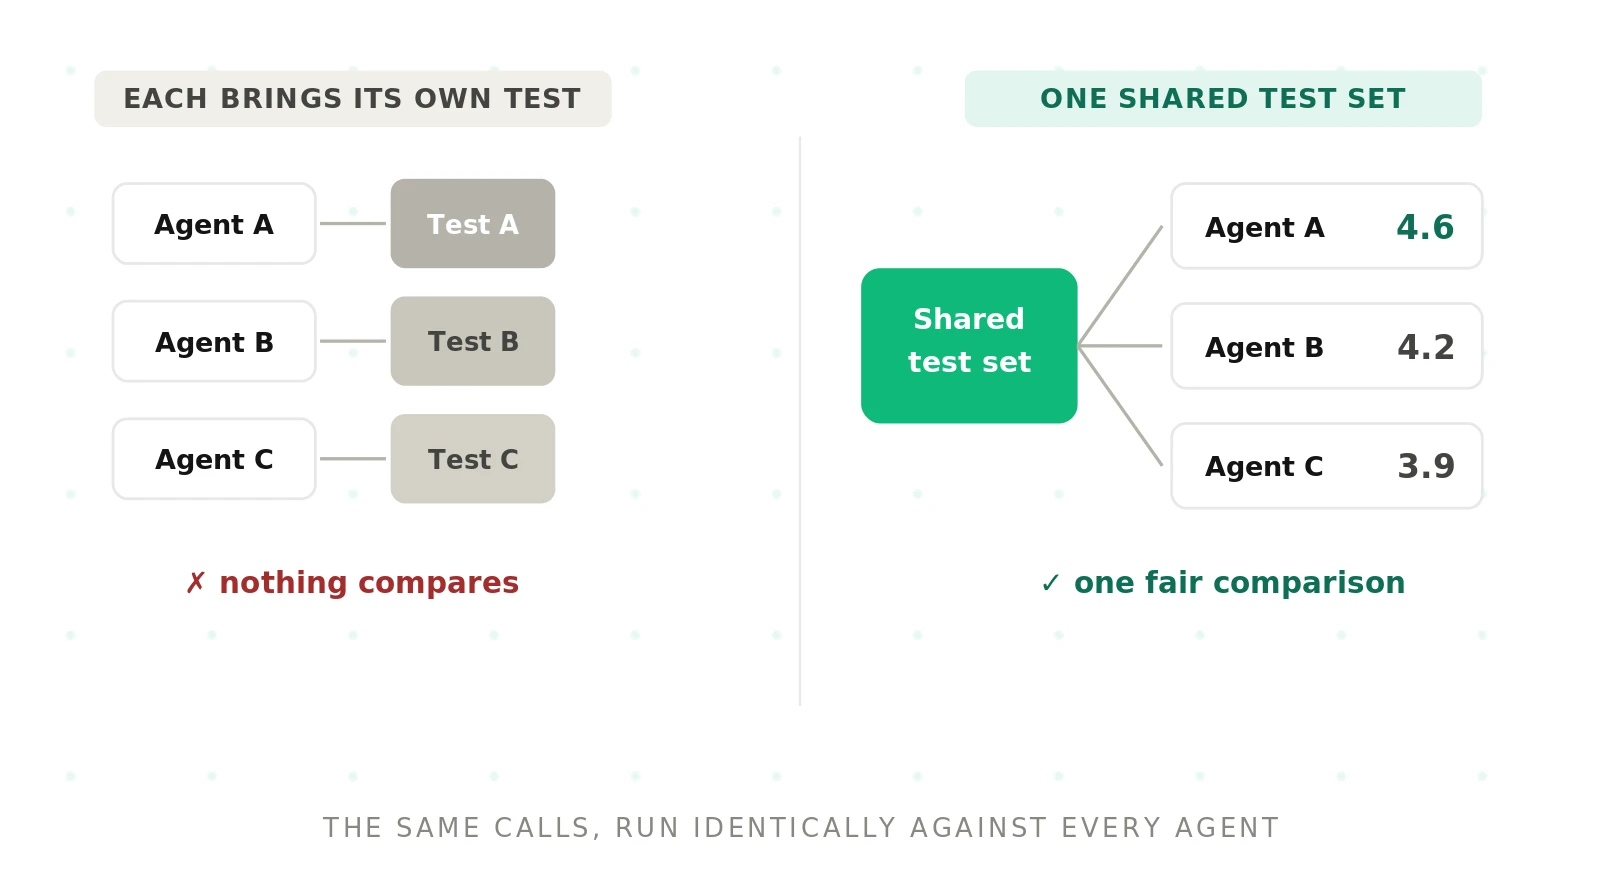
How to Compare Voice Agents on the Same Test Cases
The only fair way to compare voice agents is one shared test set run identically against each. How to build it from your real calls and reuse it over time.
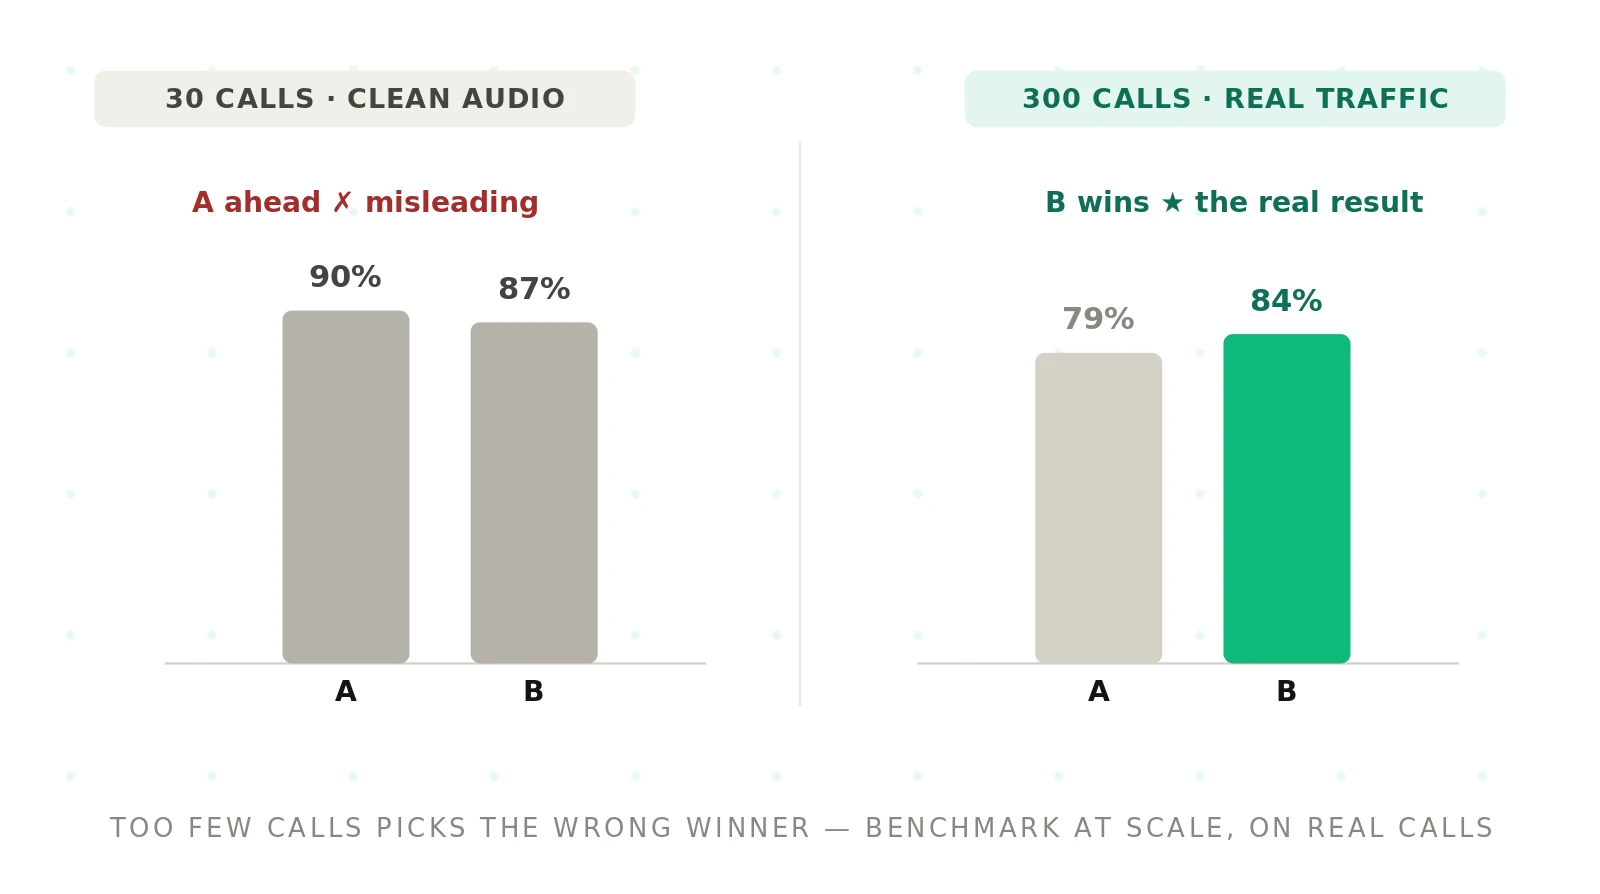
Voice Agent Vendor Benchmarking: A 2026 Guide
How to benchmark voice agent vendors fairly: representative data, fixed definitions, controlled conditions, and a sample large enough to be reproducible.
Why You Can't Trust Vendor-Reported Voice AI Metrics
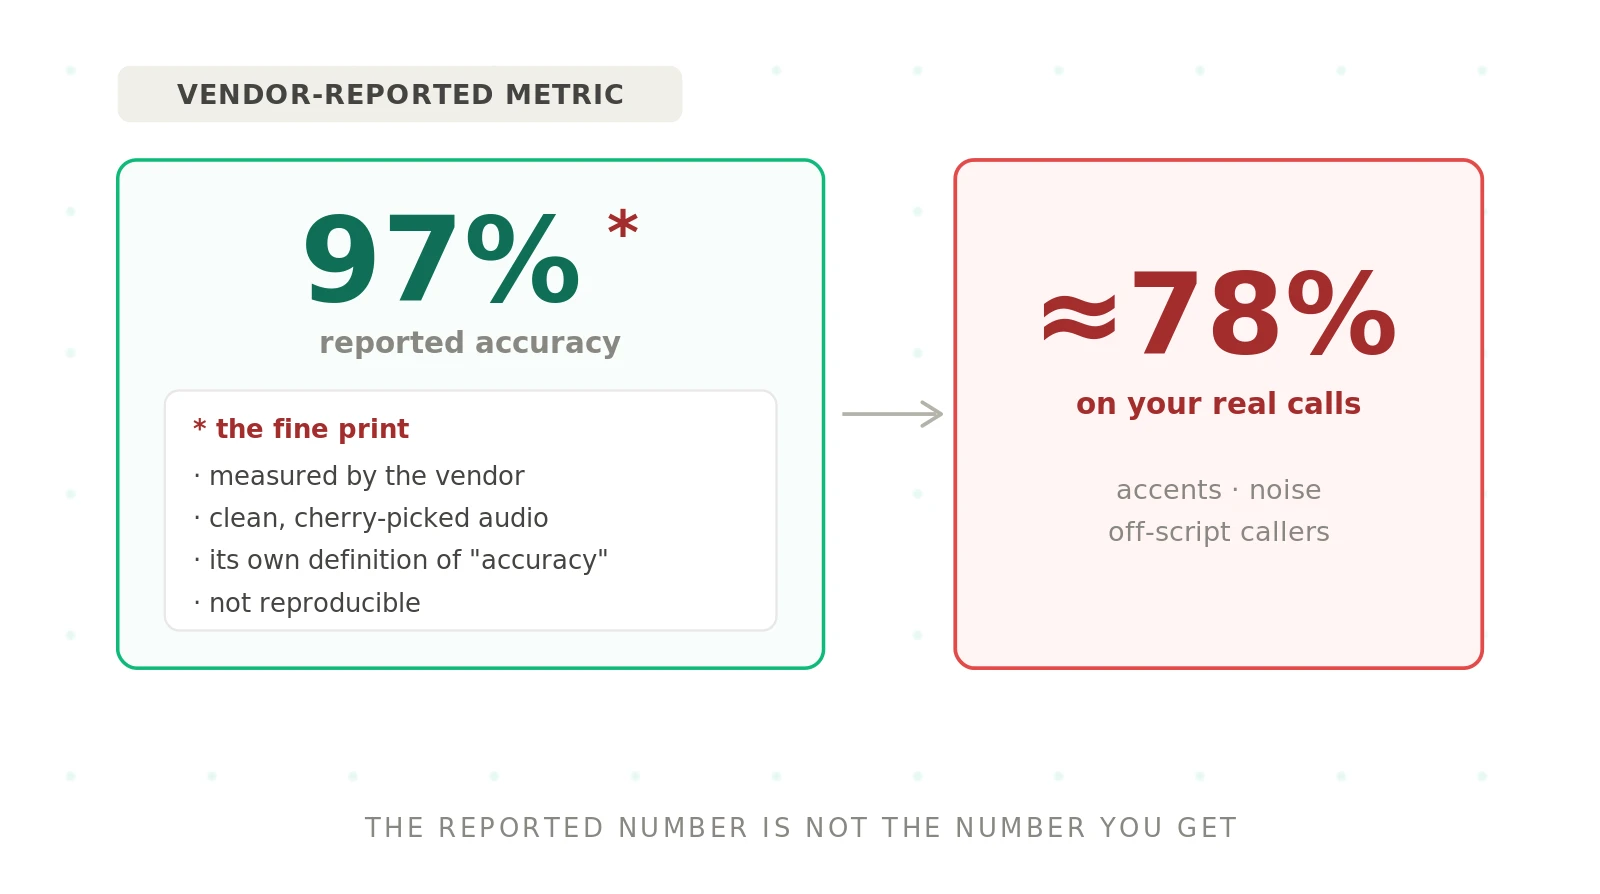
Vendor-reported voice AI metrics are self-measured on cherry-picked data with private definitions. Why they don't compare — and what to measure instead.