Blog
Page 39 of 52
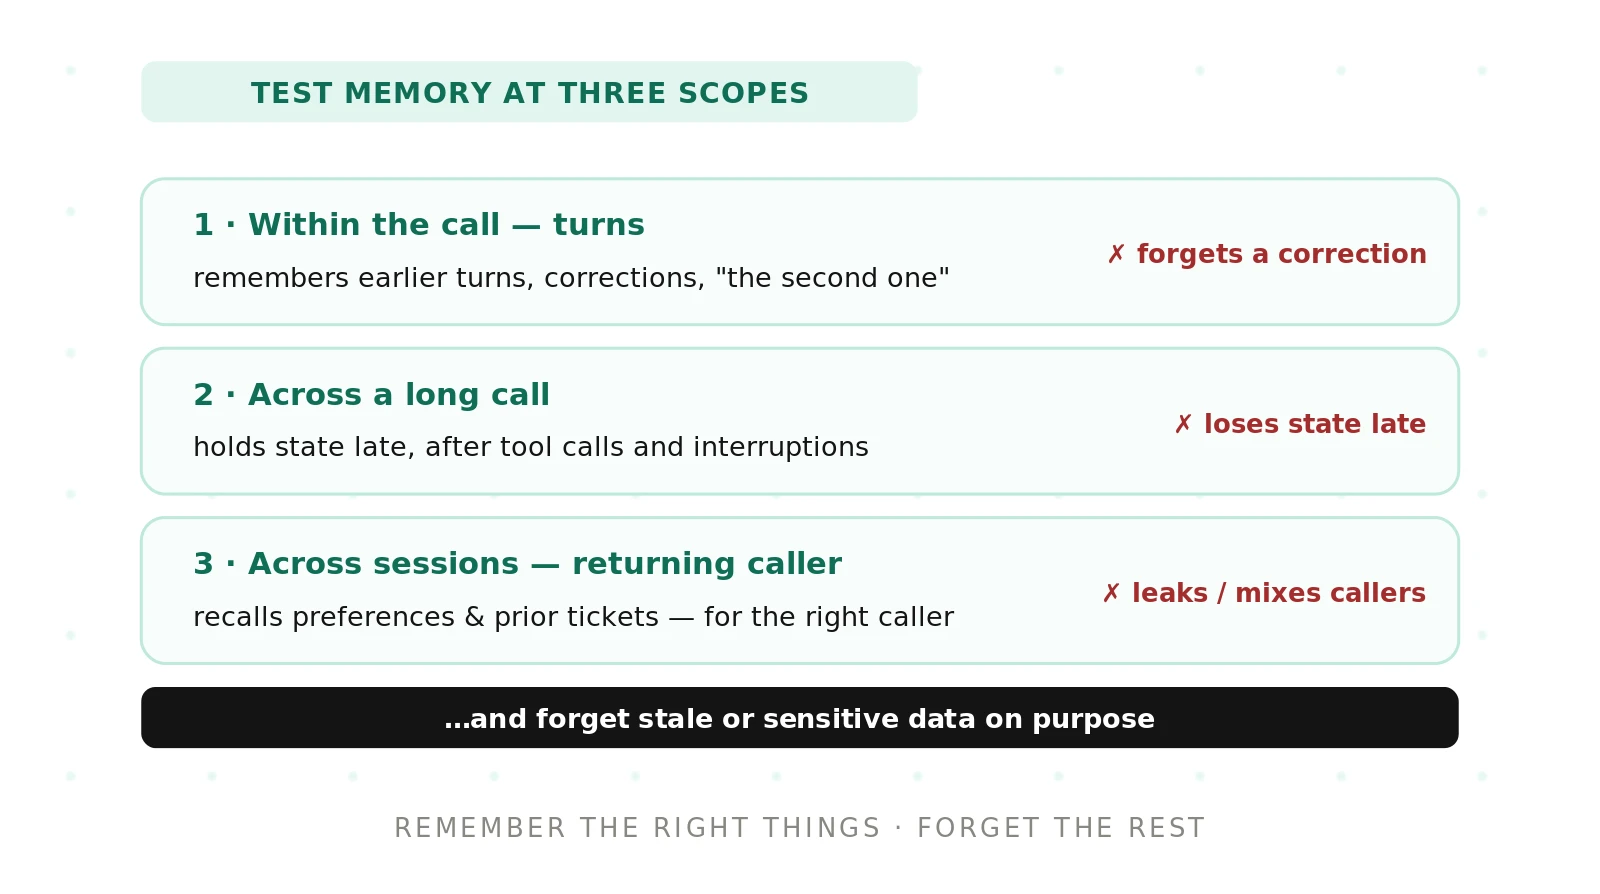
How to Test Memory and Context in Voice Agents
Test memory and context in voice agents across three scopes: turn, whole call, and separate sessions. Learn what to check and the failures to catch.
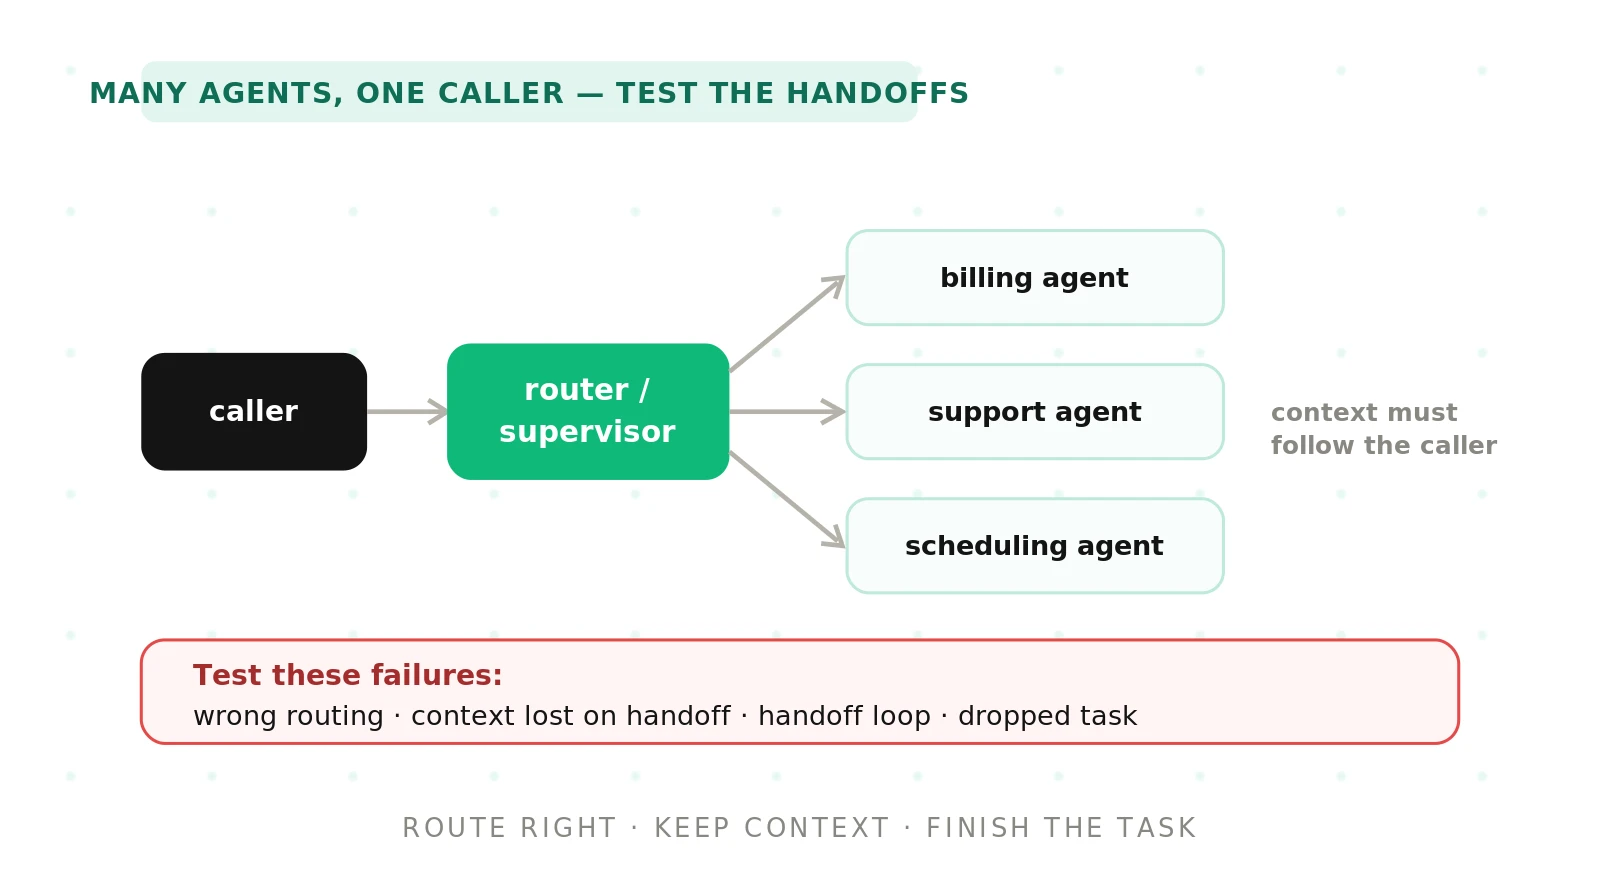
How to Test Multi-Agent Orchestration in Voice Agents
Testing a voice system where multiple AI agents coordinate means checking routing, handoff context, loops, task ownership, and end-to-end success.
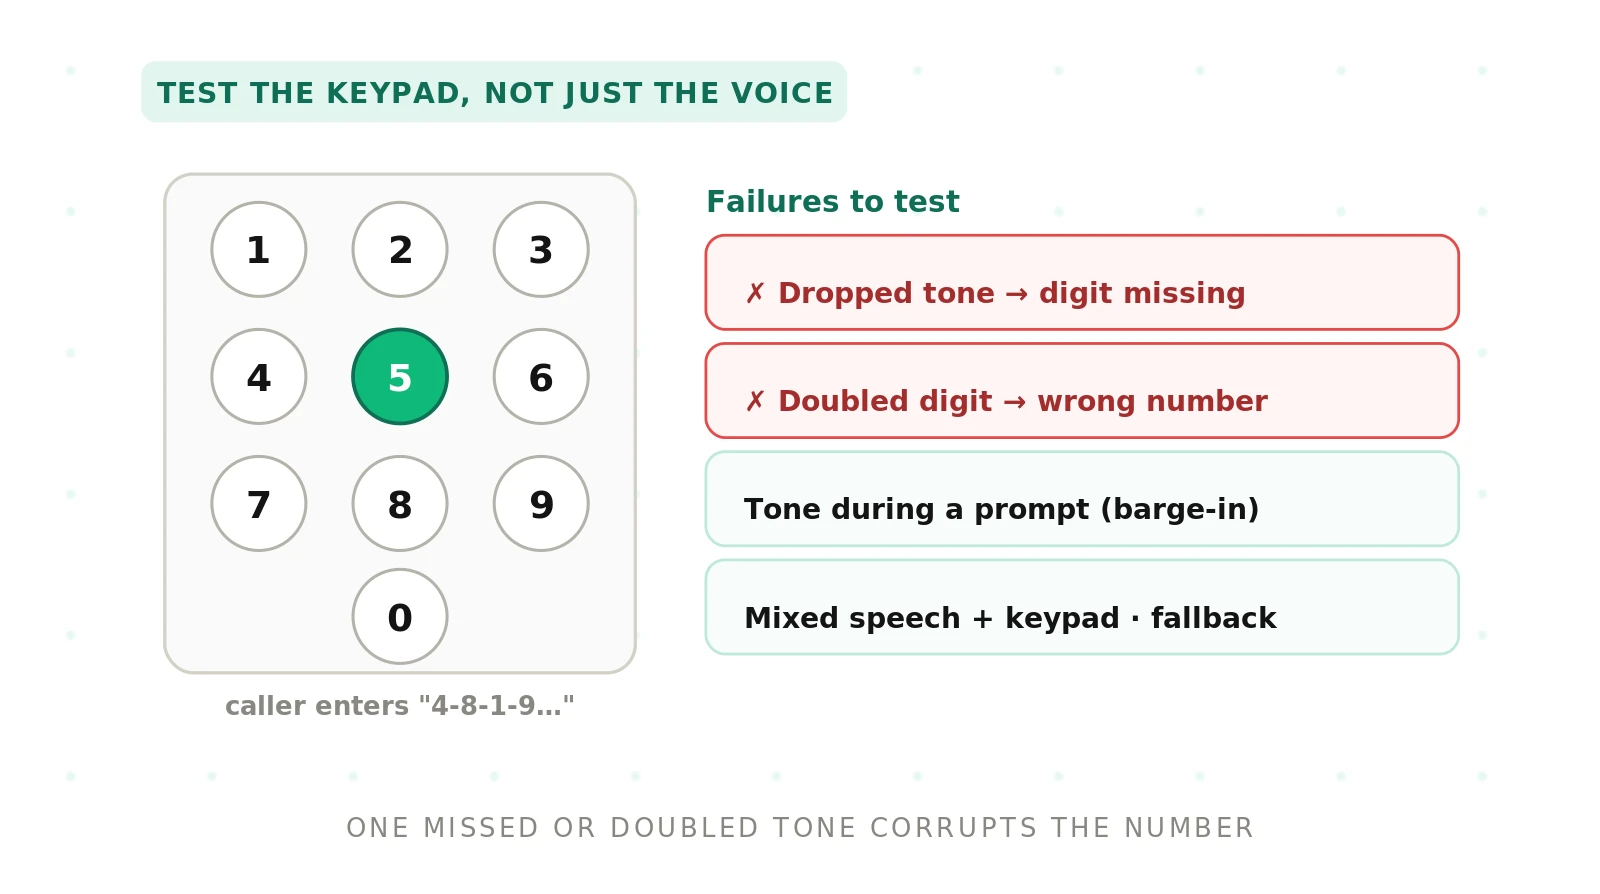
How to Test DTMF Navigation in Voice Agents
Callers still press keys during voice agent calls. Learn how to test DTMF navigation, digit entry, and fallback so tones never break the task.
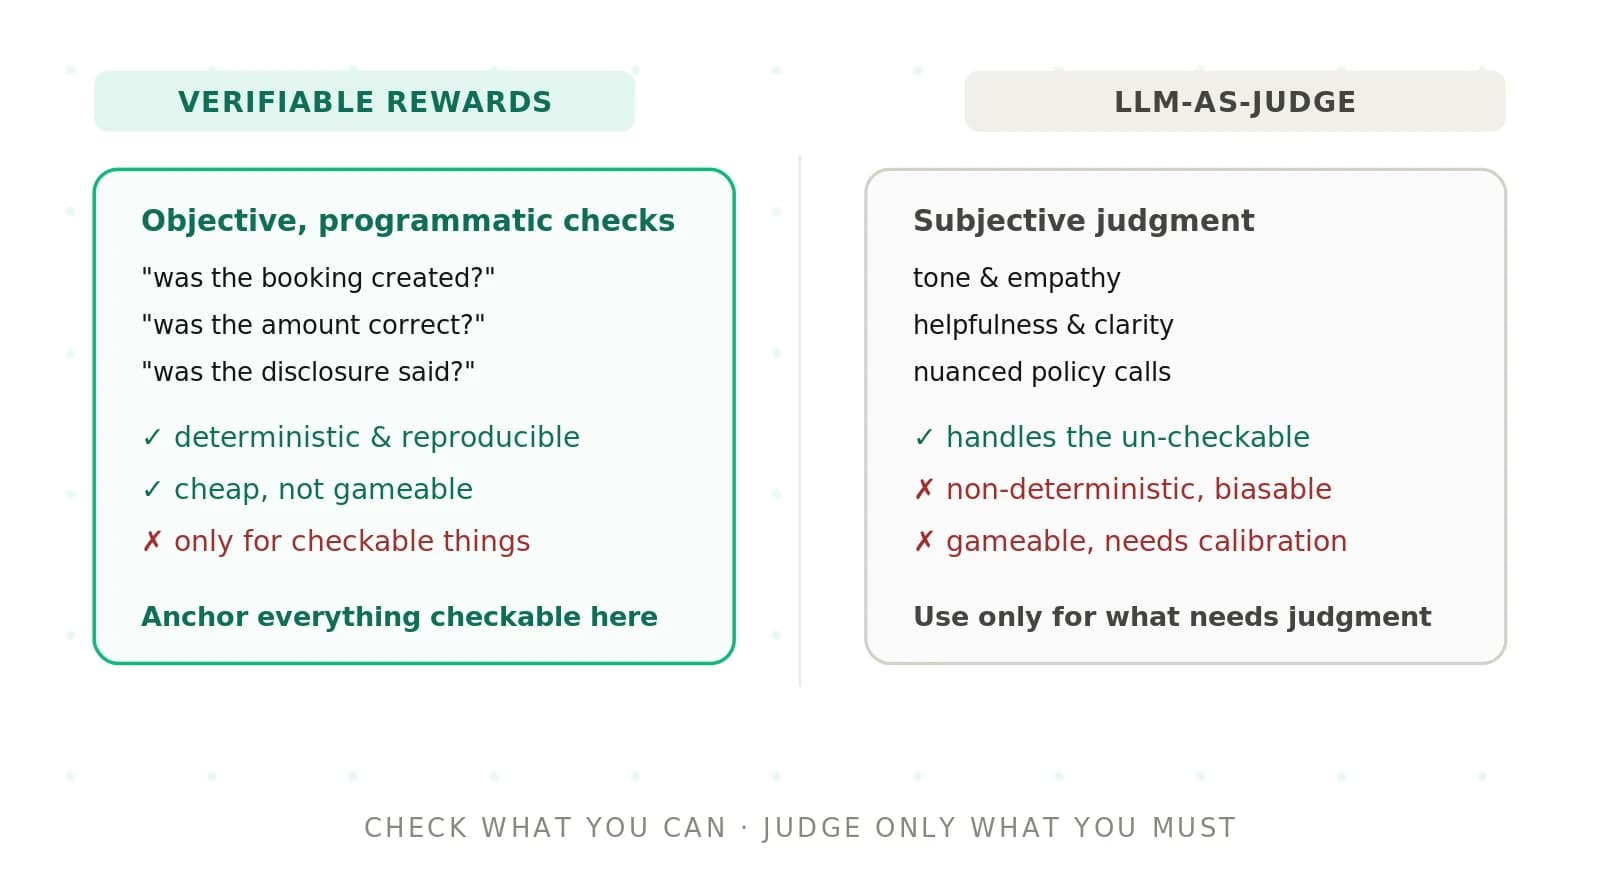
Verifiable Rewards vs LLM Judges for Voice Agents
Verifiable rewards score voice agents with deterministic checks; LLM judges score nuance. Learn when each fits and how to combine them the right way.
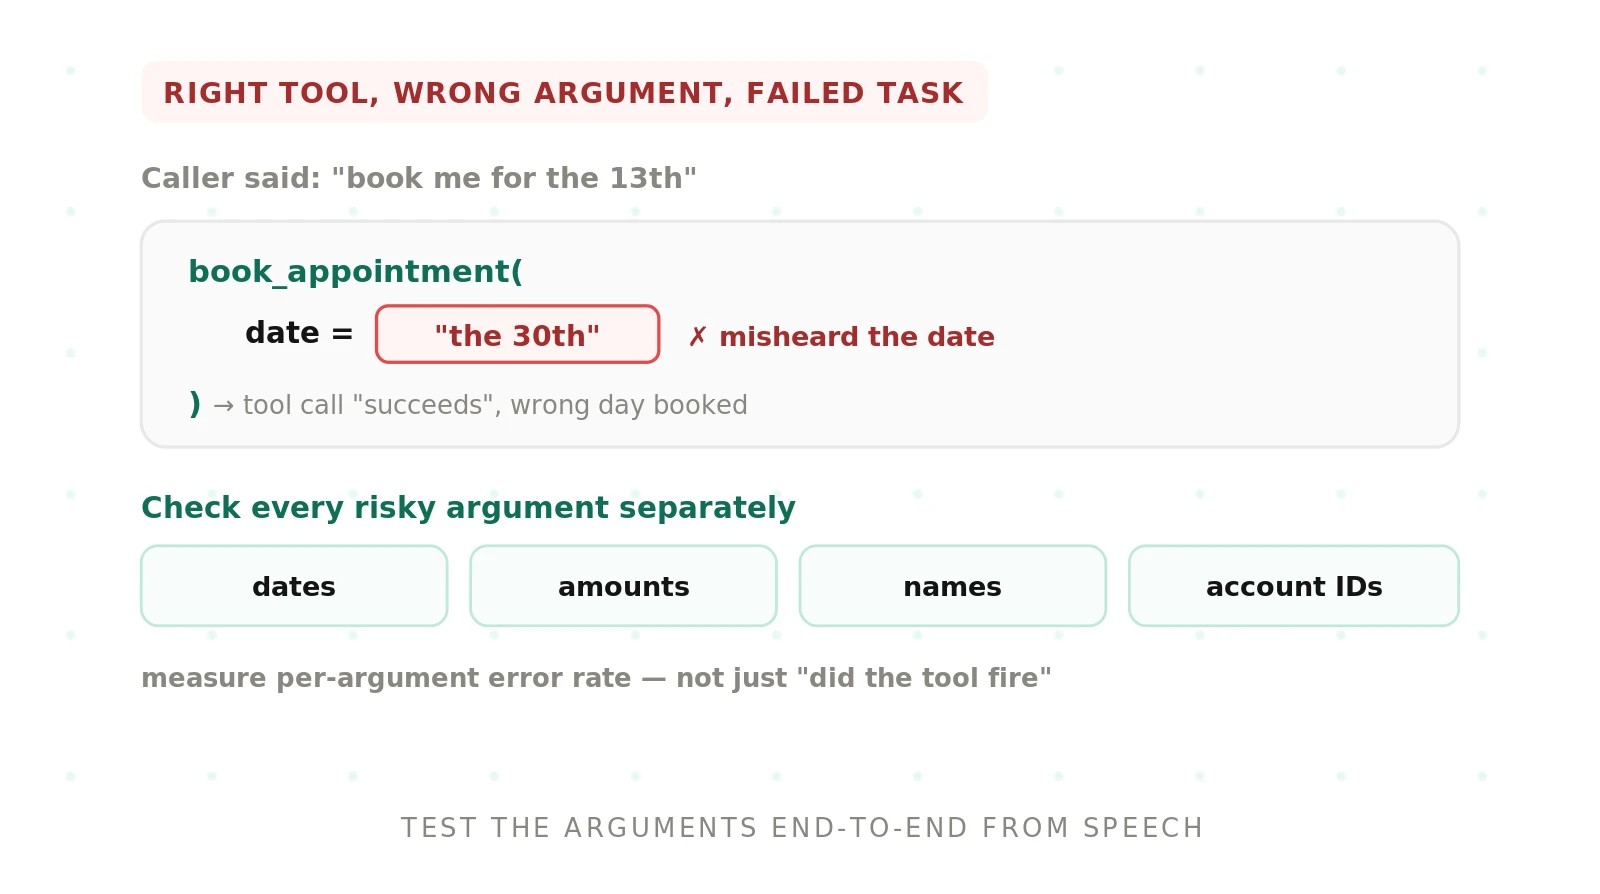
Evaluating Tool-Argument Accuracy from Speech
A voice agent can call the right tool with the wrong arguments and still fail. Learn how to measure tool-argument accuracy end to end from speech.
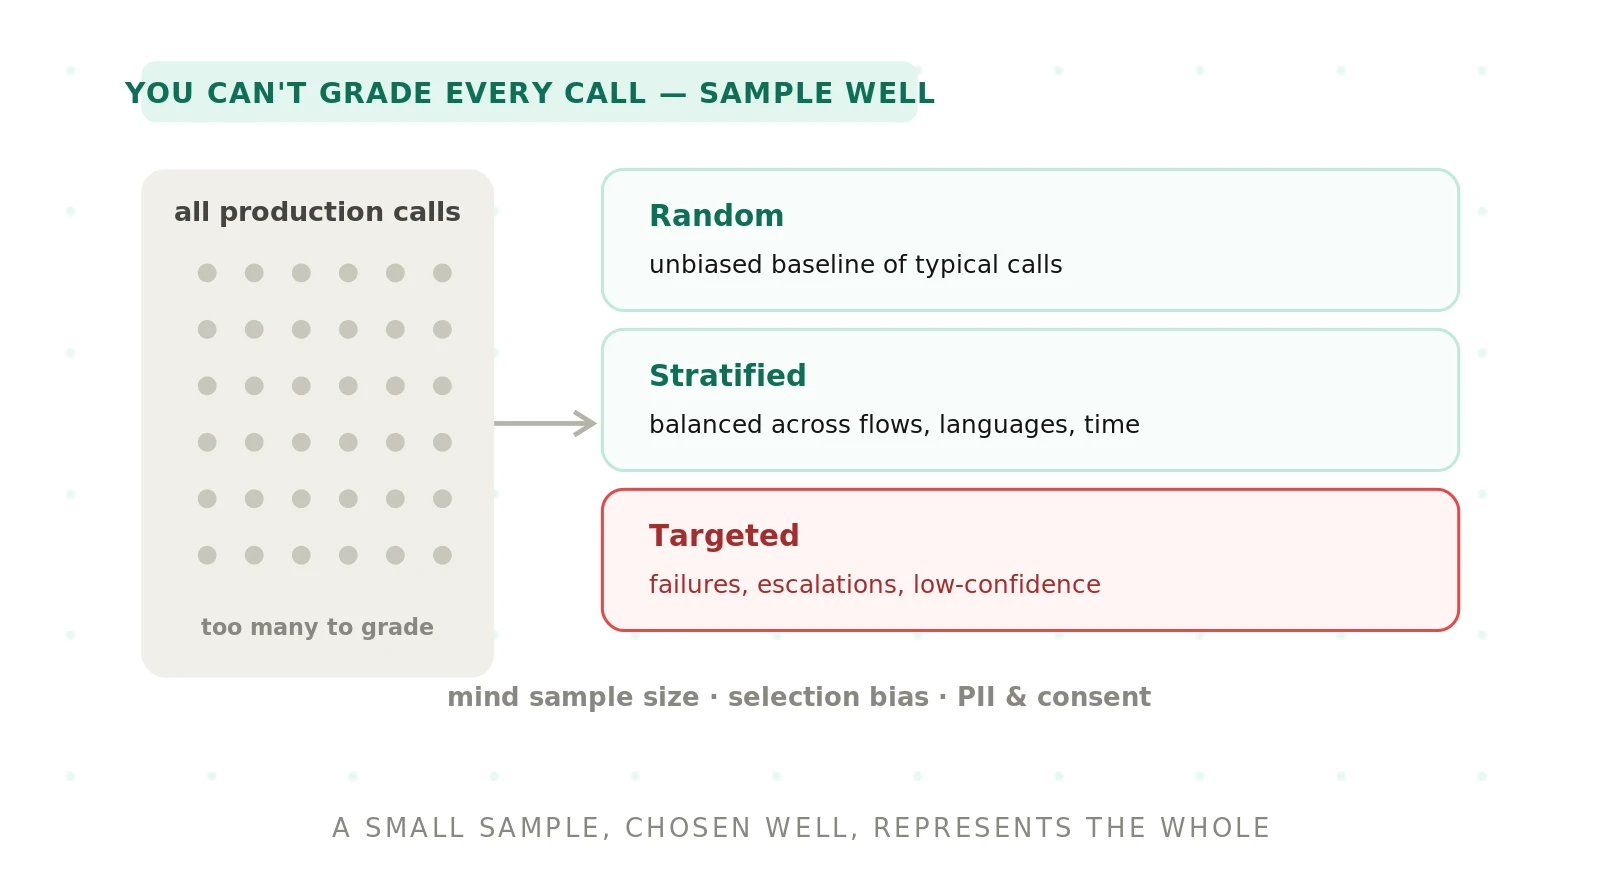
How to Sample Live Calls for Evaluation
You can't grade every production call. How to sample live calls for voice agent evaluation: random, stratified, and targeted methods, sizing, and PII.
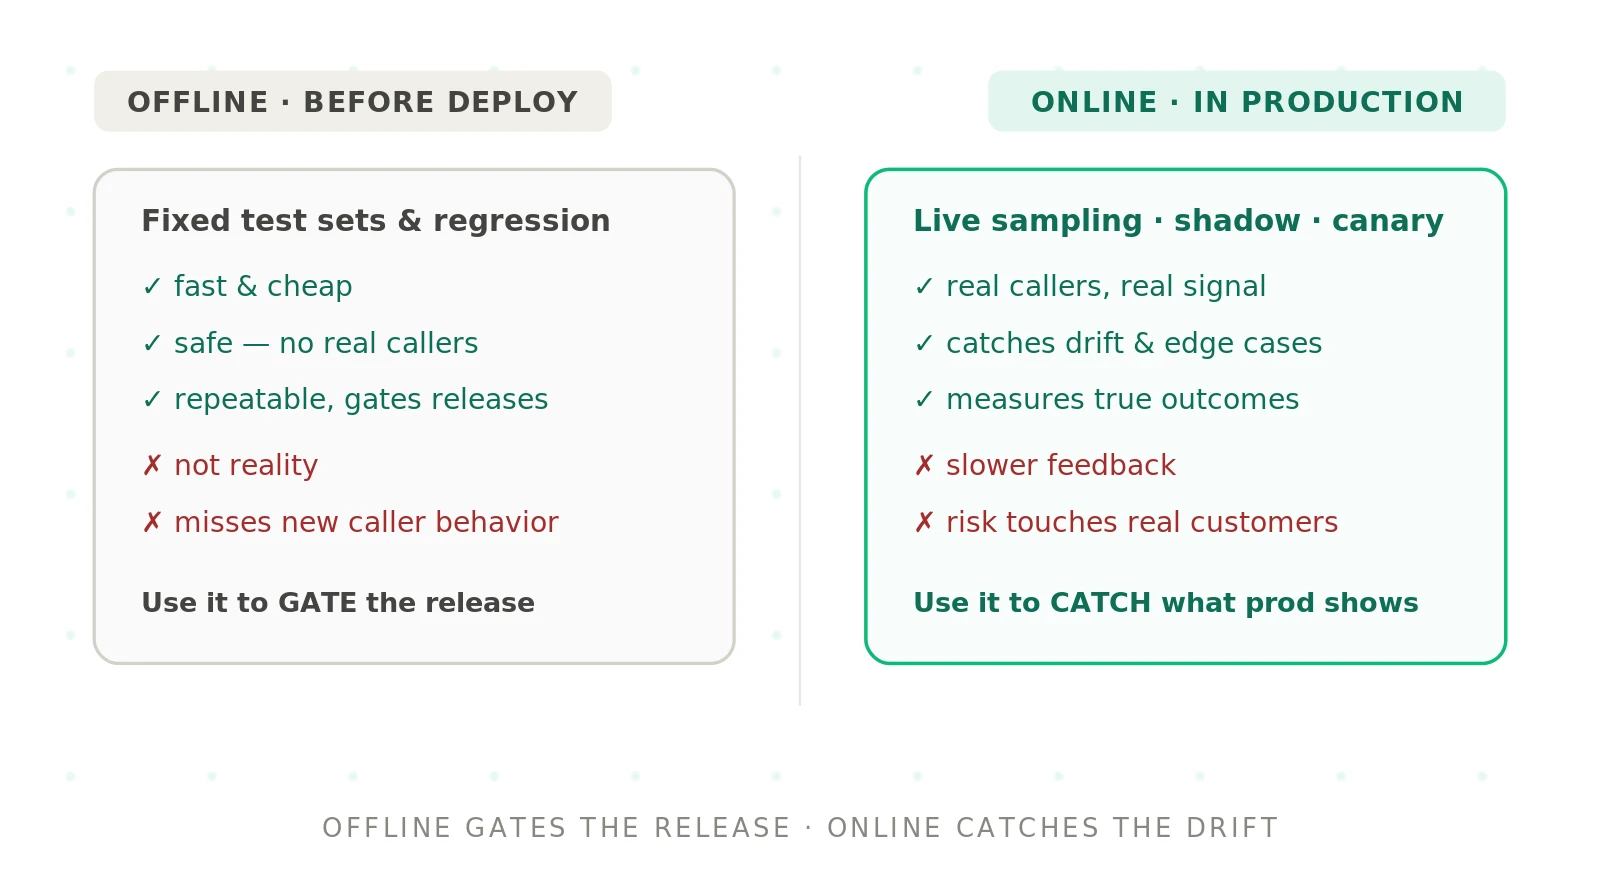
Offline vs Online Voice Agent Evaluation
Offline vs online voice agent evaluation compared on speed, realism, risk, and what each catches, plus how to combine them to gate releases and find drift.
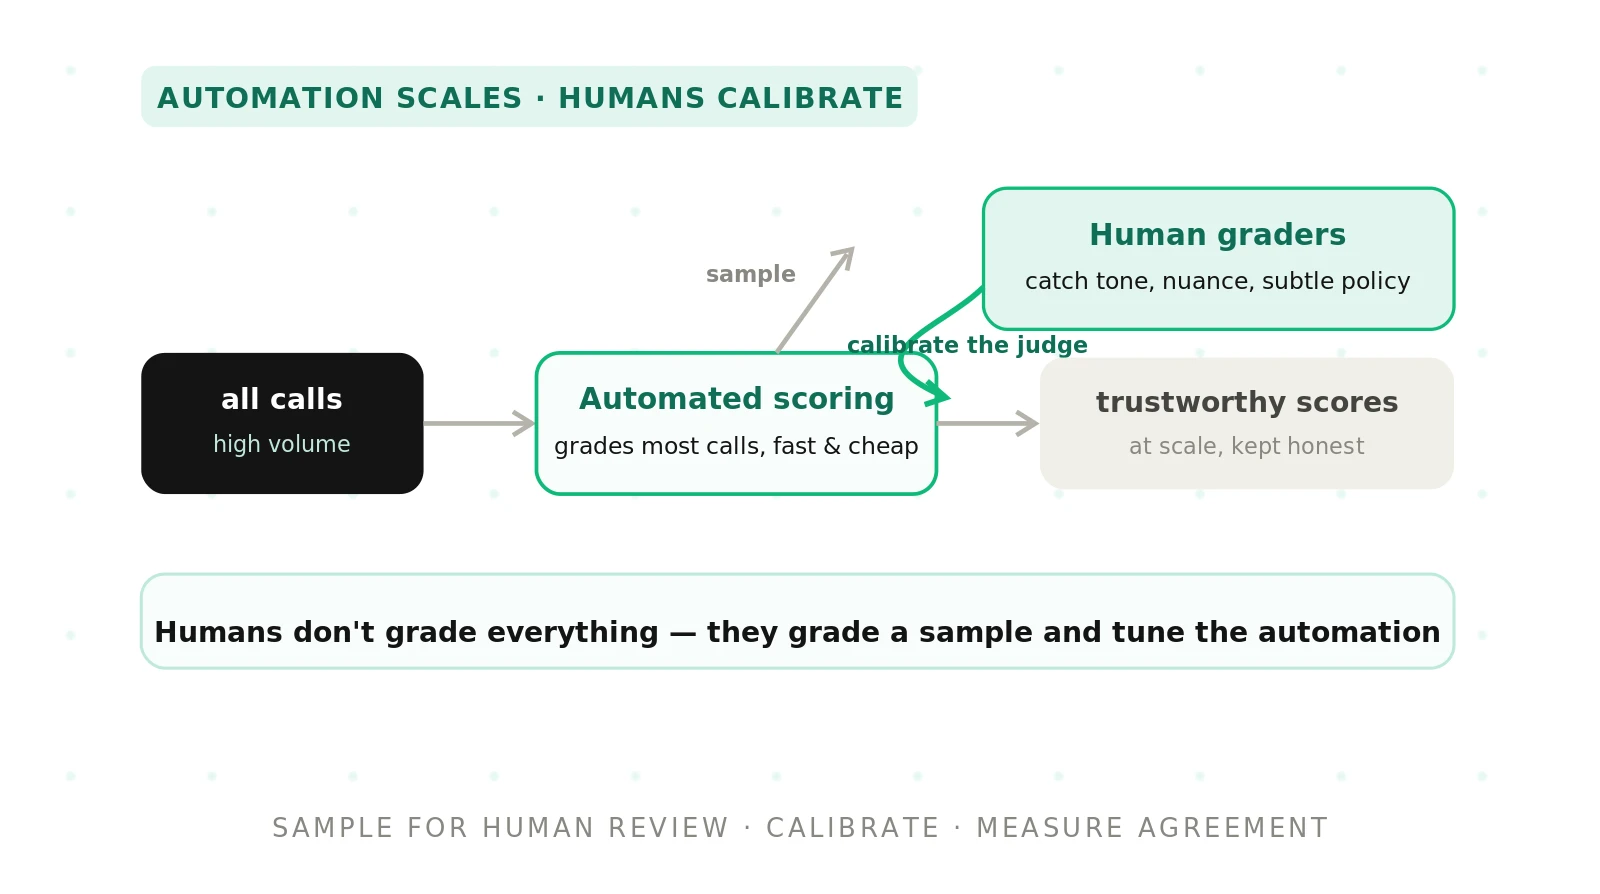
Human-in-the-Loop Evaluation for Voice Agents
Learn where humans belong in human in the loop voice agent evaluation, how to calibrate graders, tune automated scoring, and sample review to control cost.
How to Score a Voice Agent Conversation
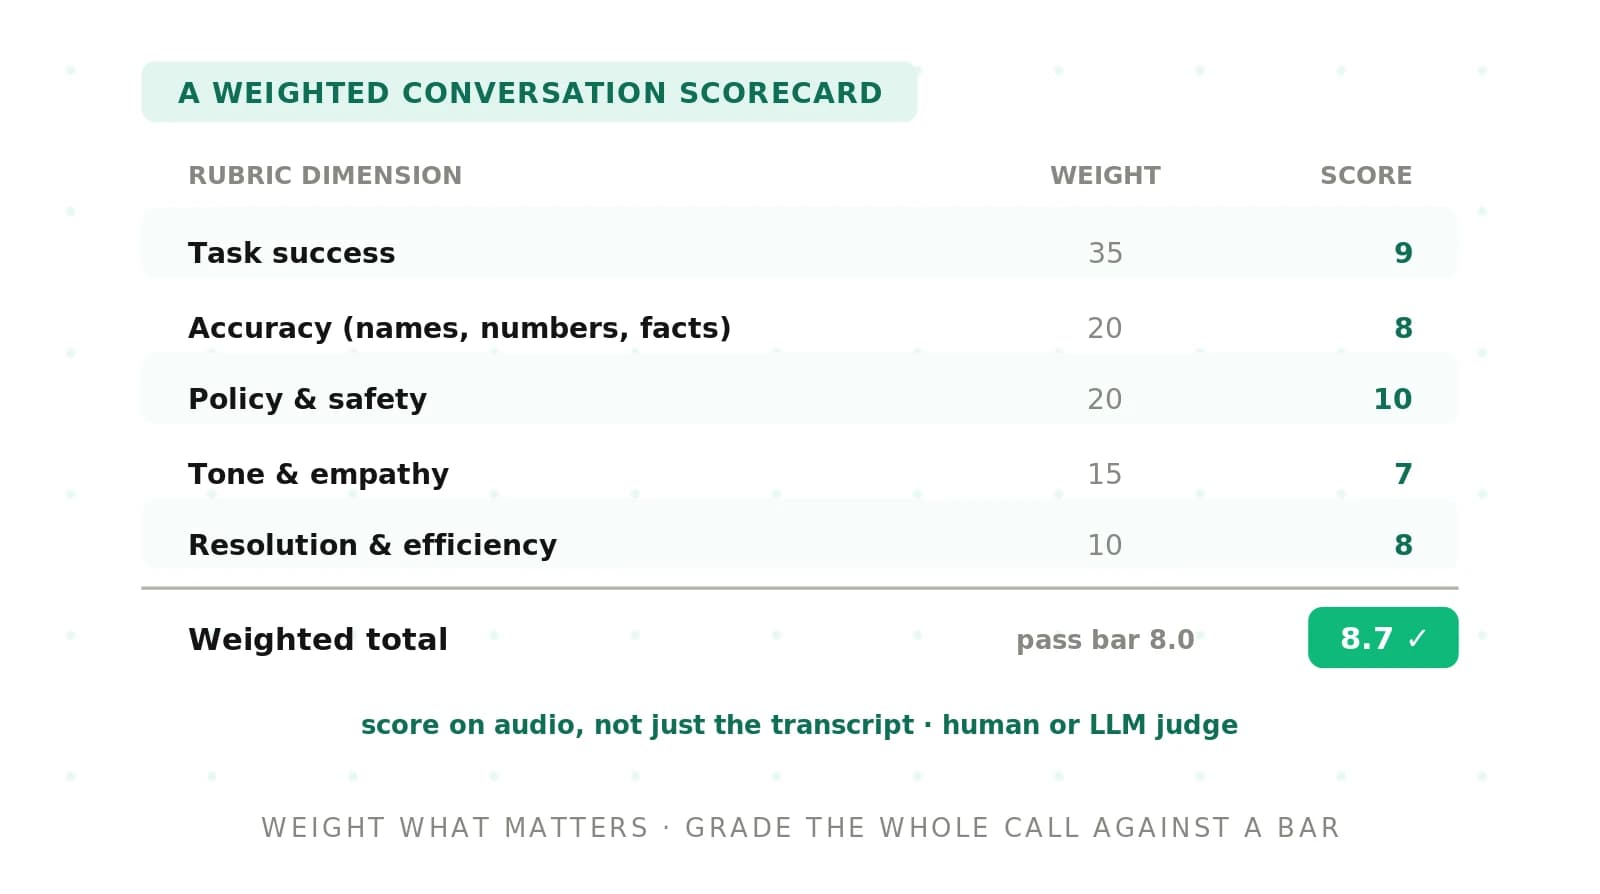
Score a voice agent conversation end to end: build a weighted rubric, set pass bars, choose a human, LLM, or hybrid scorer, and grade the audio.