Blog
Page 8 of 32
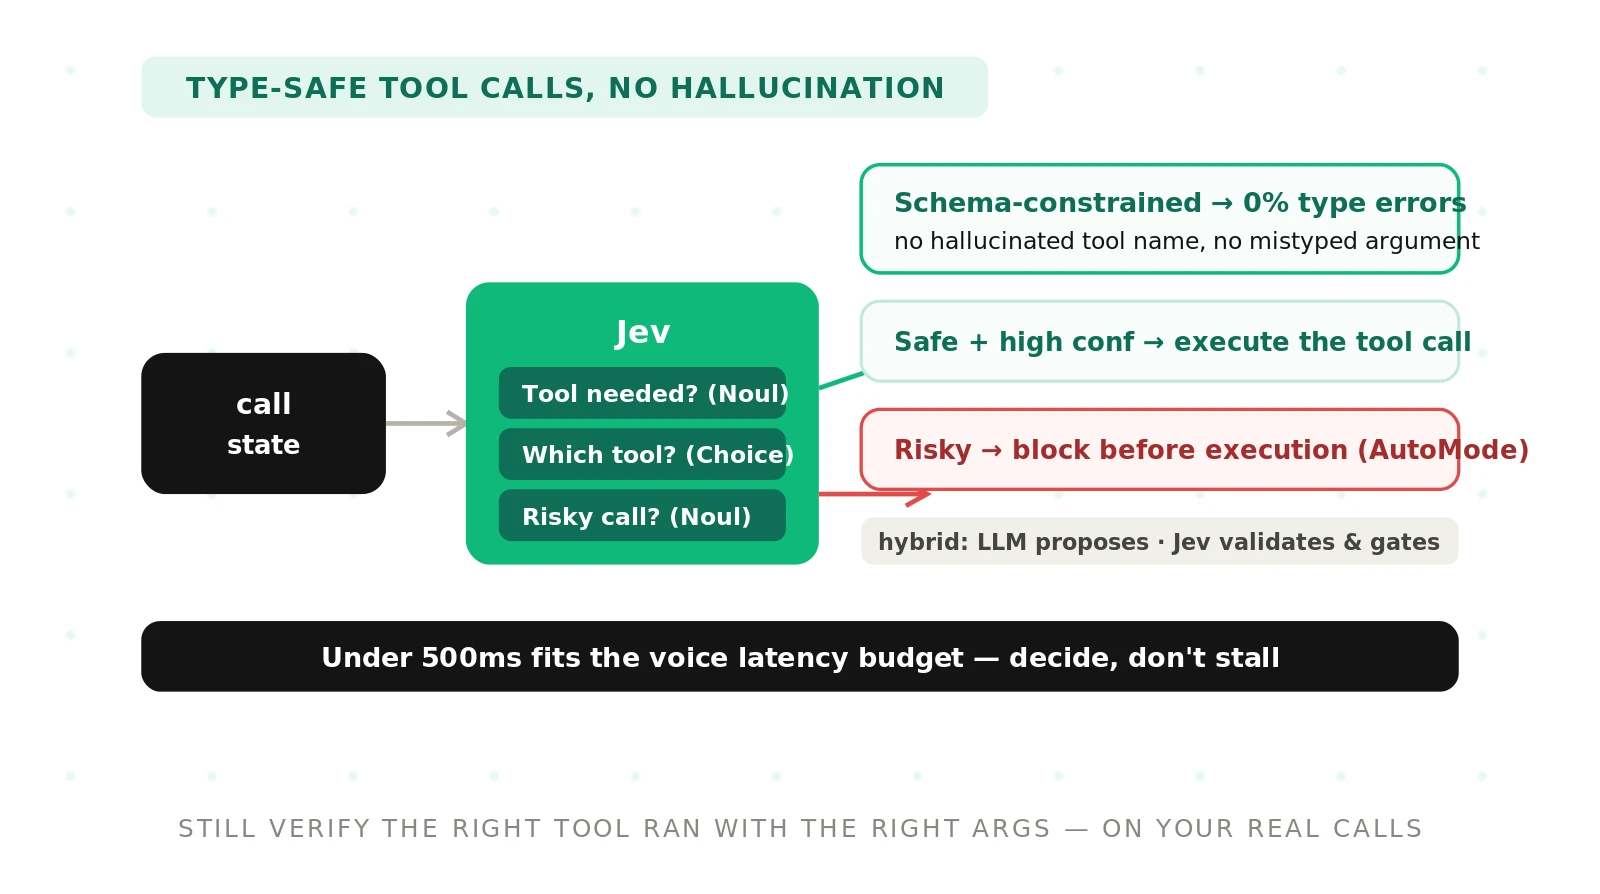
Jev for Tool Calling in AI Voice Agents
Jev cannot emit a hallucinated tool name or a mistyped value. Real requests, Python, and latency math for picking and gating tool calls in voice agents.
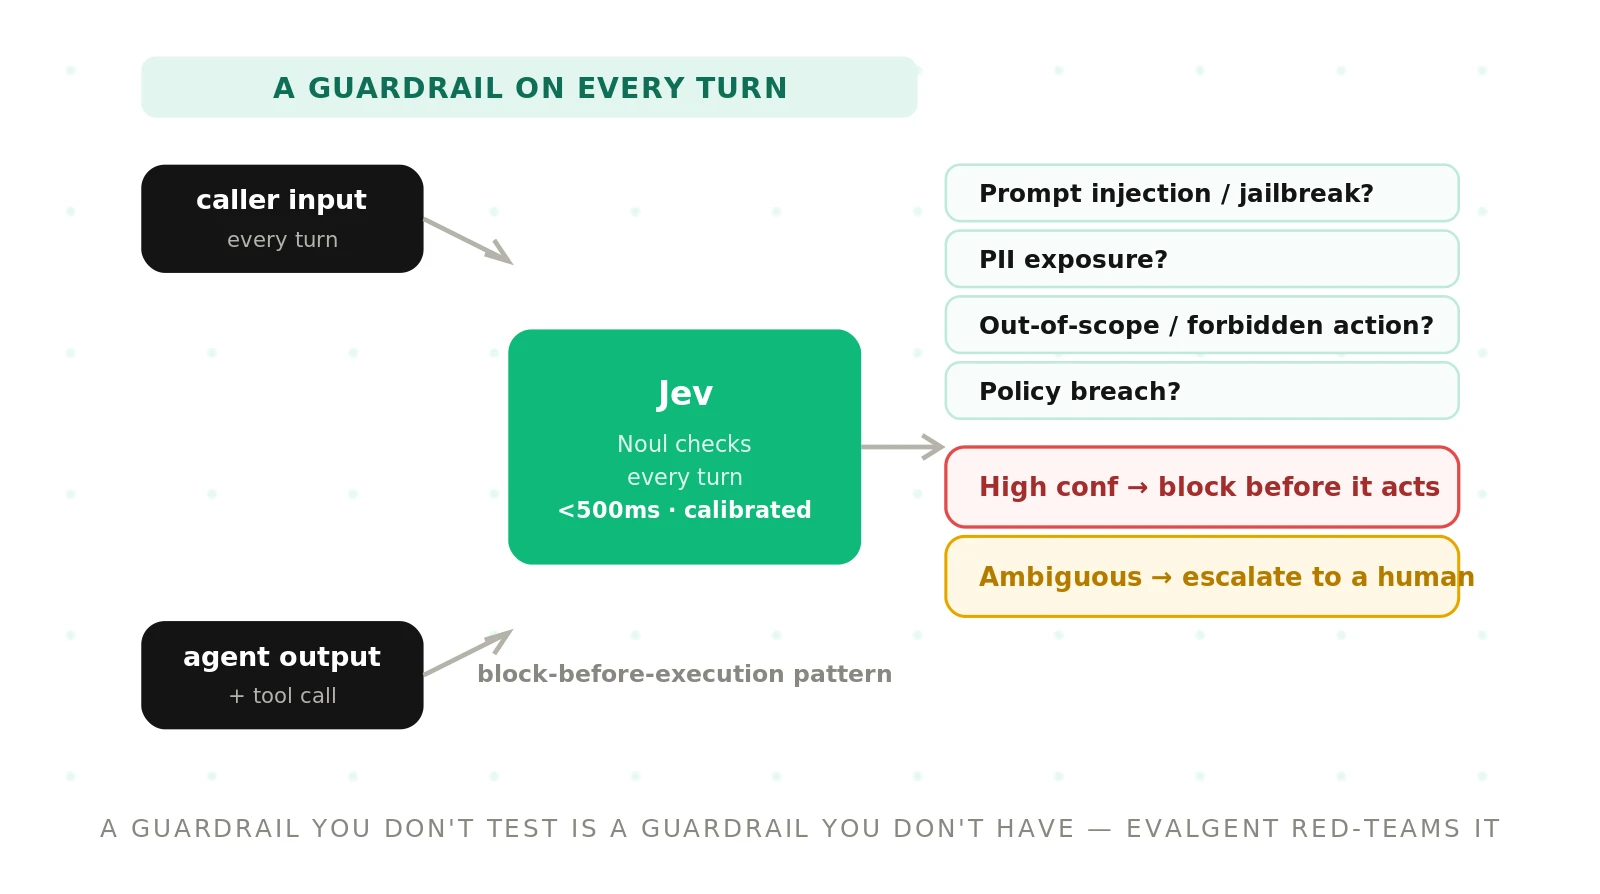
Jev for Voice Agent Guardrails and Jailbreak Detection
Jev voice agent guardrails check caller turns and tool calls in one fast call. Get code, gating logic, a threat catalog, and threshold tuning steps.
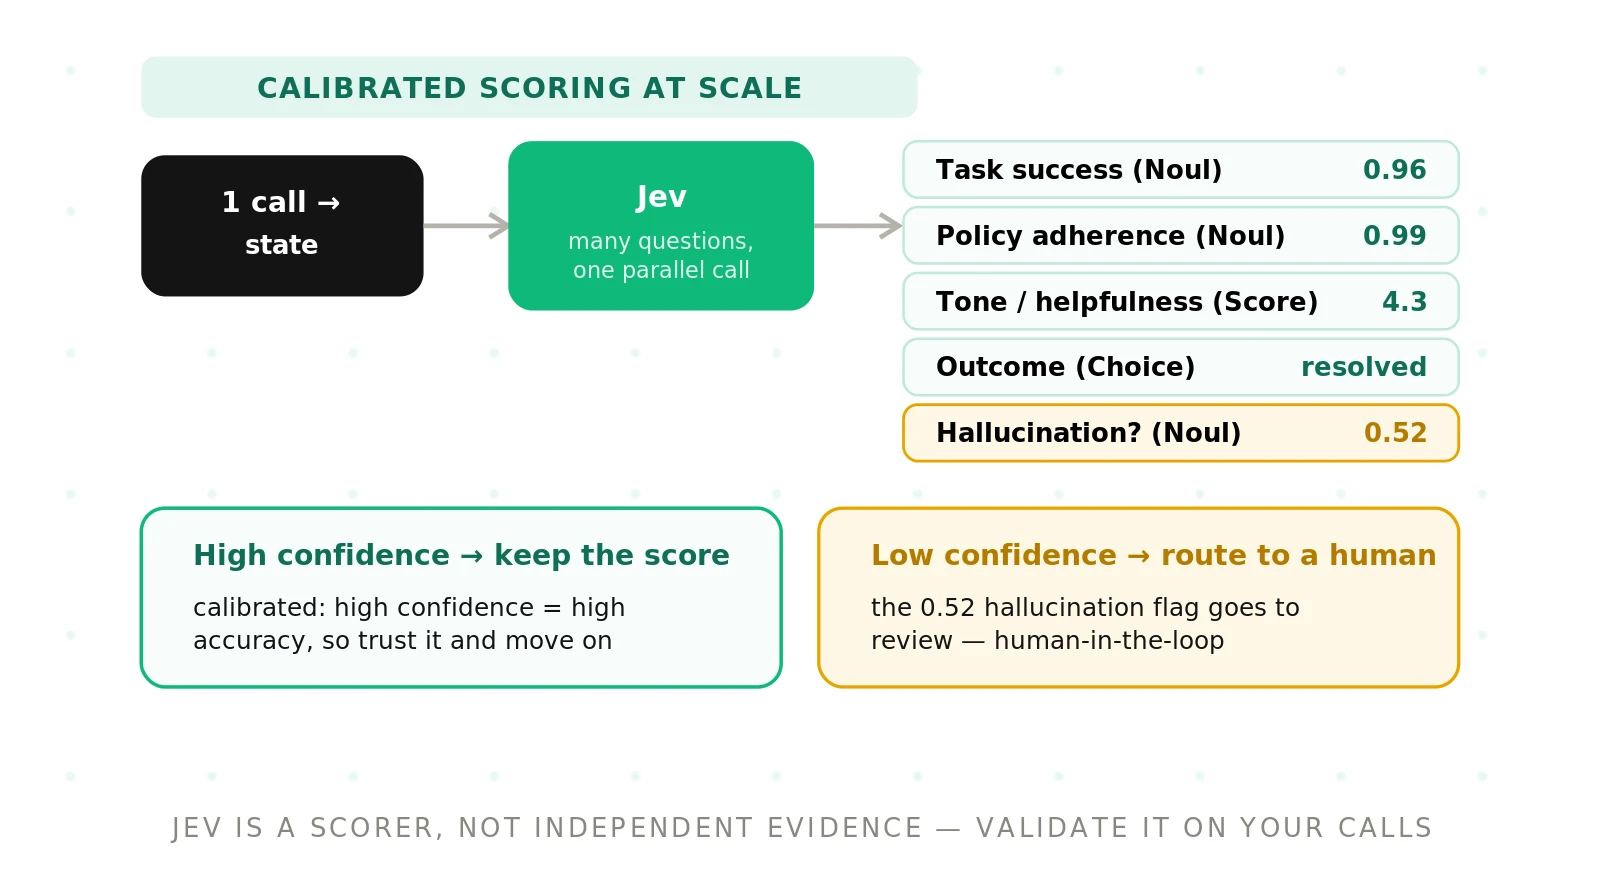
Jev for Voice Agent Evaluation: Calibrated Scoring at Scale
Jev voice agent evaluation turns each transcript into calibrated scores. Build a full rubric as Jev questions, then validate the scorer on your own calls.
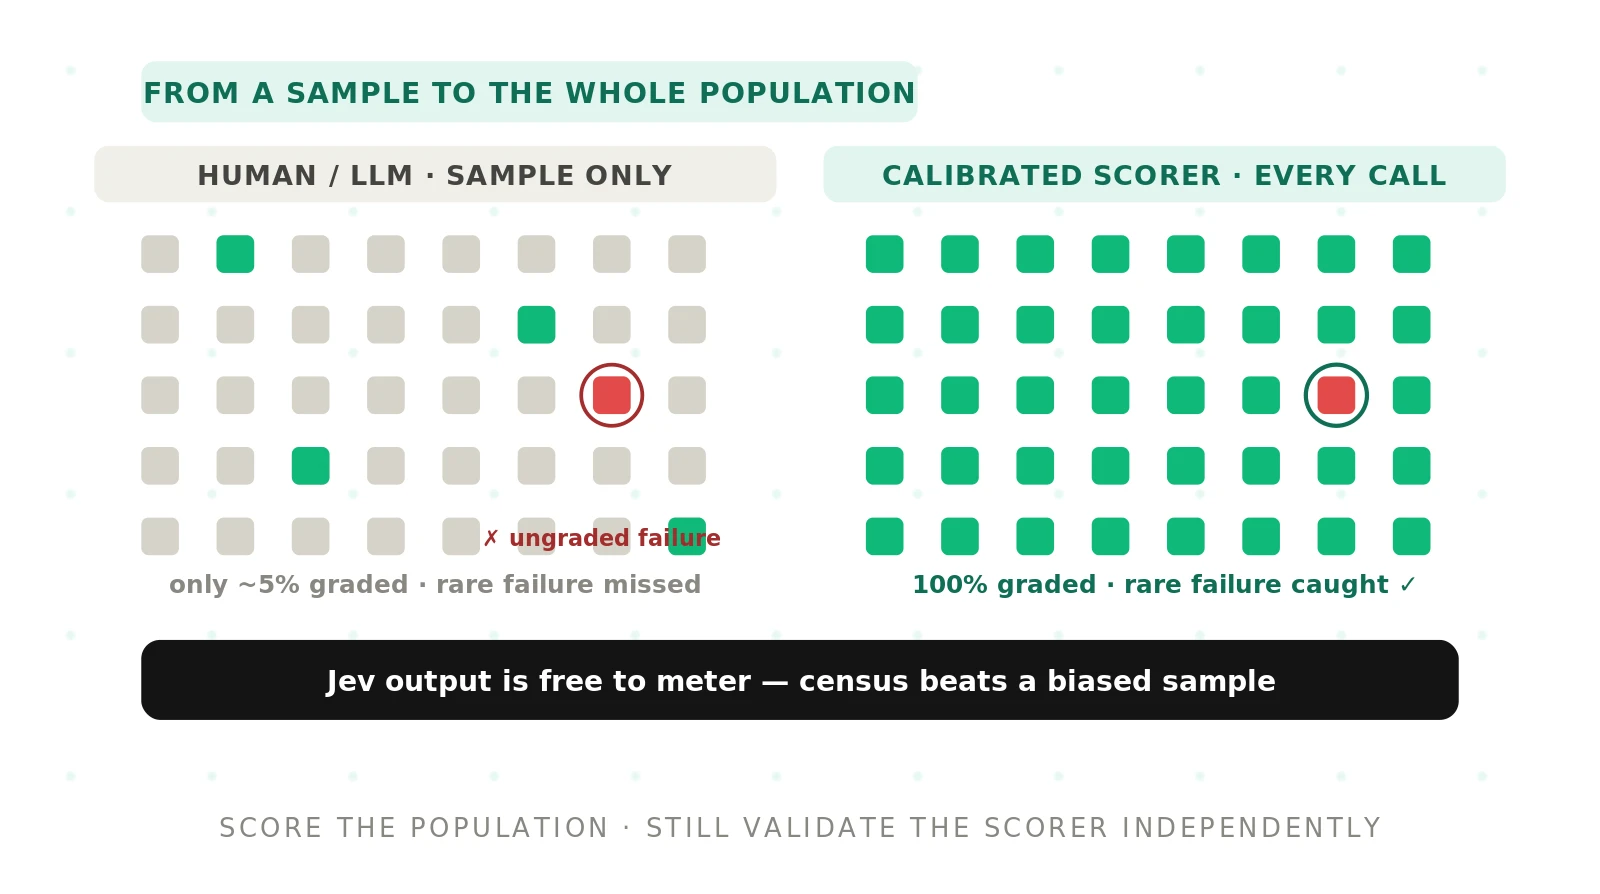
Score Every Call, Not a Sample: Voice-Eval Economics
Scoring every voice agent call now costs cents per 1,000 calls. See the worked math and the insights full coverage unlocks that a 2% sample never can.
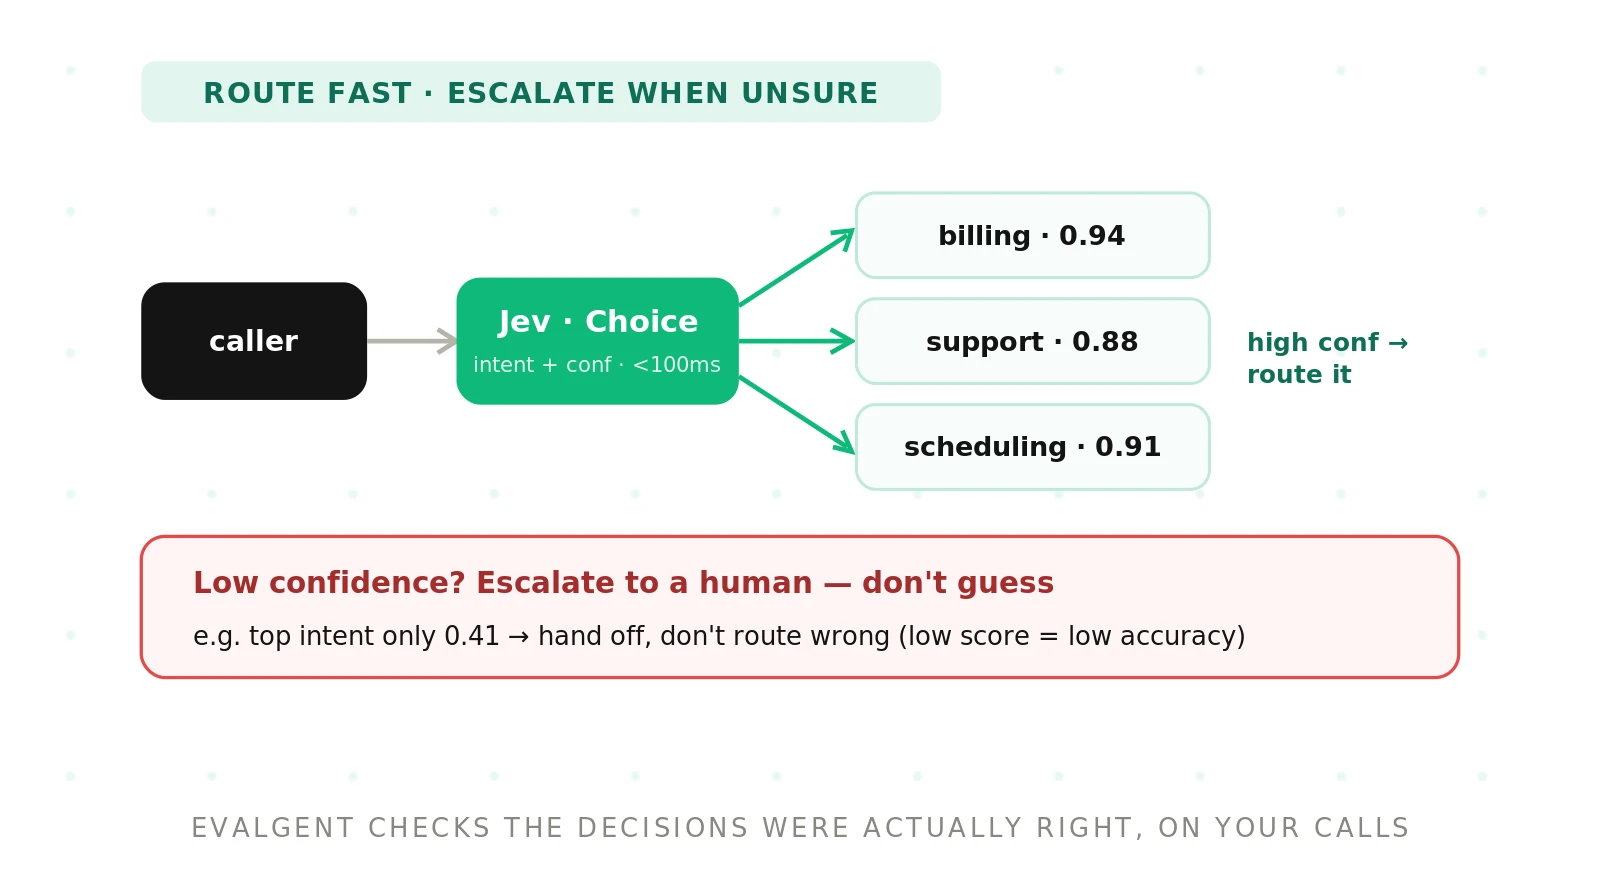
Jev for Real-Time Routing and Escalation in Voice Agents
Use Jev for real-time voice agent routing and confidence-based escalation: classify intent, route models, and escalate to a human when confidence is low.
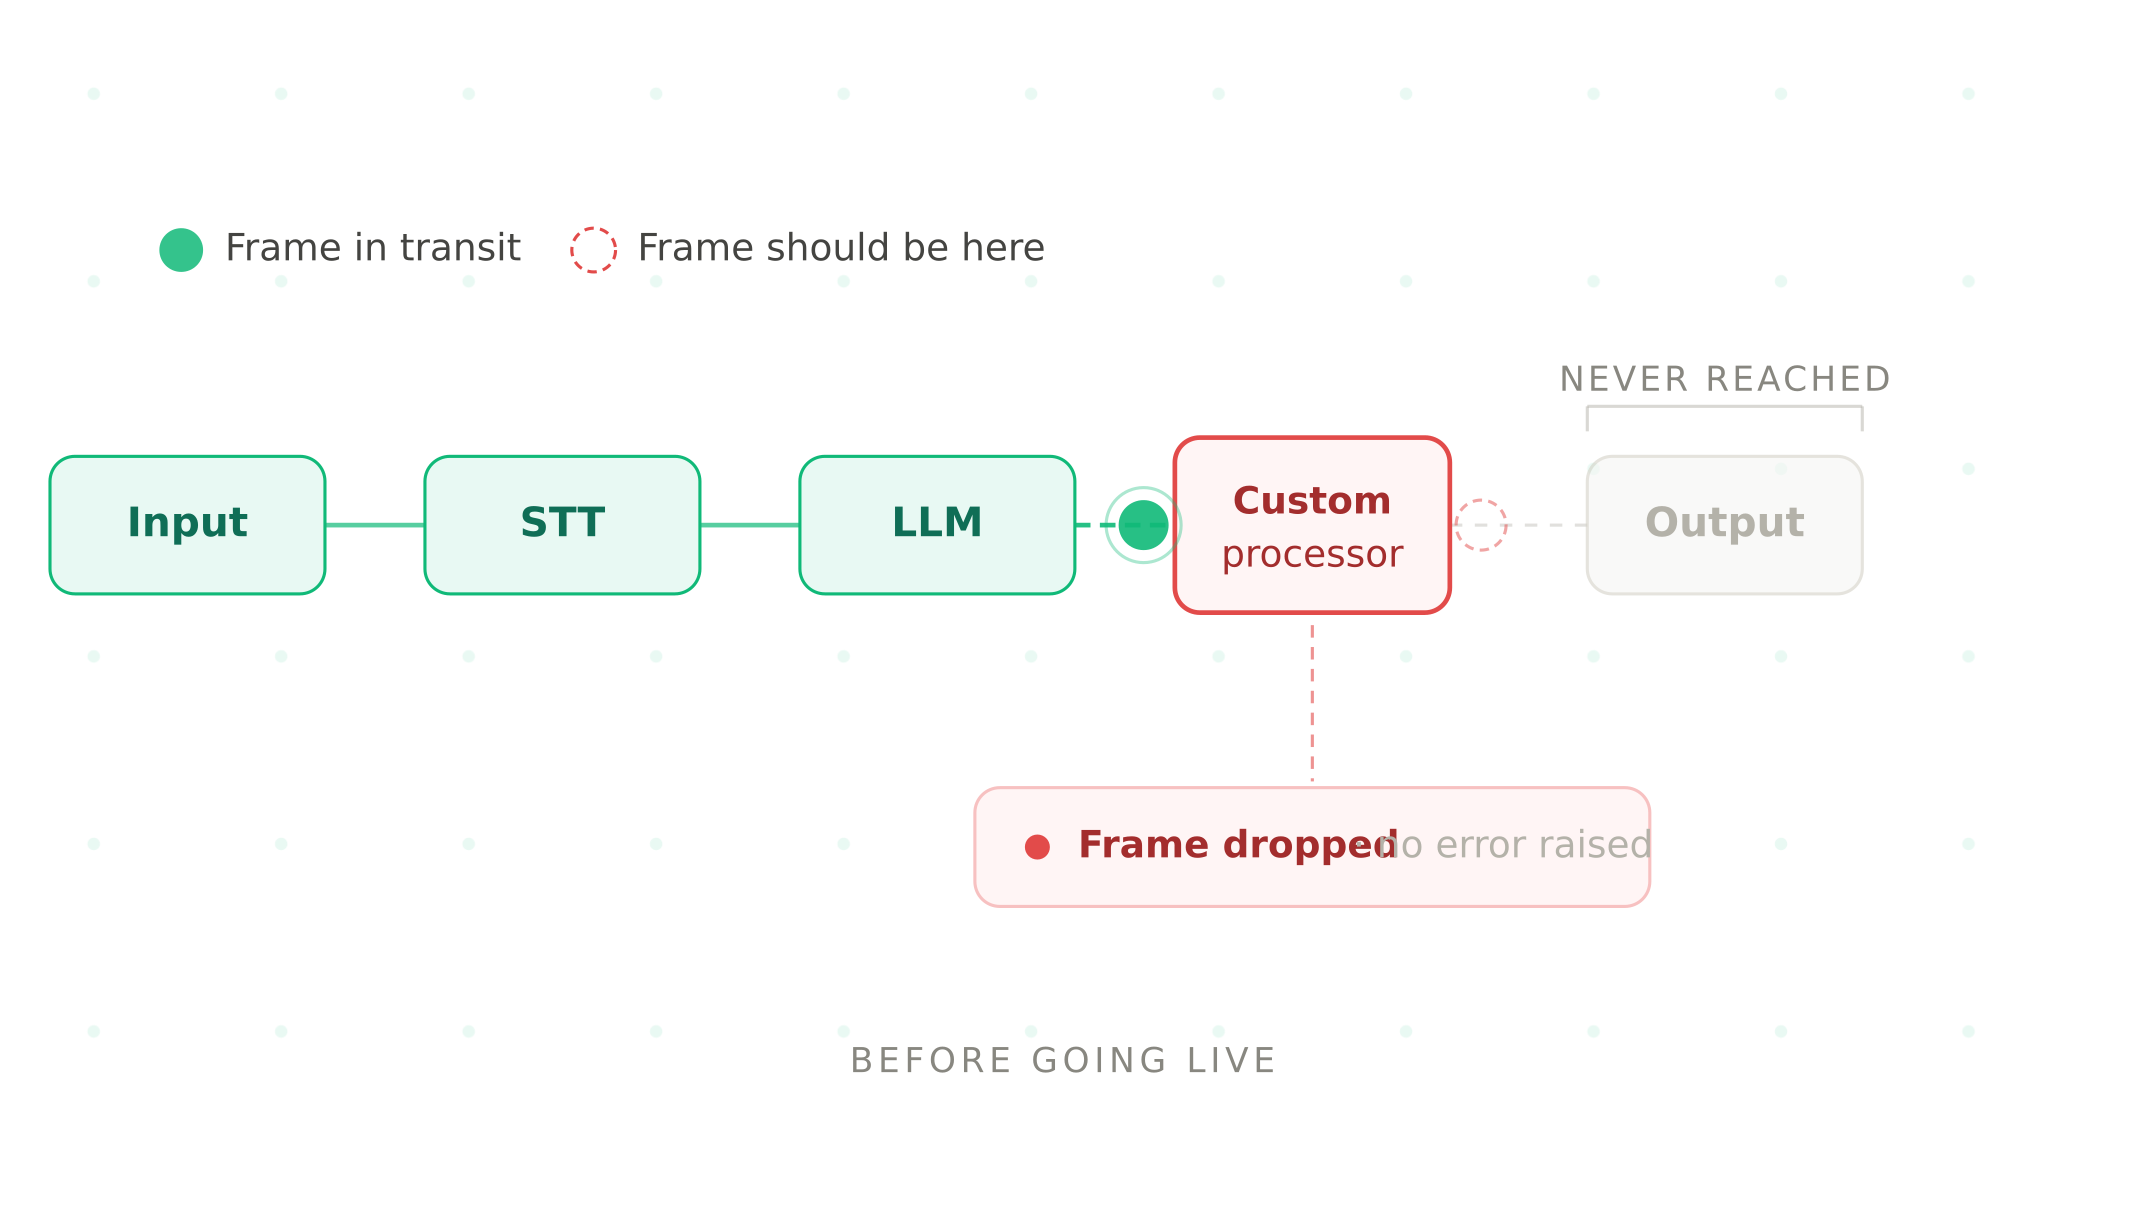
Pipecat voice agent testing guide: frames, VAD, Smart Turn, and evals (2026)
How to test a Pipecat voice agent in 2026: unit-test frame processors, tune Silero VAD and Smart Turn, run Pipecat Evals, and catch context drift.

Why AI voice agents fail in production: 9 failure layers, how to detect each, and how to prevent them
Voice agents fail in production across 9 layers, from 8 kHz audio to silent tool errors. Symptoms, root causes, alerts, and fixes in one master table.
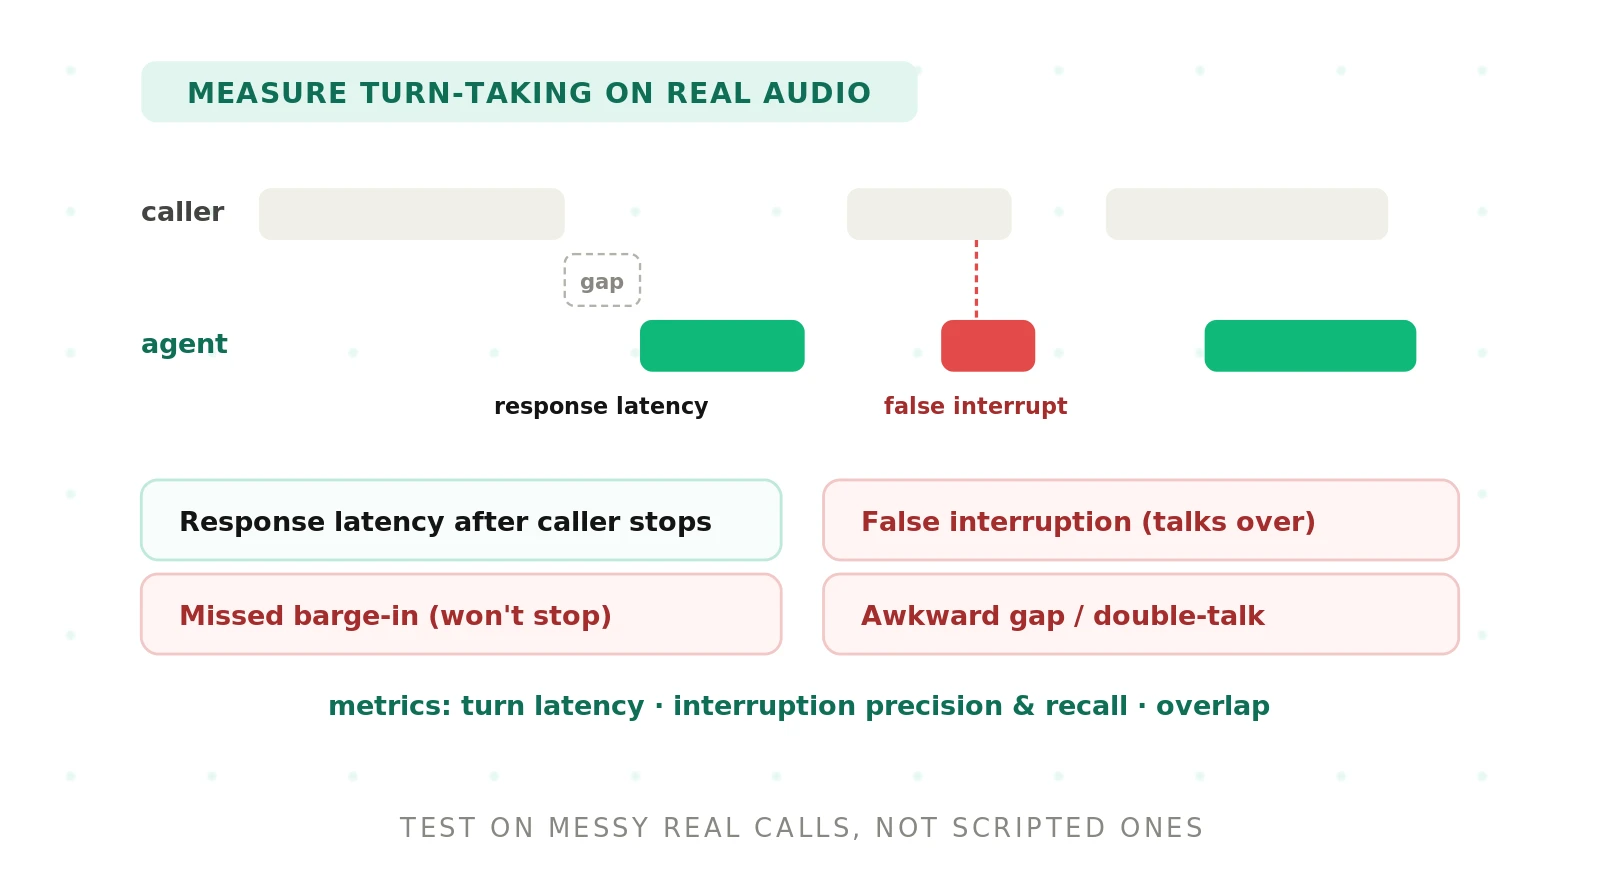
Voice Model Turn-Taking Evaluation: Metrics, Test Matrix, and FTO Code
Score voice agent turn-taking the way researchers do: floor transfer offset, false cut-ins, barge-in stop time, a test matrix, and stereo FTO code.
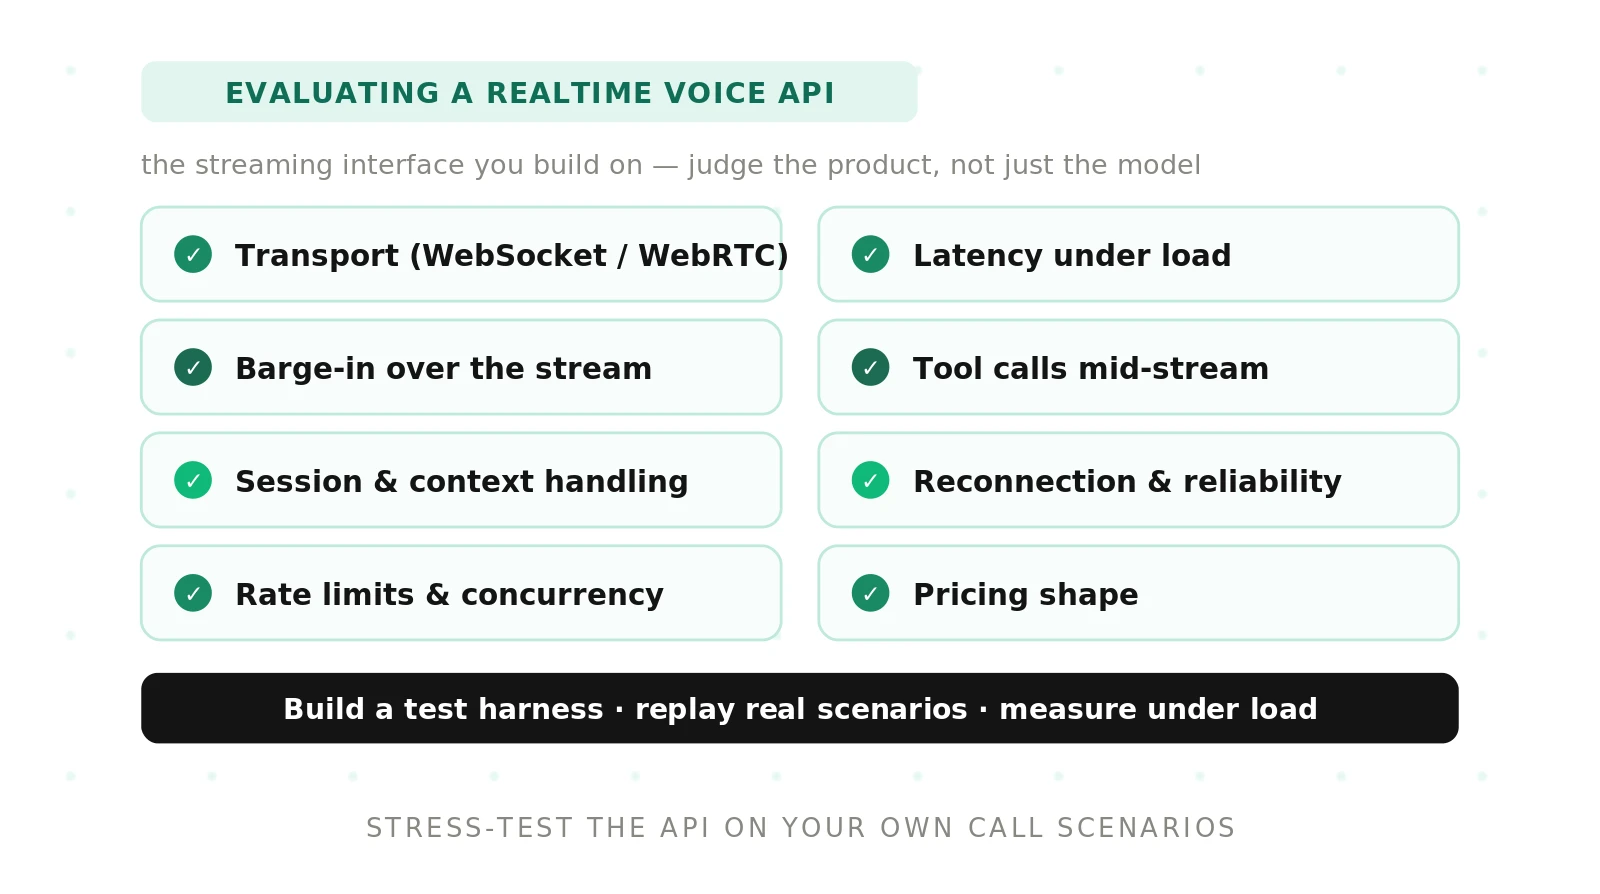
How to Evaluate a Realtime Voice API: GPT-Live, Gemini Live, Grok, Deepgram, ElevenLabs Compared
Compare realtime voice APIs on mechanics, not demos: transport, event protocols, VAD, truncation, async tools, session limits, and true per-minute cost.