Blog
Page 35 of 37
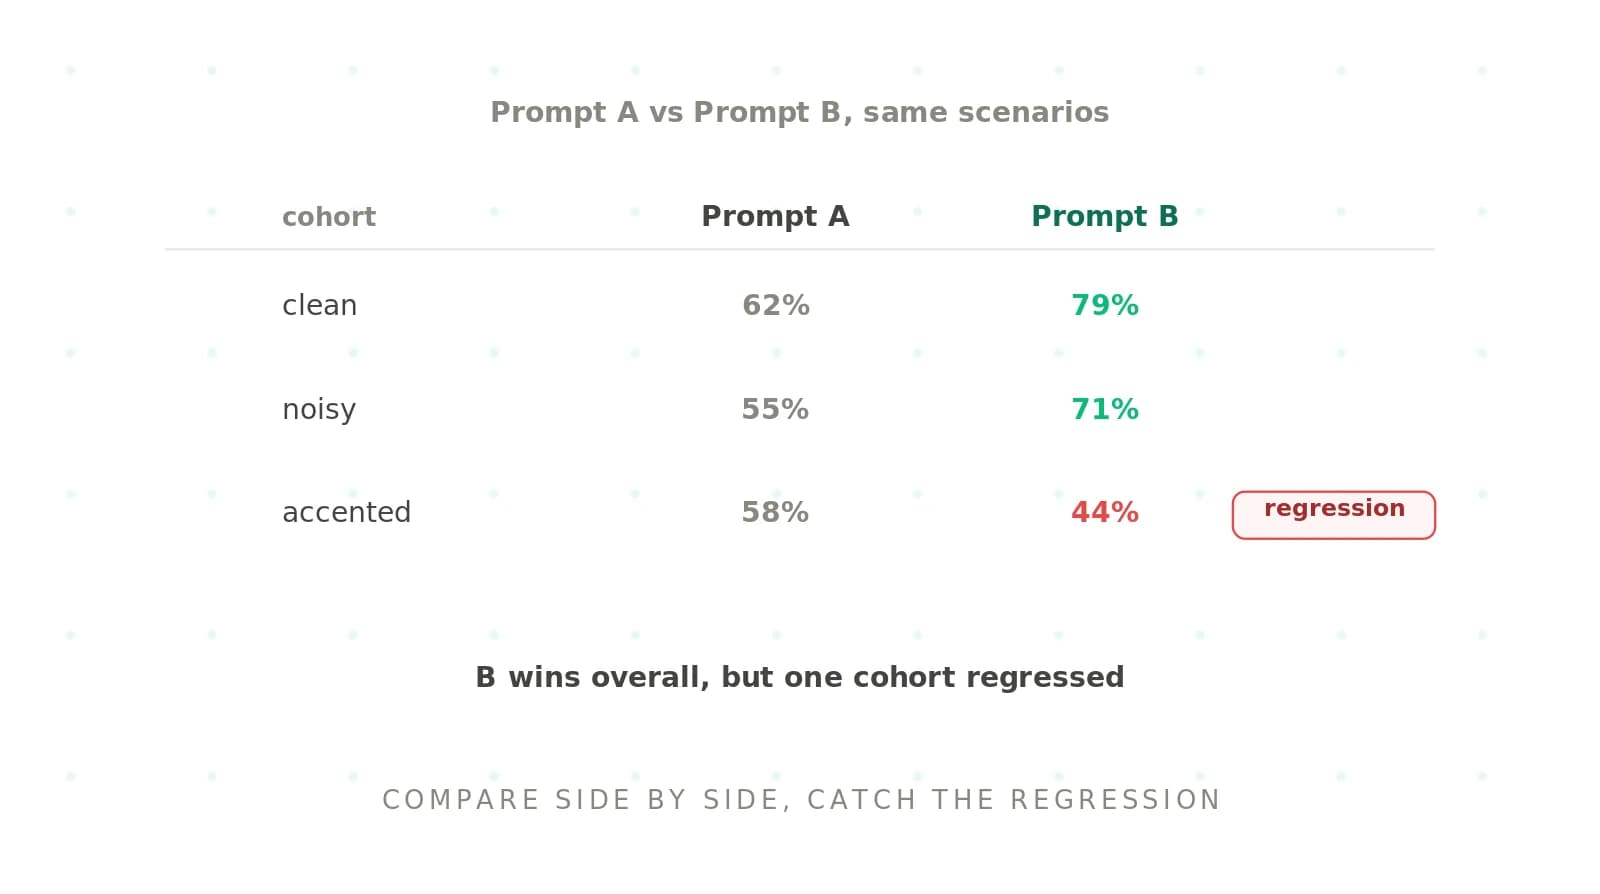
Voice agent prompt comparison: how to test prompt changes side by side
Voice agent prompt comparison runs two prompts on the same calls to find the winner. Learn side-by-side testing, catching regressions, and the tooling.
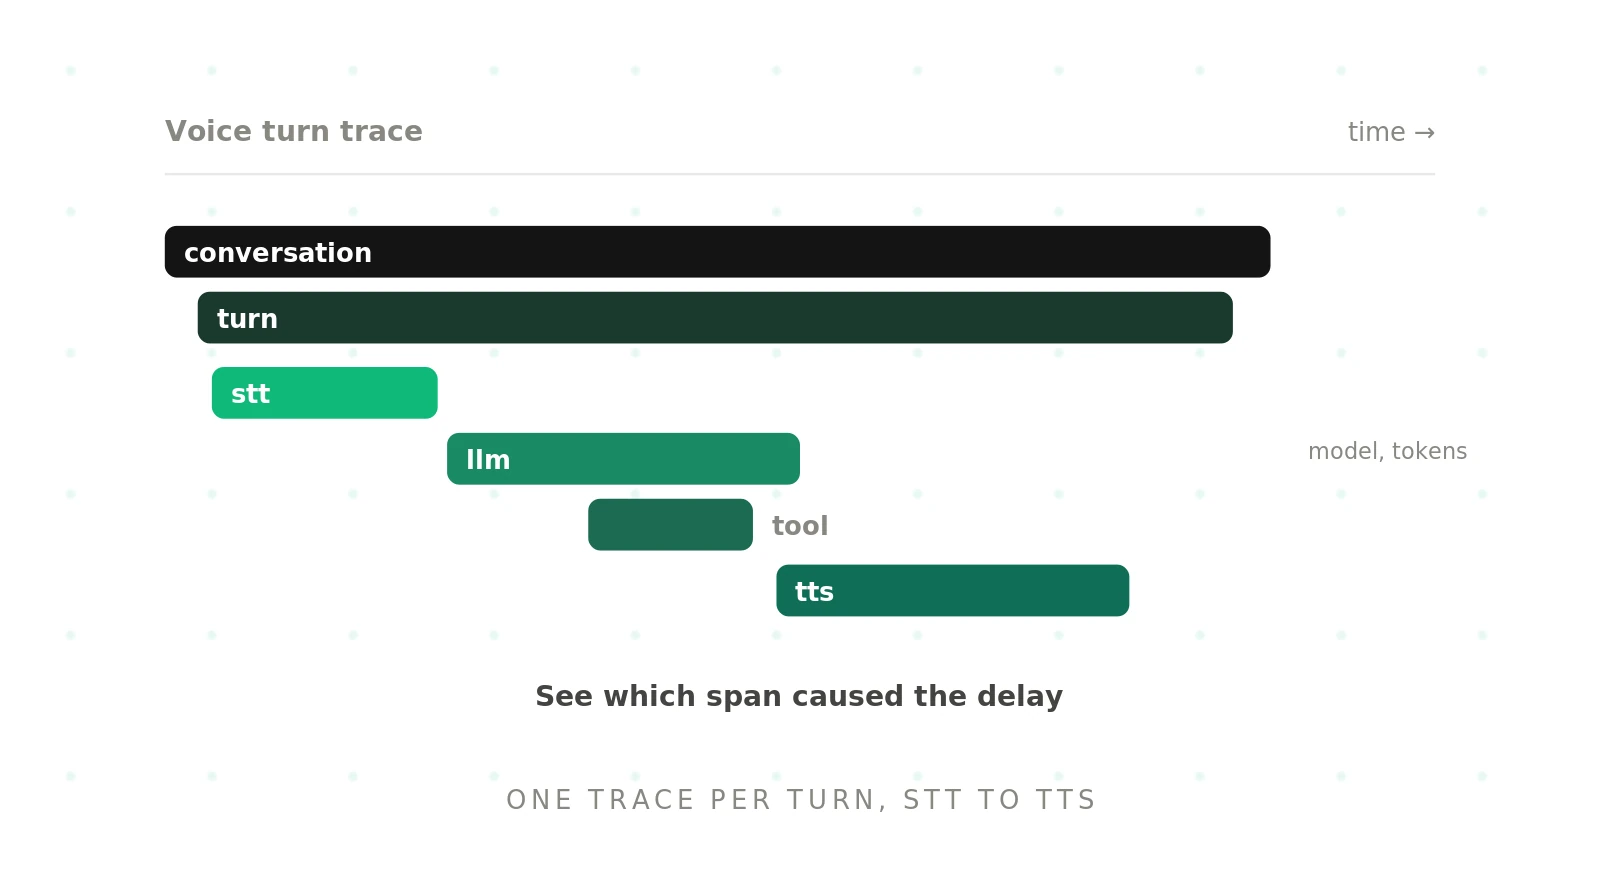
OpenTelemetry observability for AI voice agents
OpenTelemetry for voice agents traces every turn across STT, LLM, and TTS. Learn the GenAI conventions, the spans to emit, and how to instrument it.
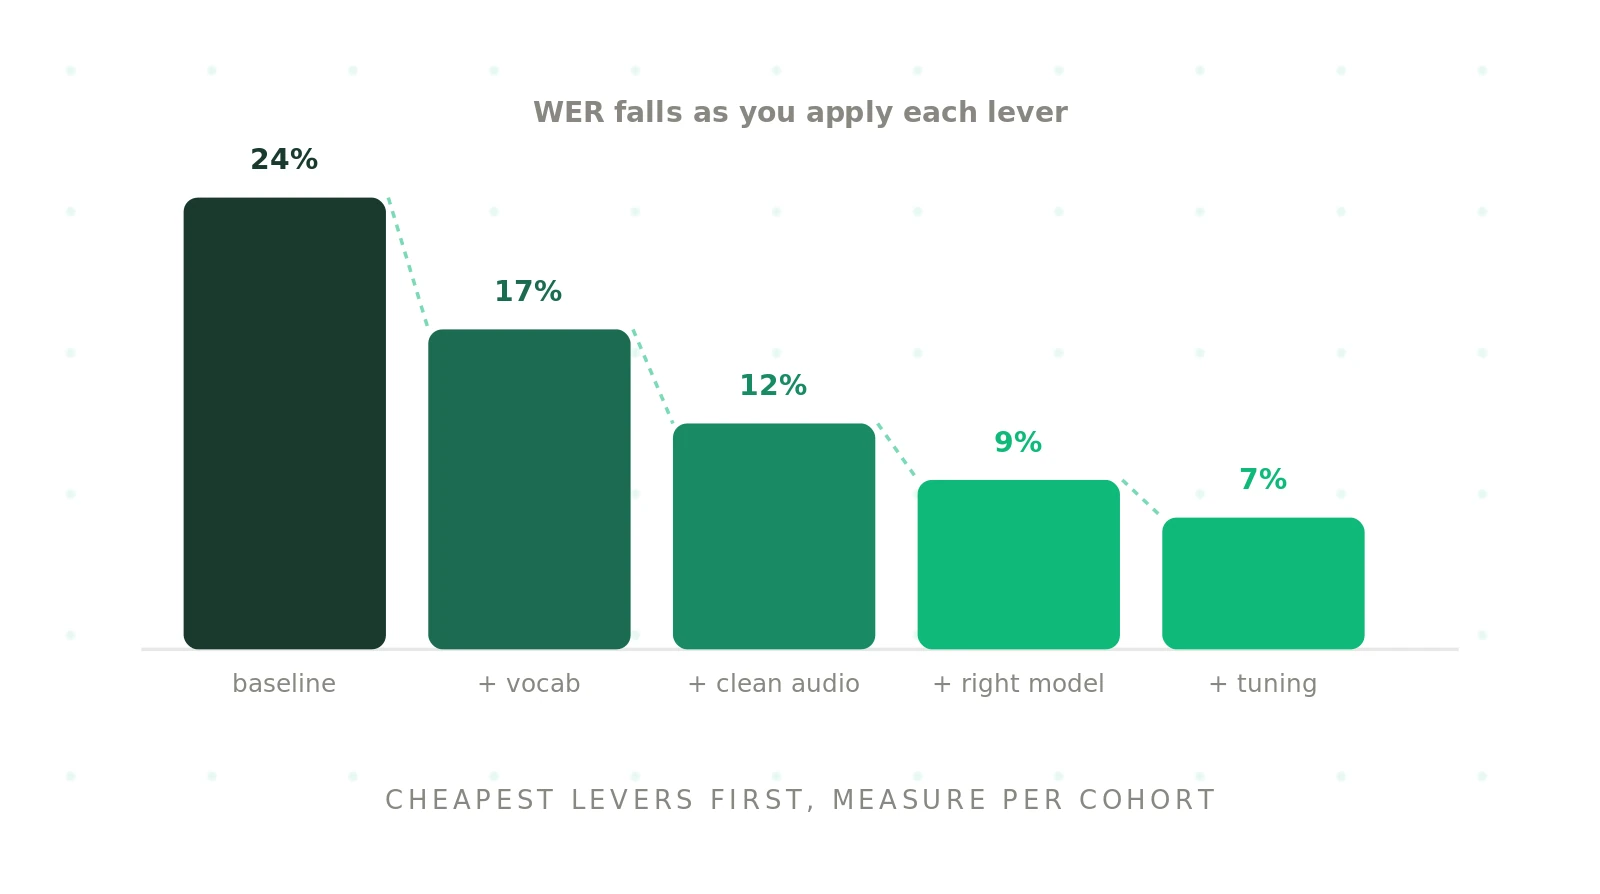
How to improve WER: reducing word error rate for voice agents
Improve WER for your voice agent with custom vocabulary, cleaner audio, model choice, and tuning. A practical guide to reducing word error rate per cohort.
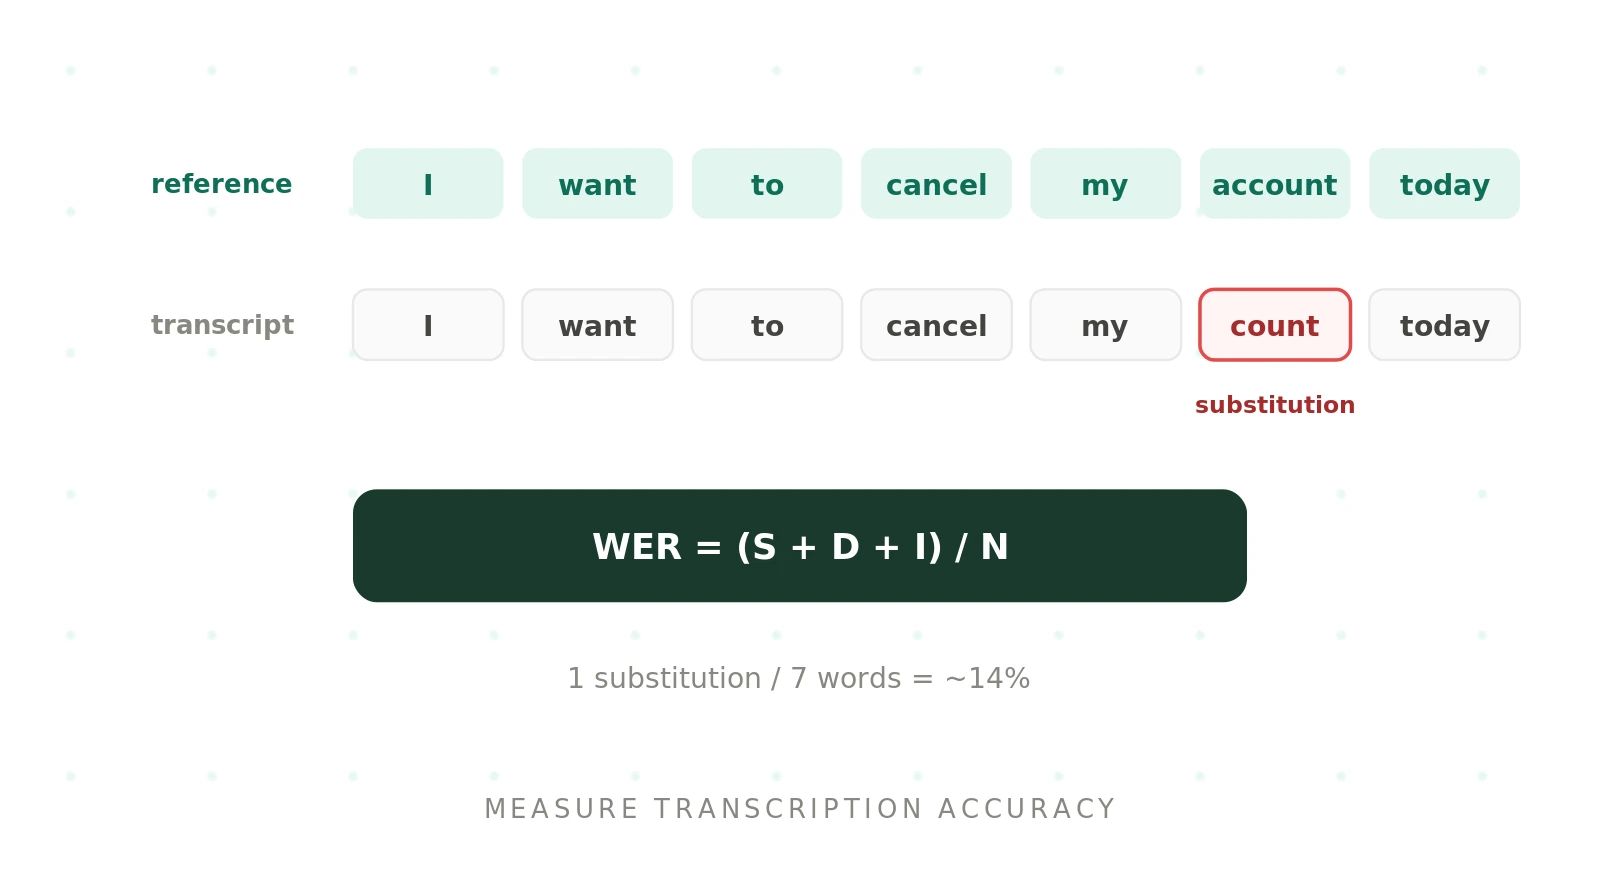
Word error rate (WER): the complete guide for voice agents
Word error rate measures speech-to-text accuracy via substitutions, deletions, and insertions over total words. Learn how to calculate it and its limits.
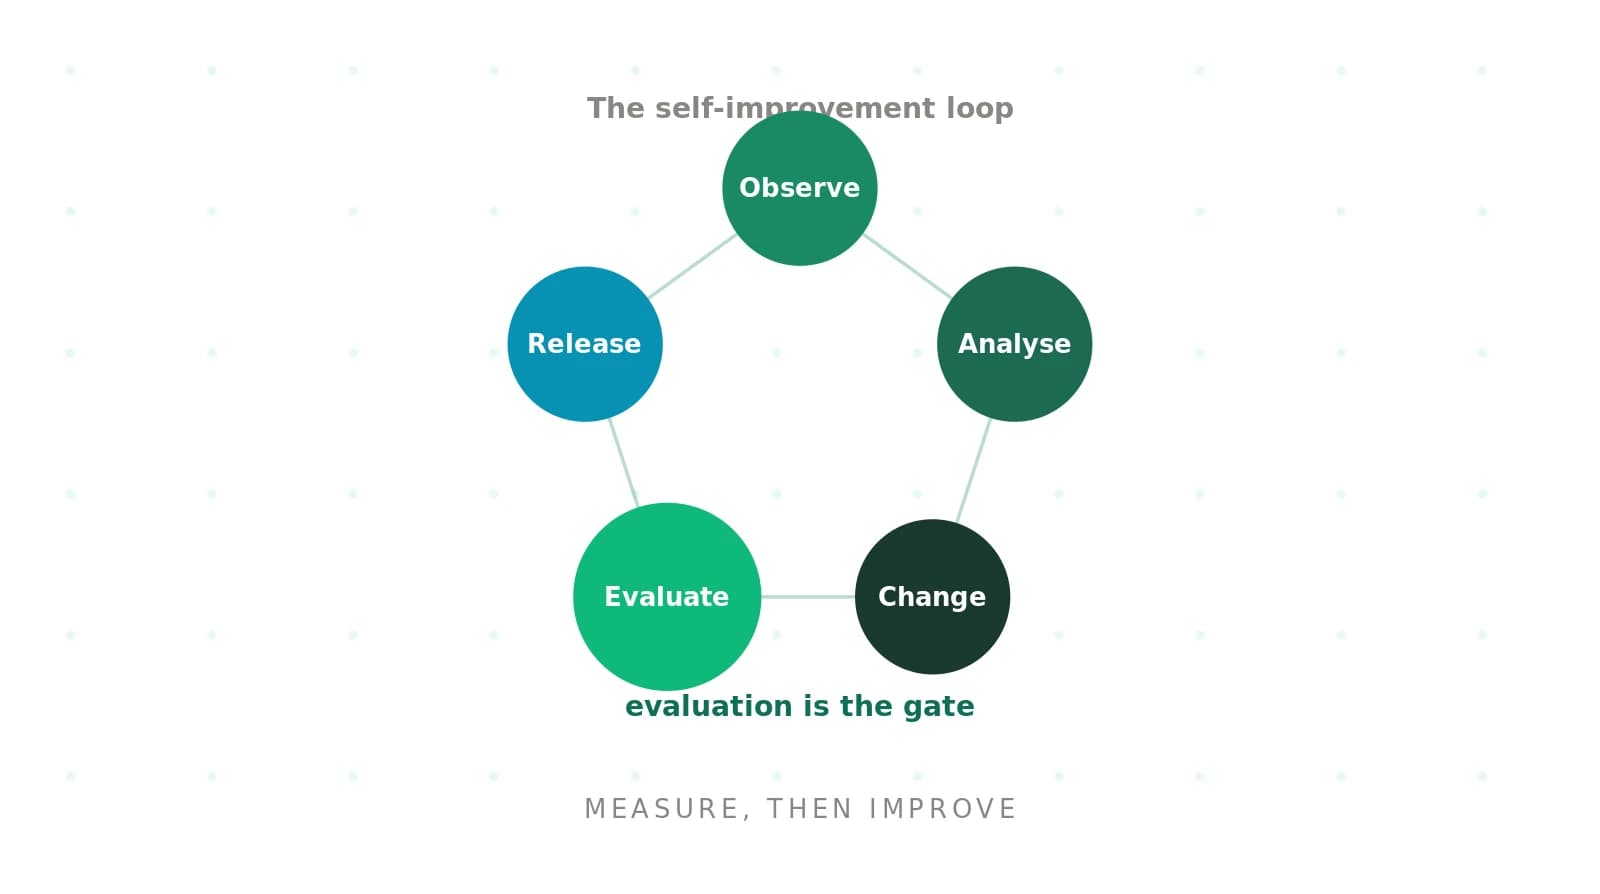
Self-improving voice agents: how feedback loops make agents better
Self-improving voice agents get better from production feedback. Learn how the loop works, where it differs from retraining, and how to keep it safe.
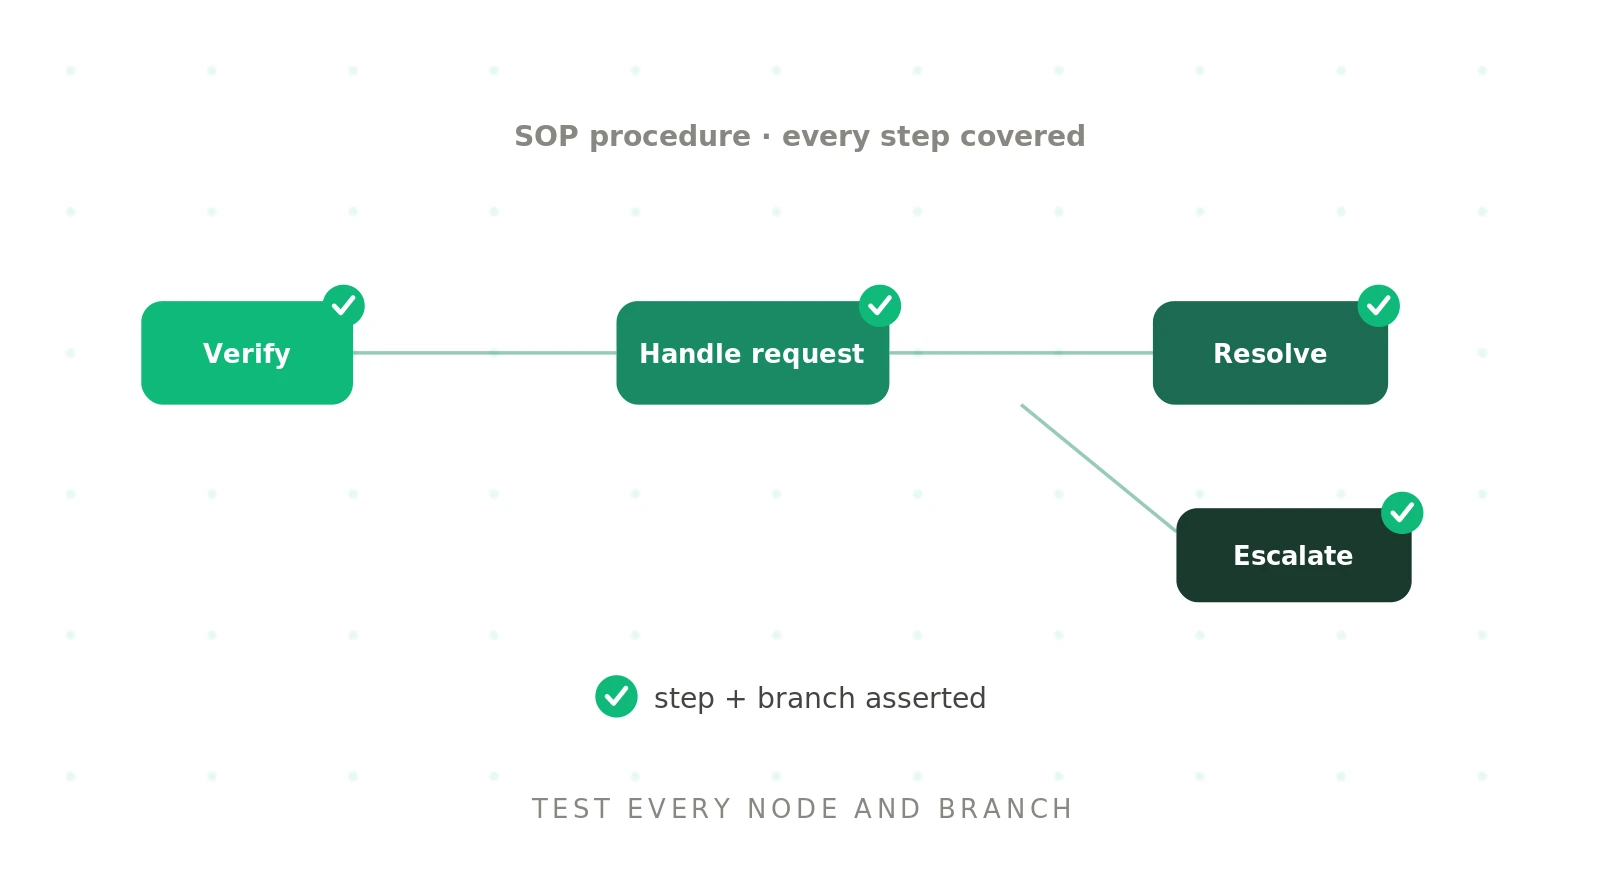
Testing SOP-based voice agents: how to verify procedure adherence
Testing SOP-based voice agents means verifying every step and branch of the procedure. Learn SOP adherence testing, step coverage, and metrics.
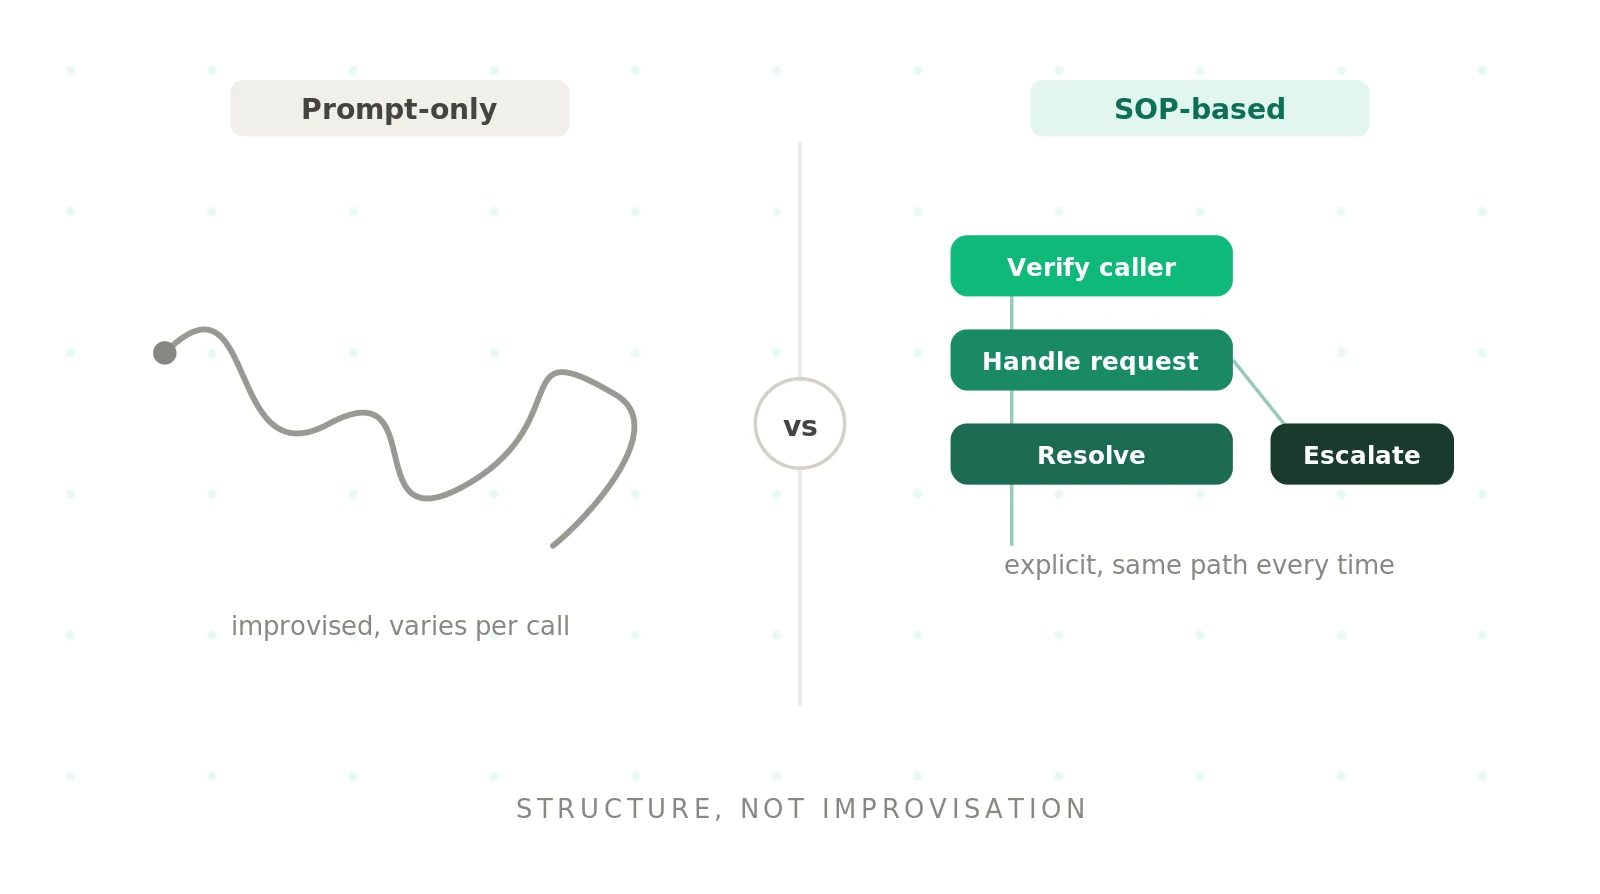
SOP-based voice agents: how standard operating procedures make agents reliable
SOP-based voice agents follow standard operating procedures instead of relying on a prompt. Learn how SOPs improve reliability, control, and testability.
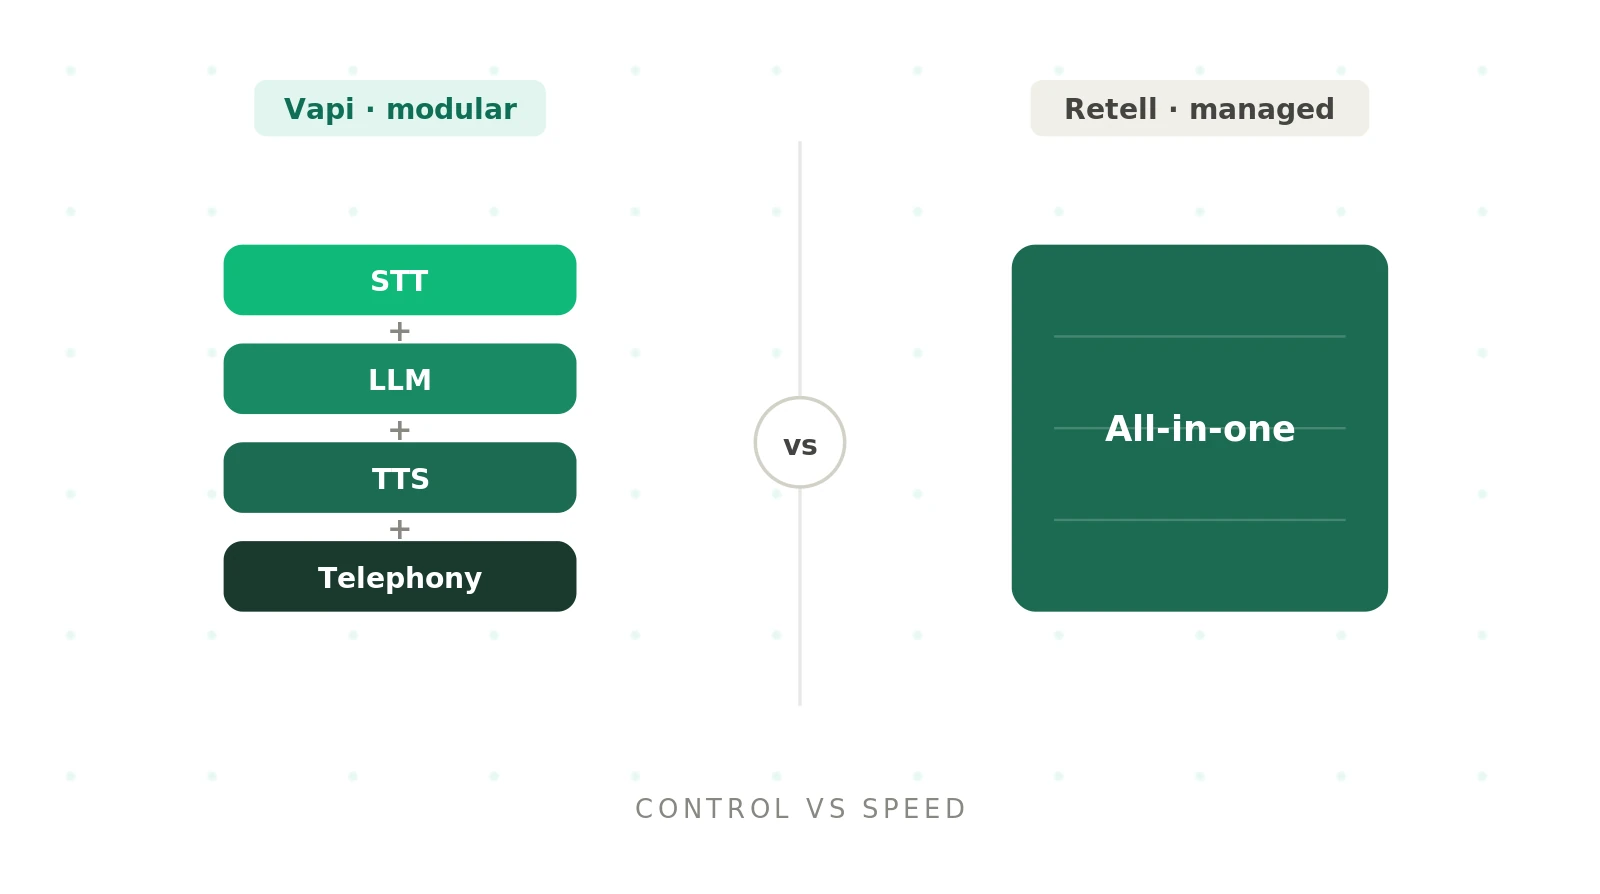
Vapi vs Retell: which voice agent platform should you choose?
Vapi vs Retell compared on architecture, pricing, latency, telephony, and scale. A clear decision framework for choosing a voice agent platform in 2026.
Testing Graph-Based Voice Agents: The Three-Tier Model
Testing graph-based voice agents requires three tiers — node, subgraph, end-to-end voice. Most teams stop at tier one. Here's what production-grade looks like.