Blog
Page 18 of 47
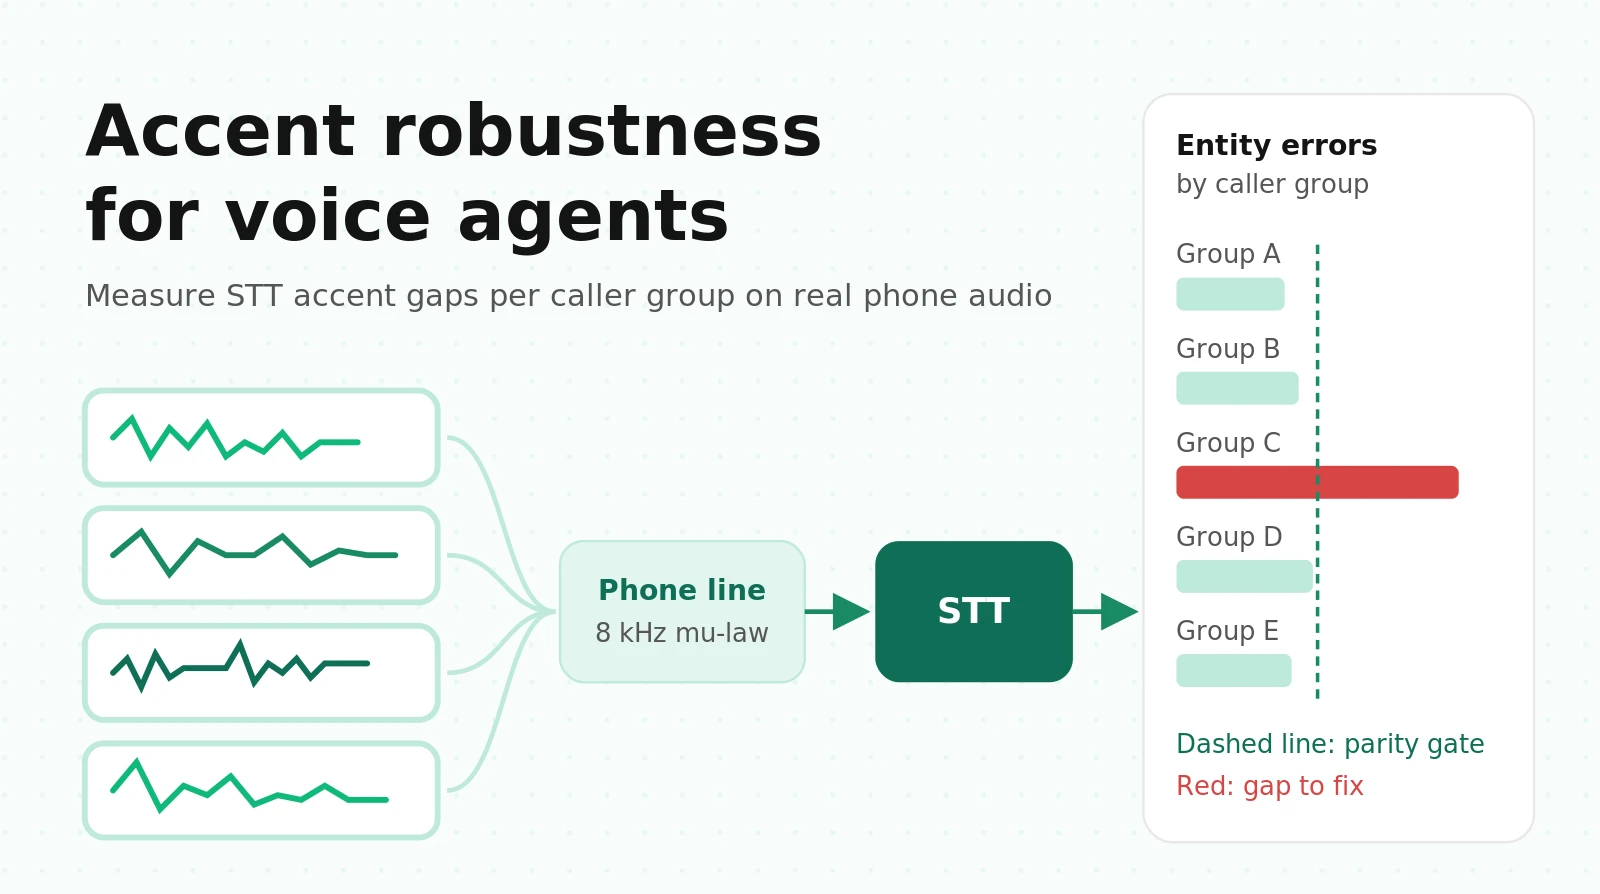
Accent Robustness for Voice Agents: Finding and Fixing Speech Recognition Accent Bias on US Calls
How STT accent errors break voice agents on US phone calls, what the research measured, and how to test, monitor and fix accent gaps with real numbers.
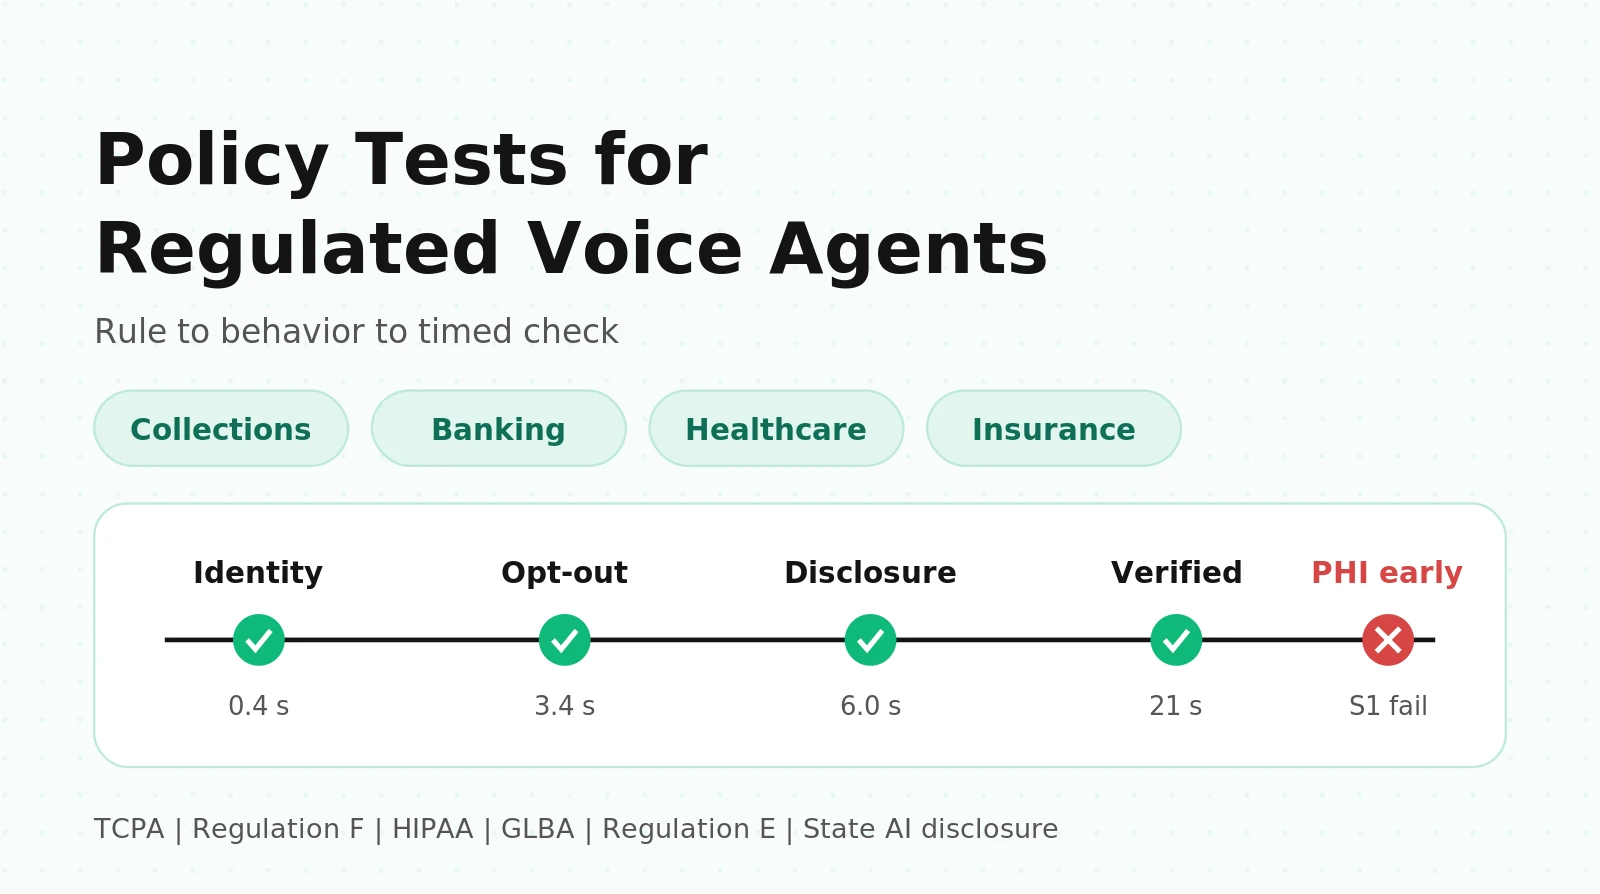
Voice Agent Compliance Testing: Policy and Guardrail Test Cases for Financial Services, Healthcare, Insurance and Collections
Voice agent compliance testing, rule by rule: TCPA, Reg F, HIPAA, GLBA and insurance test cases with pass criteria, scoring, severity and timing code.
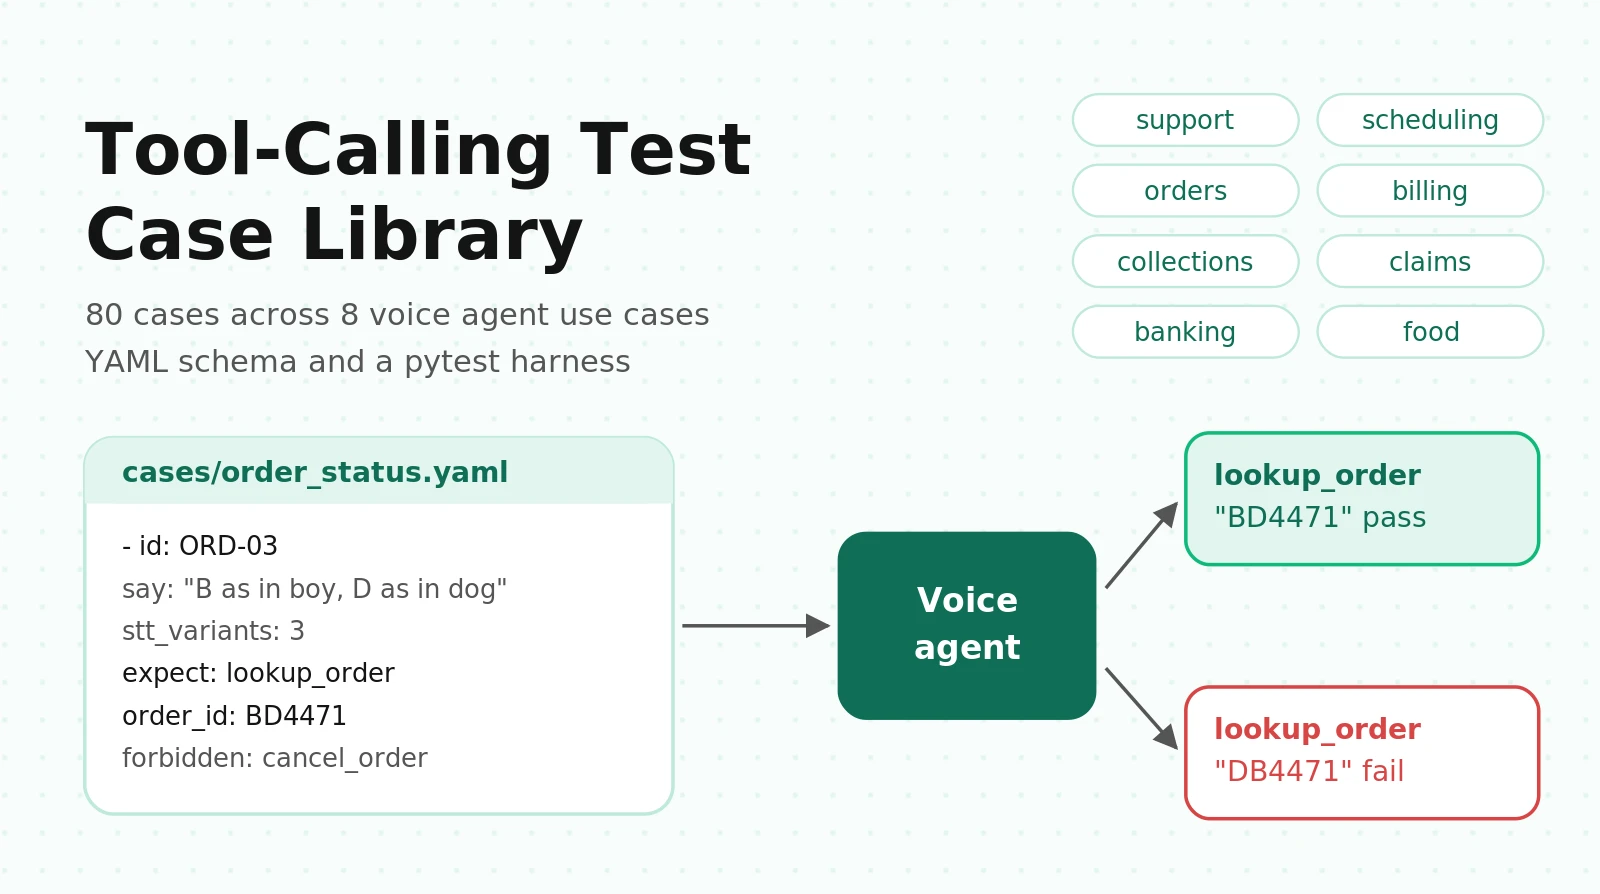
Voice Agent Tool Calling Test Cases: A Copyable Library for 8 Use Cases
80 copyable voice agent tool calling test cases for support, scheduling, orders, billing, collections, claims, banking and food, with YAML and pytest.
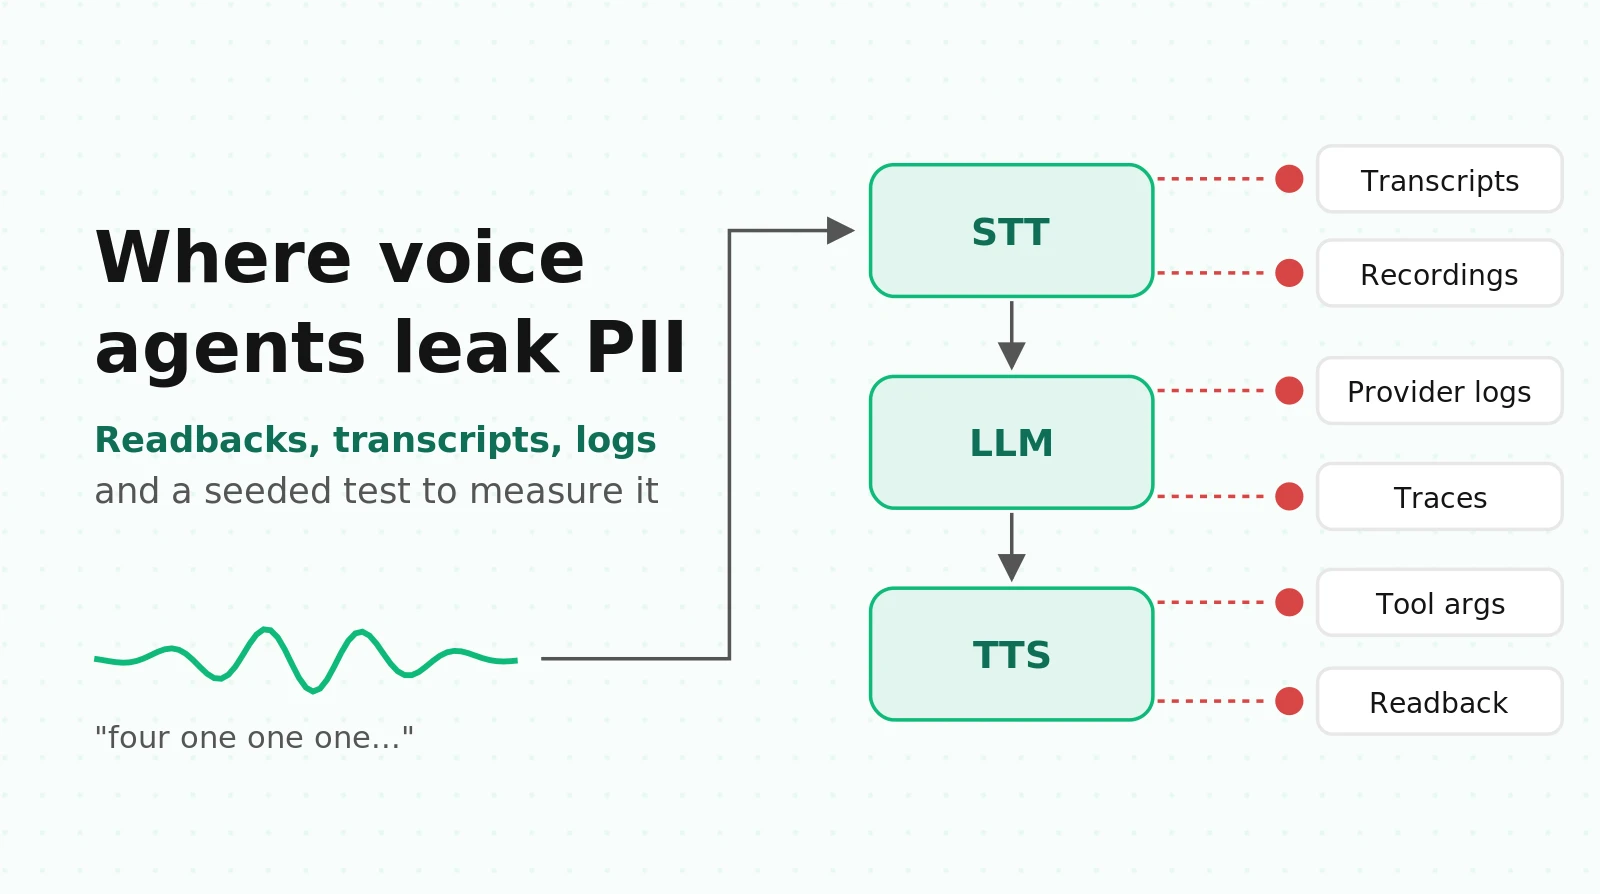
Voice Agent PII Redaction: Detecting Leaks in Spoken Readbacks, Transcripts and Logs
Where voice agents leak card numbers and SSNs: readbacks, STT, LLM logs, recordings, traces. Redaction failure modes, detection code, seeded test plan.
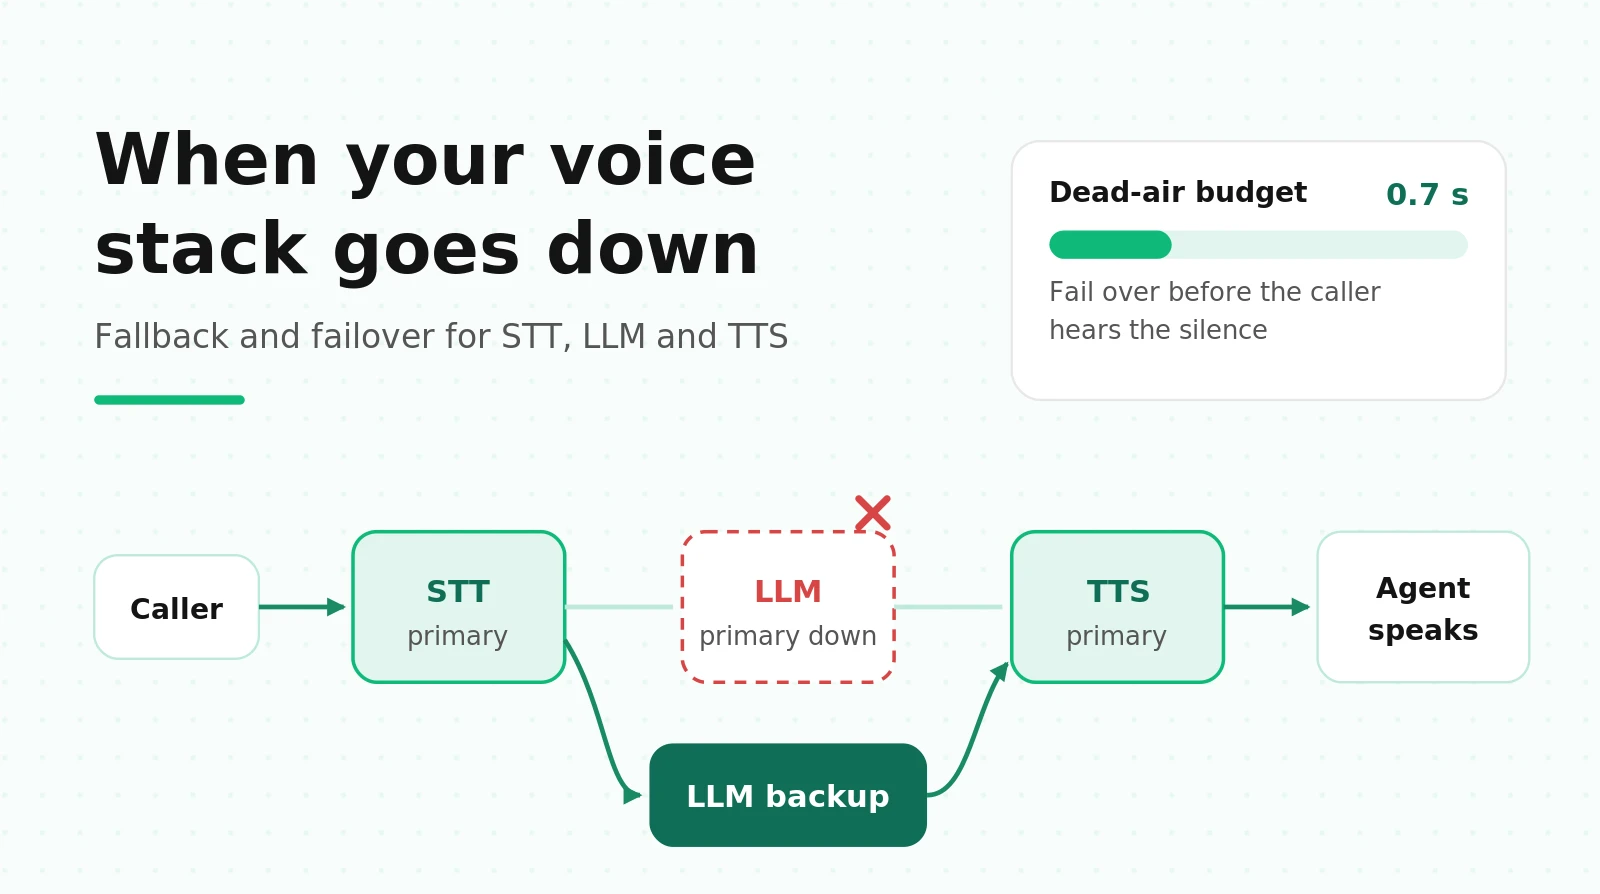
When Your STT, LLM or TTS Provider Goes Down: Voice Agent Fallback and Failover That Holds Up on Live Calls
Voice agent fallback, verified in source: what callers hear when STT, LLM or TTS fails, real timeout defaults, availability math and fault-injection tests.
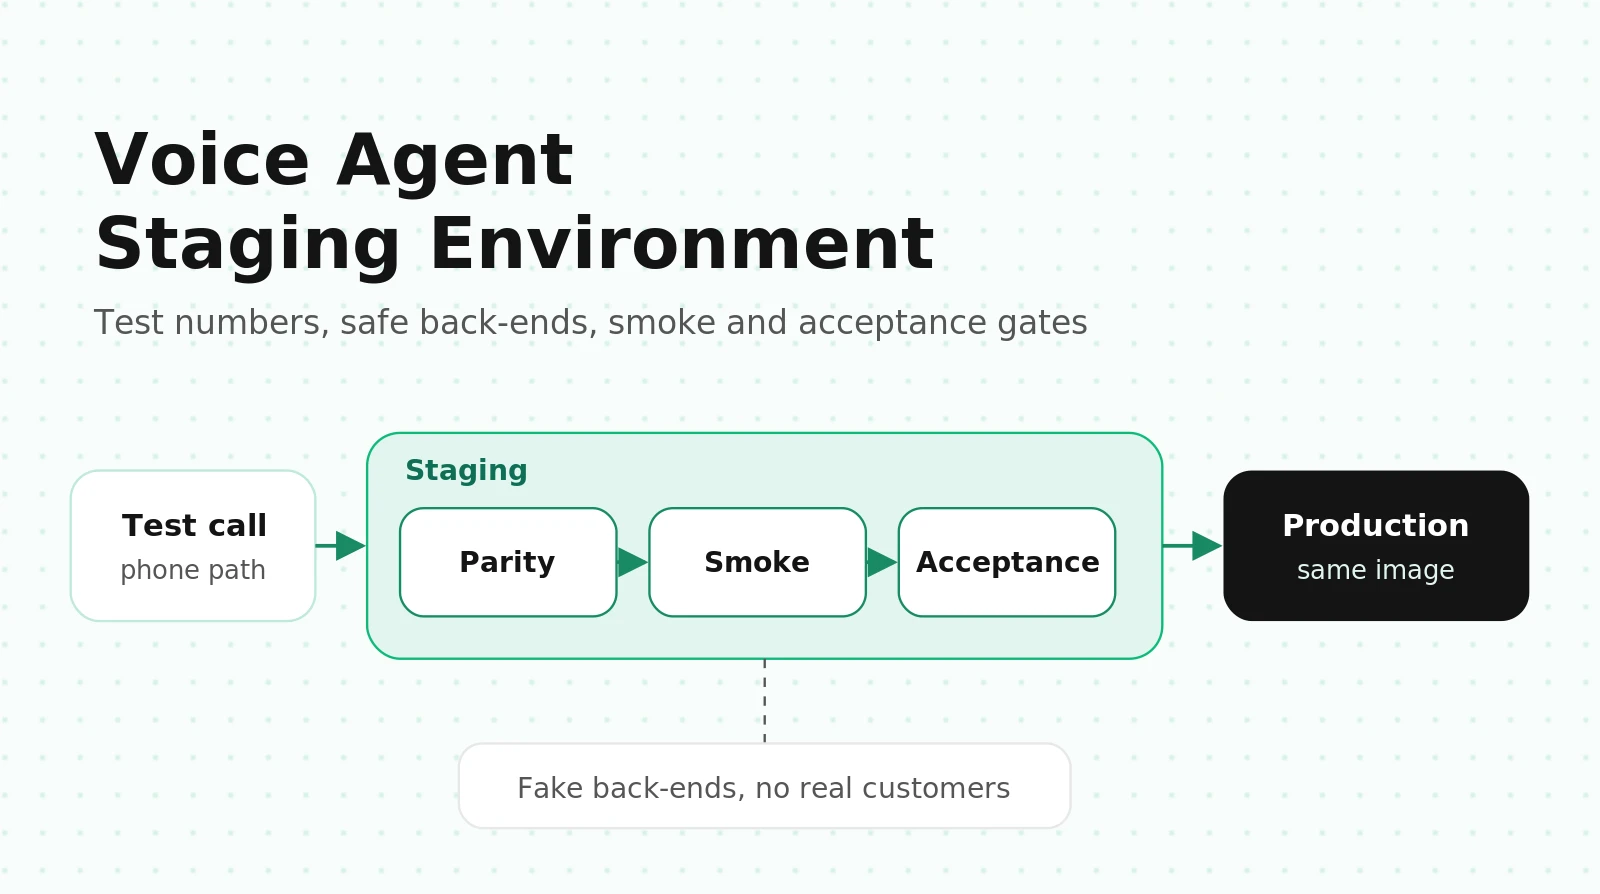
How to Set Up a Voice Agent Staging Environment: Test Numbers, Sandboxes, Smoke and Acceptance Tests
Build a voice agent staging environment on LiveKit or Pipecat: parity checks, test numbers, safe back-ends, a 5-minute smoke suite and promotion gates.
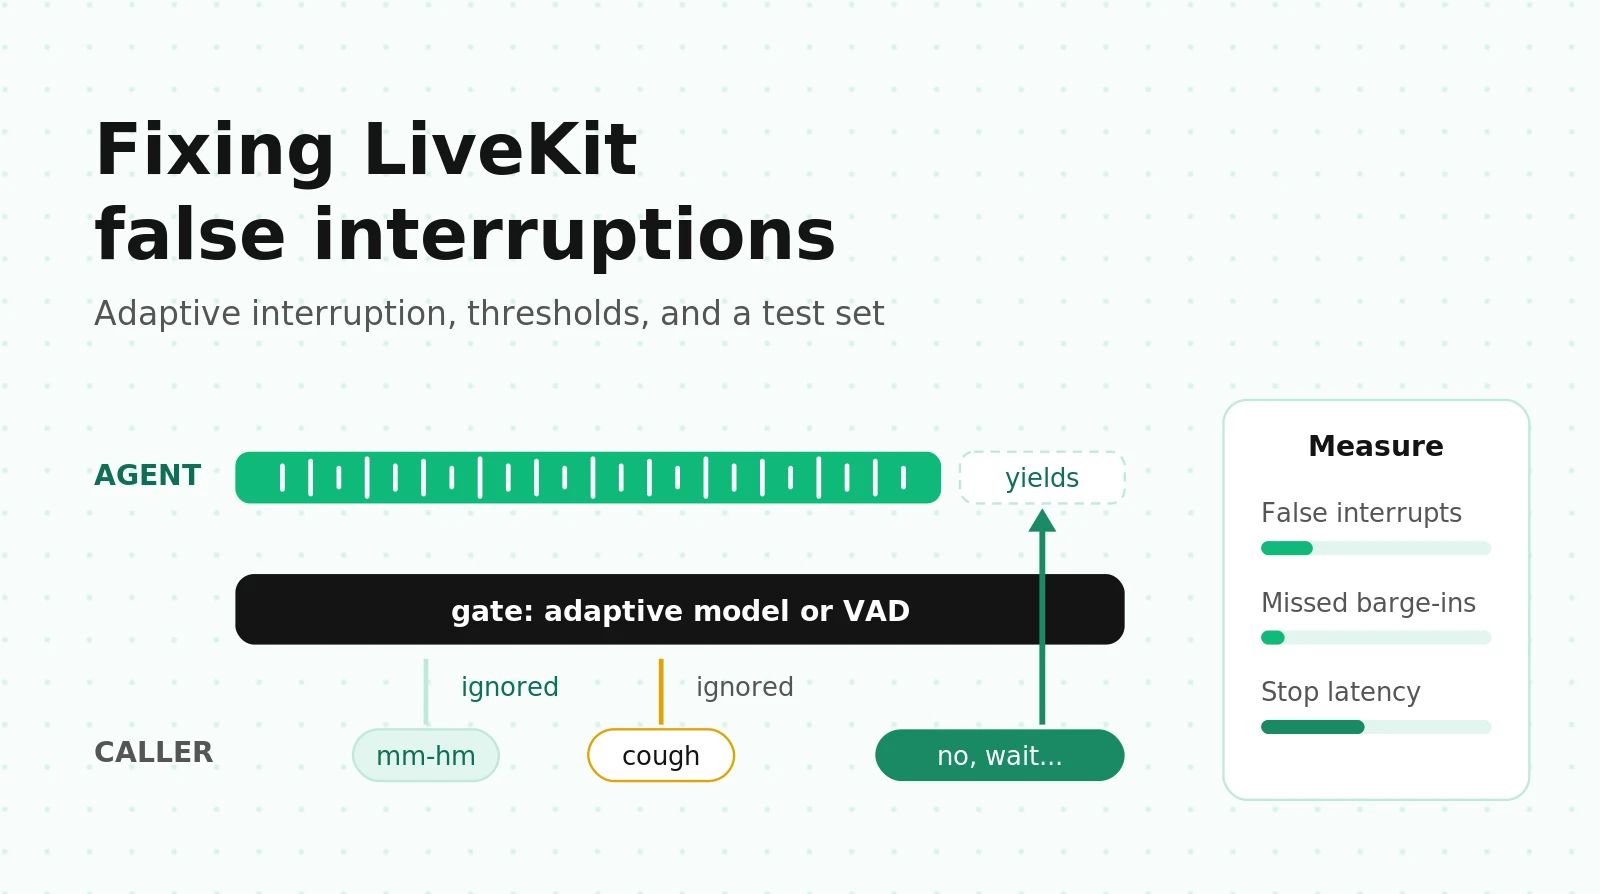
Fixing False Interruptions in LiveKit Agents: Adaptive Interruption, Thresholds and How to Test
Why LiveKit agents stop for mm-hm, coughs and echo, how adaptive interruption and min_duration work in the source, and a test set with pass thresholds.
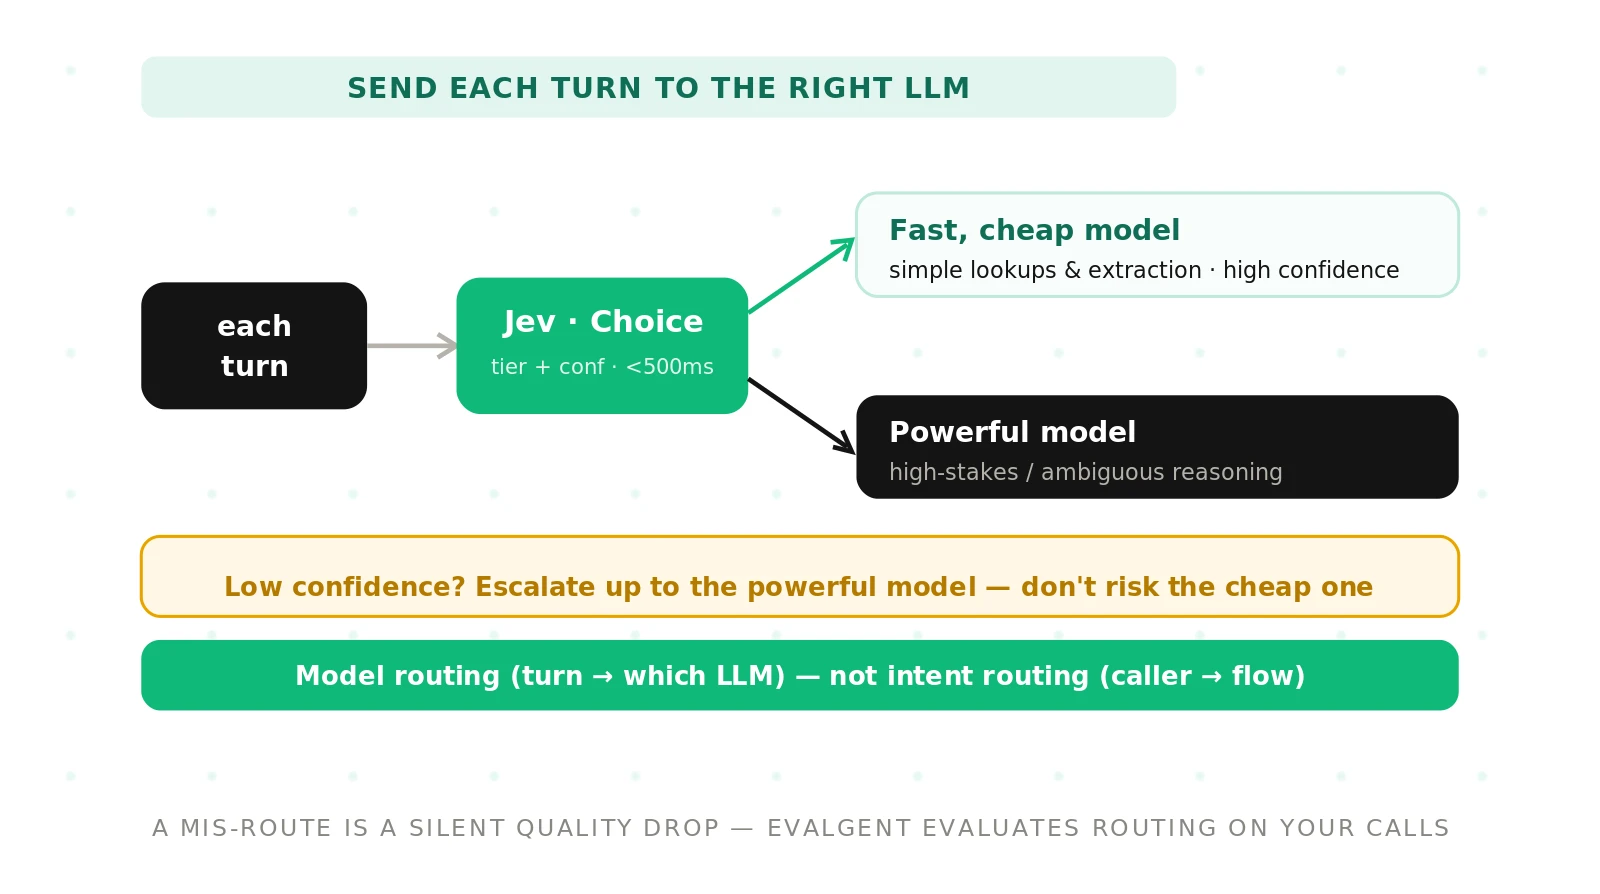
Jev Model Routing: Use Jev as a Model Router for Voice Agents
Jev model routing: use Jev as a model router that sends each voice turn to the right LLM. LangChain and API code, confidence gating, cost math, and evals.
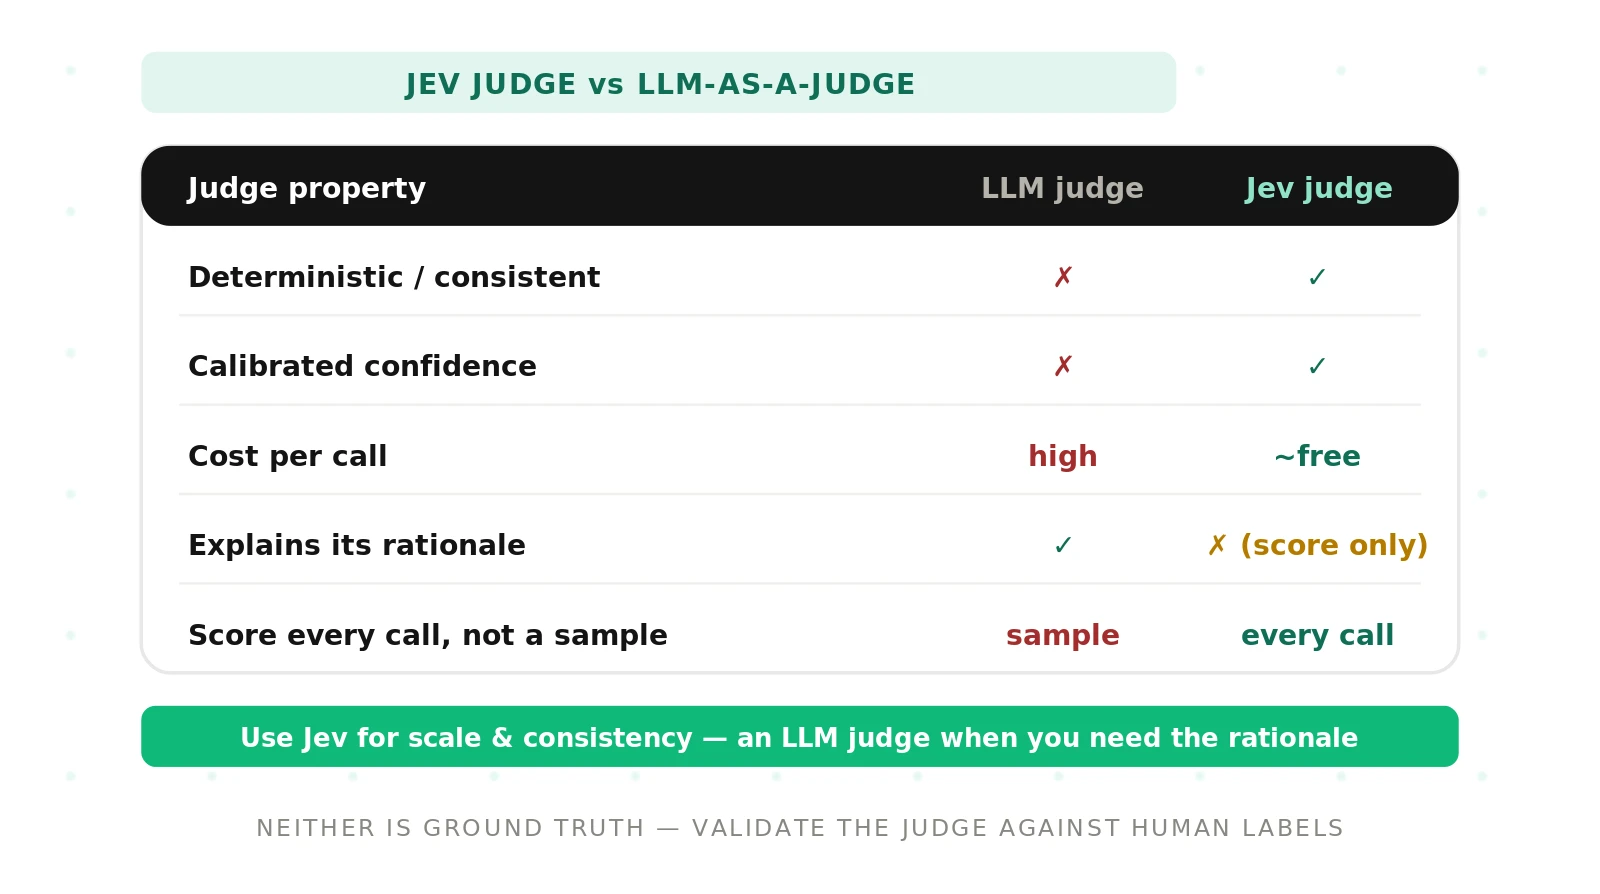
Jev as a Judge: A Calibrated Alternative to LLM-as-a-Judge
Jev as a judge matched human labels on 500 of 500 decisions in LangChain's study, at $0.34 vs $28.17 for Claude. Then build and validate a Jev judge.