Blog
Page 13 of 14
Pipecat voice agent testing guide: what to check before going live
Before your Pipecat agent goes live, check VAD, frame drops, transport, the Flows state machine, and pipeline regression. A pre-launch testing checklist.
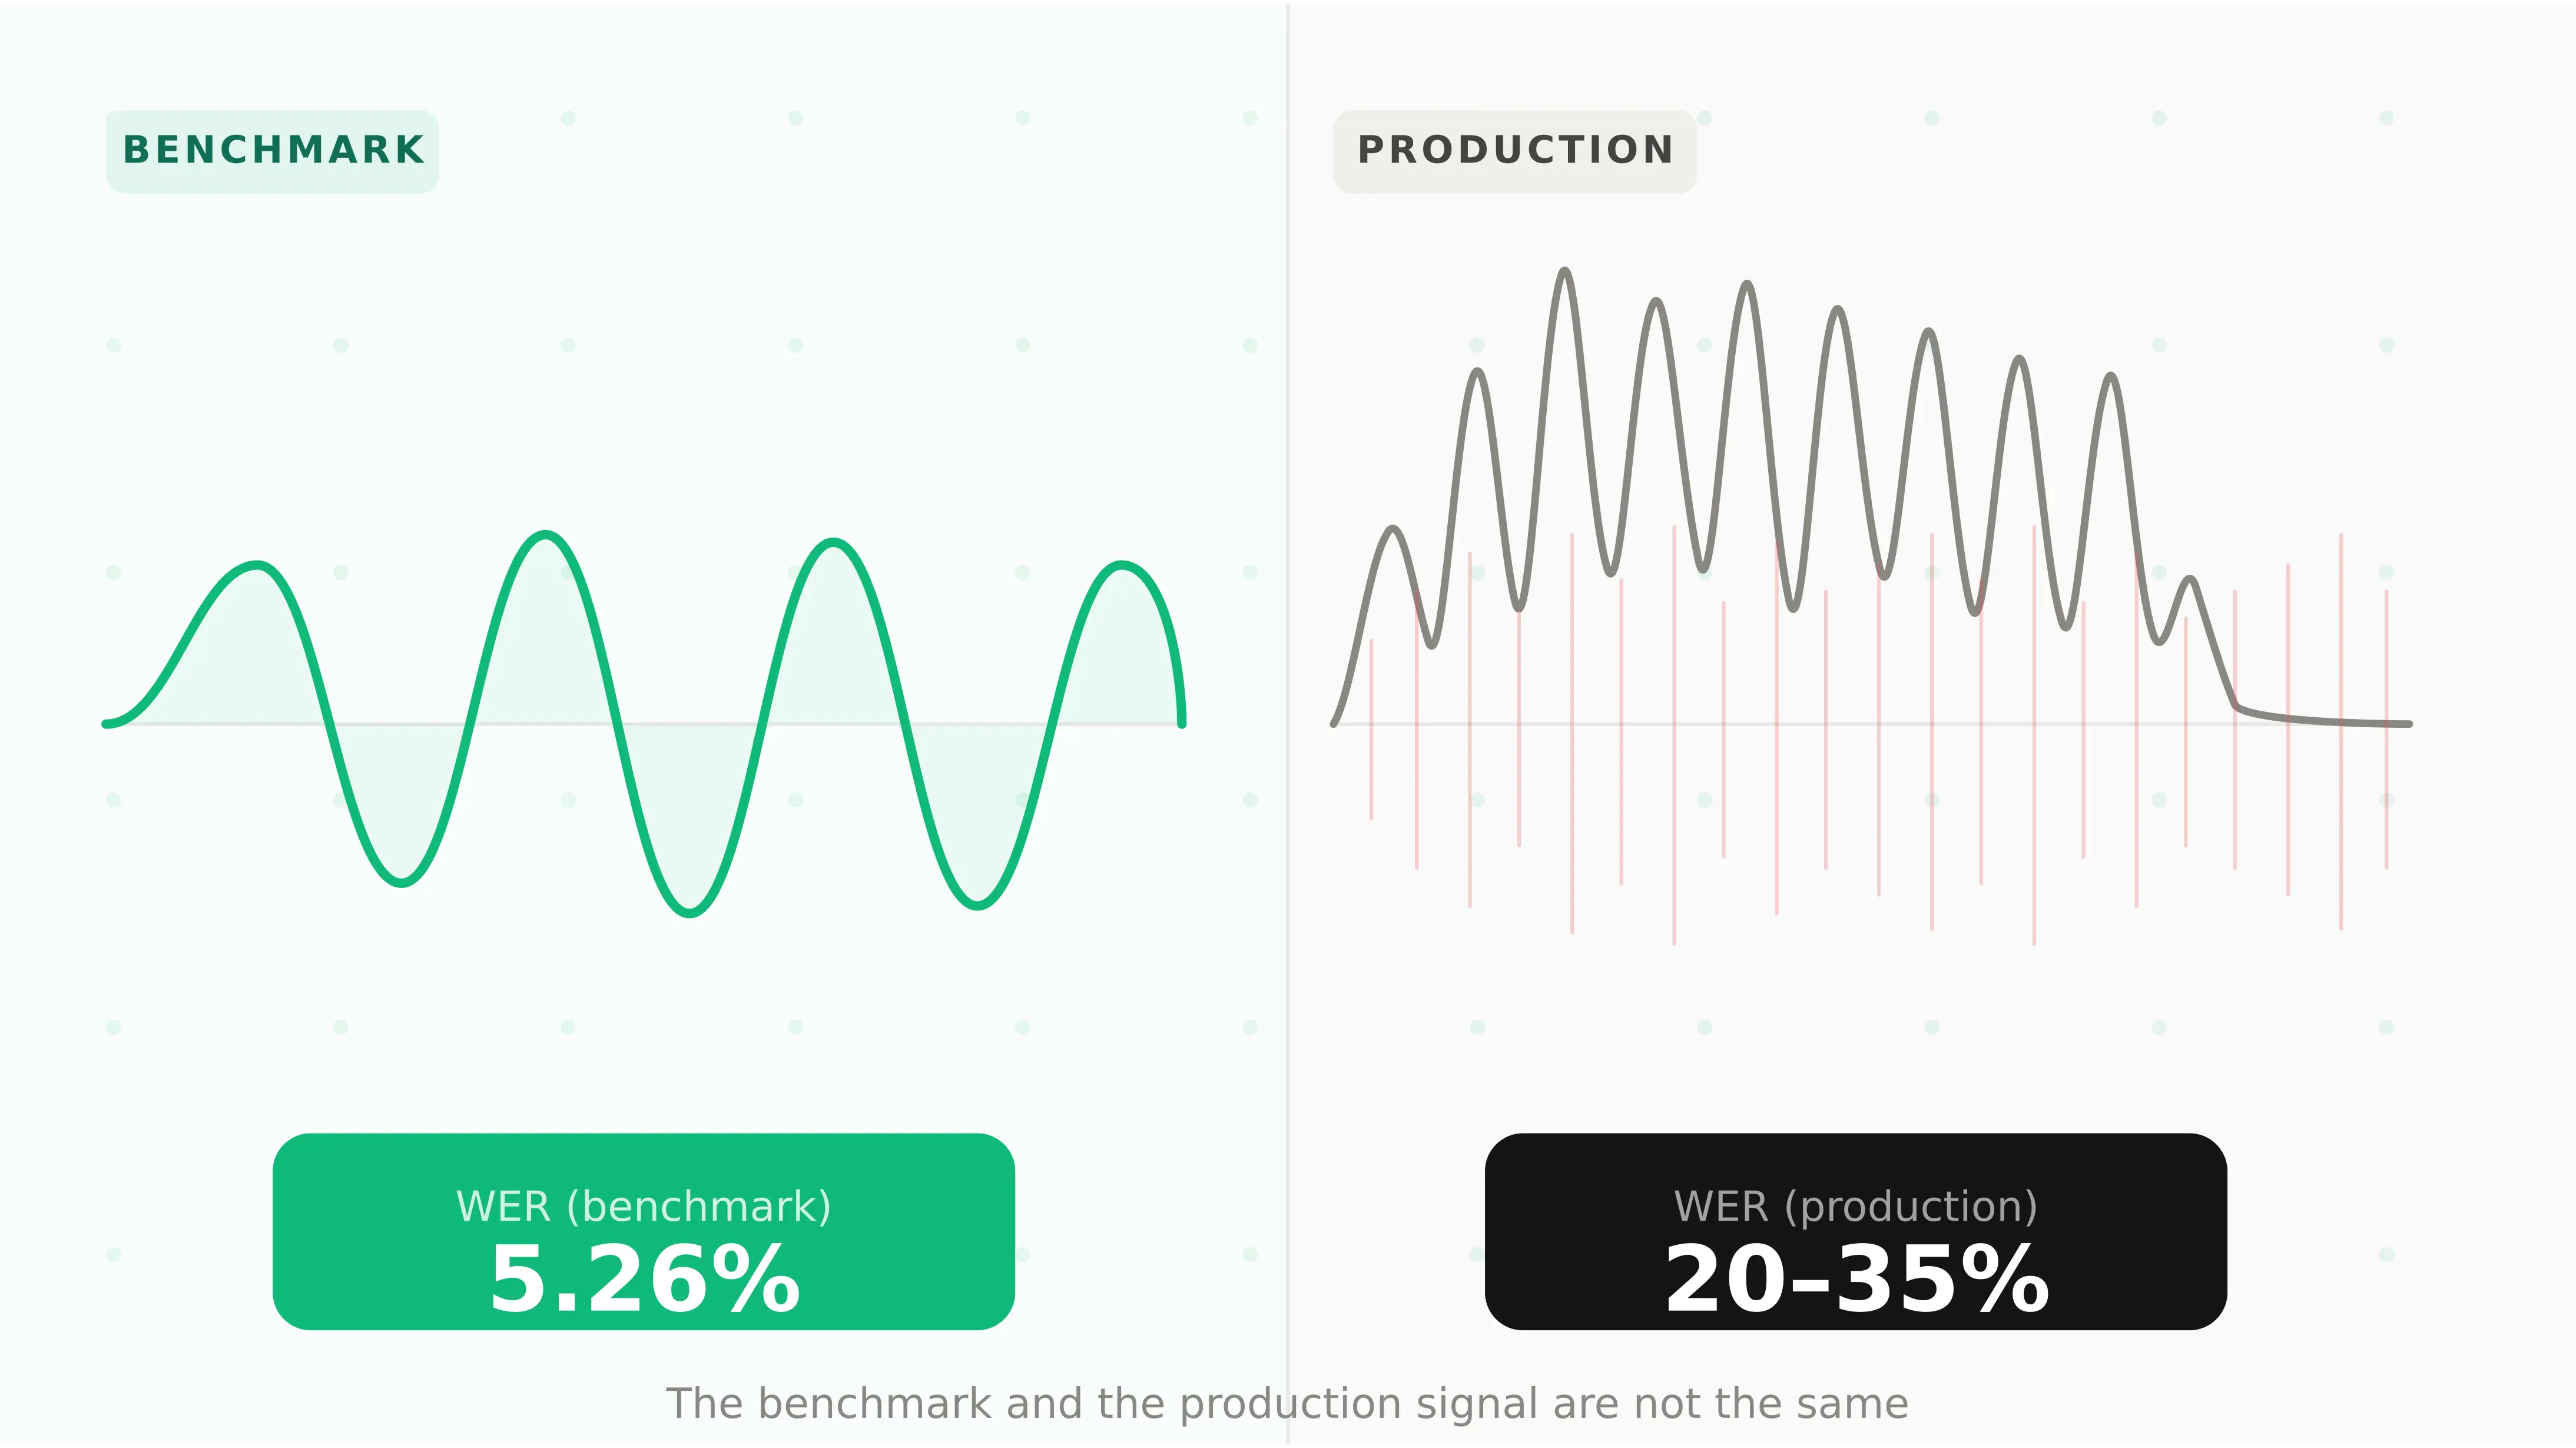
Deepgram STT testing guide for voice agents: what the benchmarks don't tell you
A practical guide to load-testing and monitoring Deepgram STT in voice agents: latency, WER under noise and accents, and error compounding before you go live.
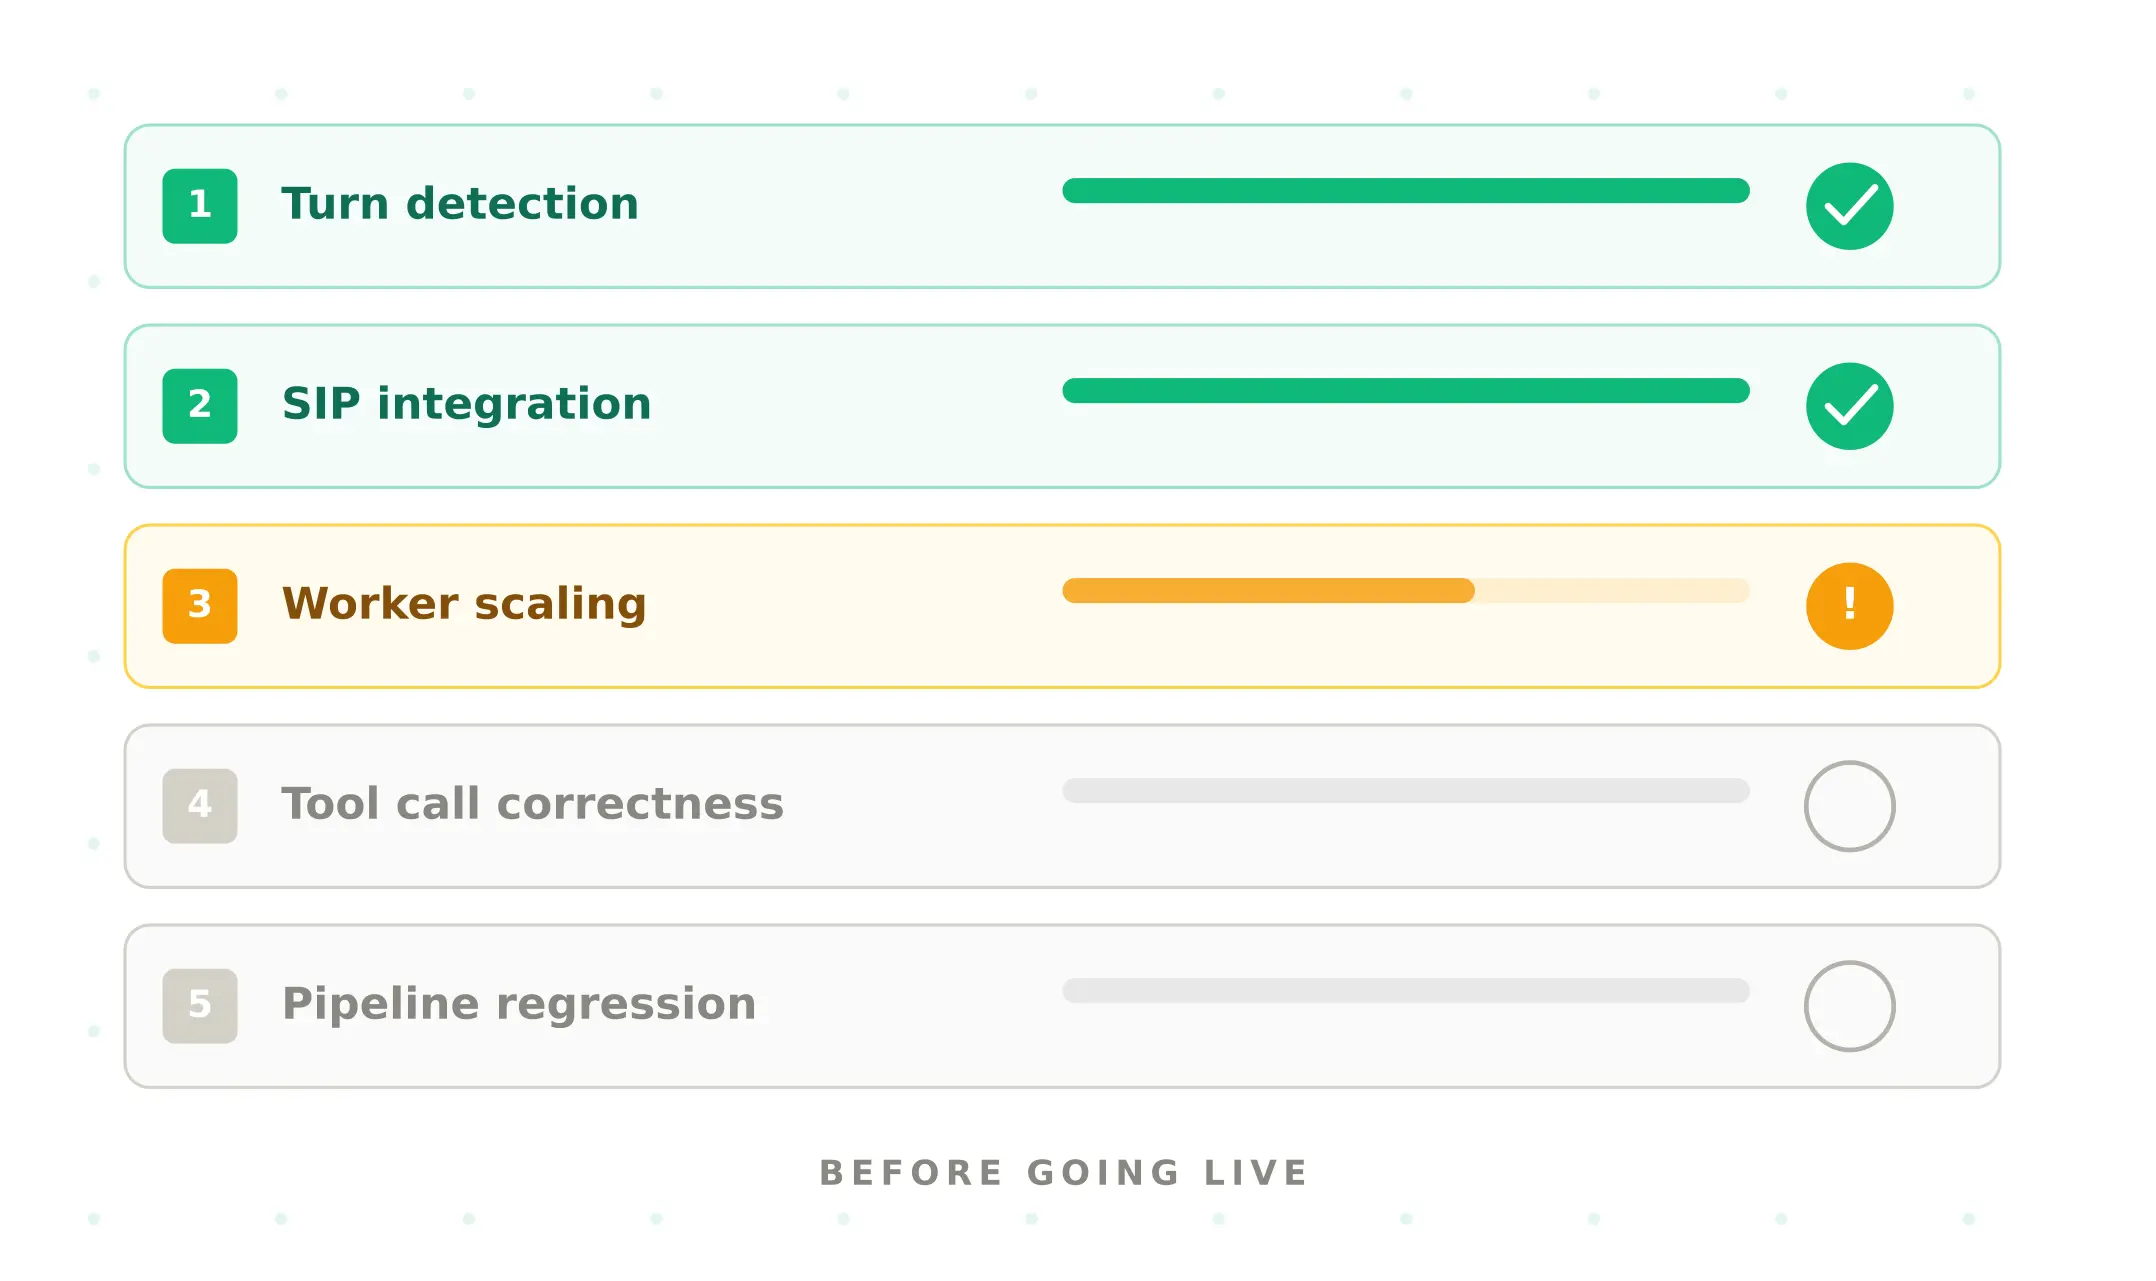
LiveKit voice agent testing guide: what to check before going live
LiveKit Agents testing guide: turn detection failures, SIP integration gaps, worker scaling, and prompt regression — what to check before going live.
Vapi voice agent testing guide: what to check before going live
Test your Vapi voice agent before going live. Covers BYOK costs, Squads handoff gaps, webhook failures, and prompt regression before real users find them.
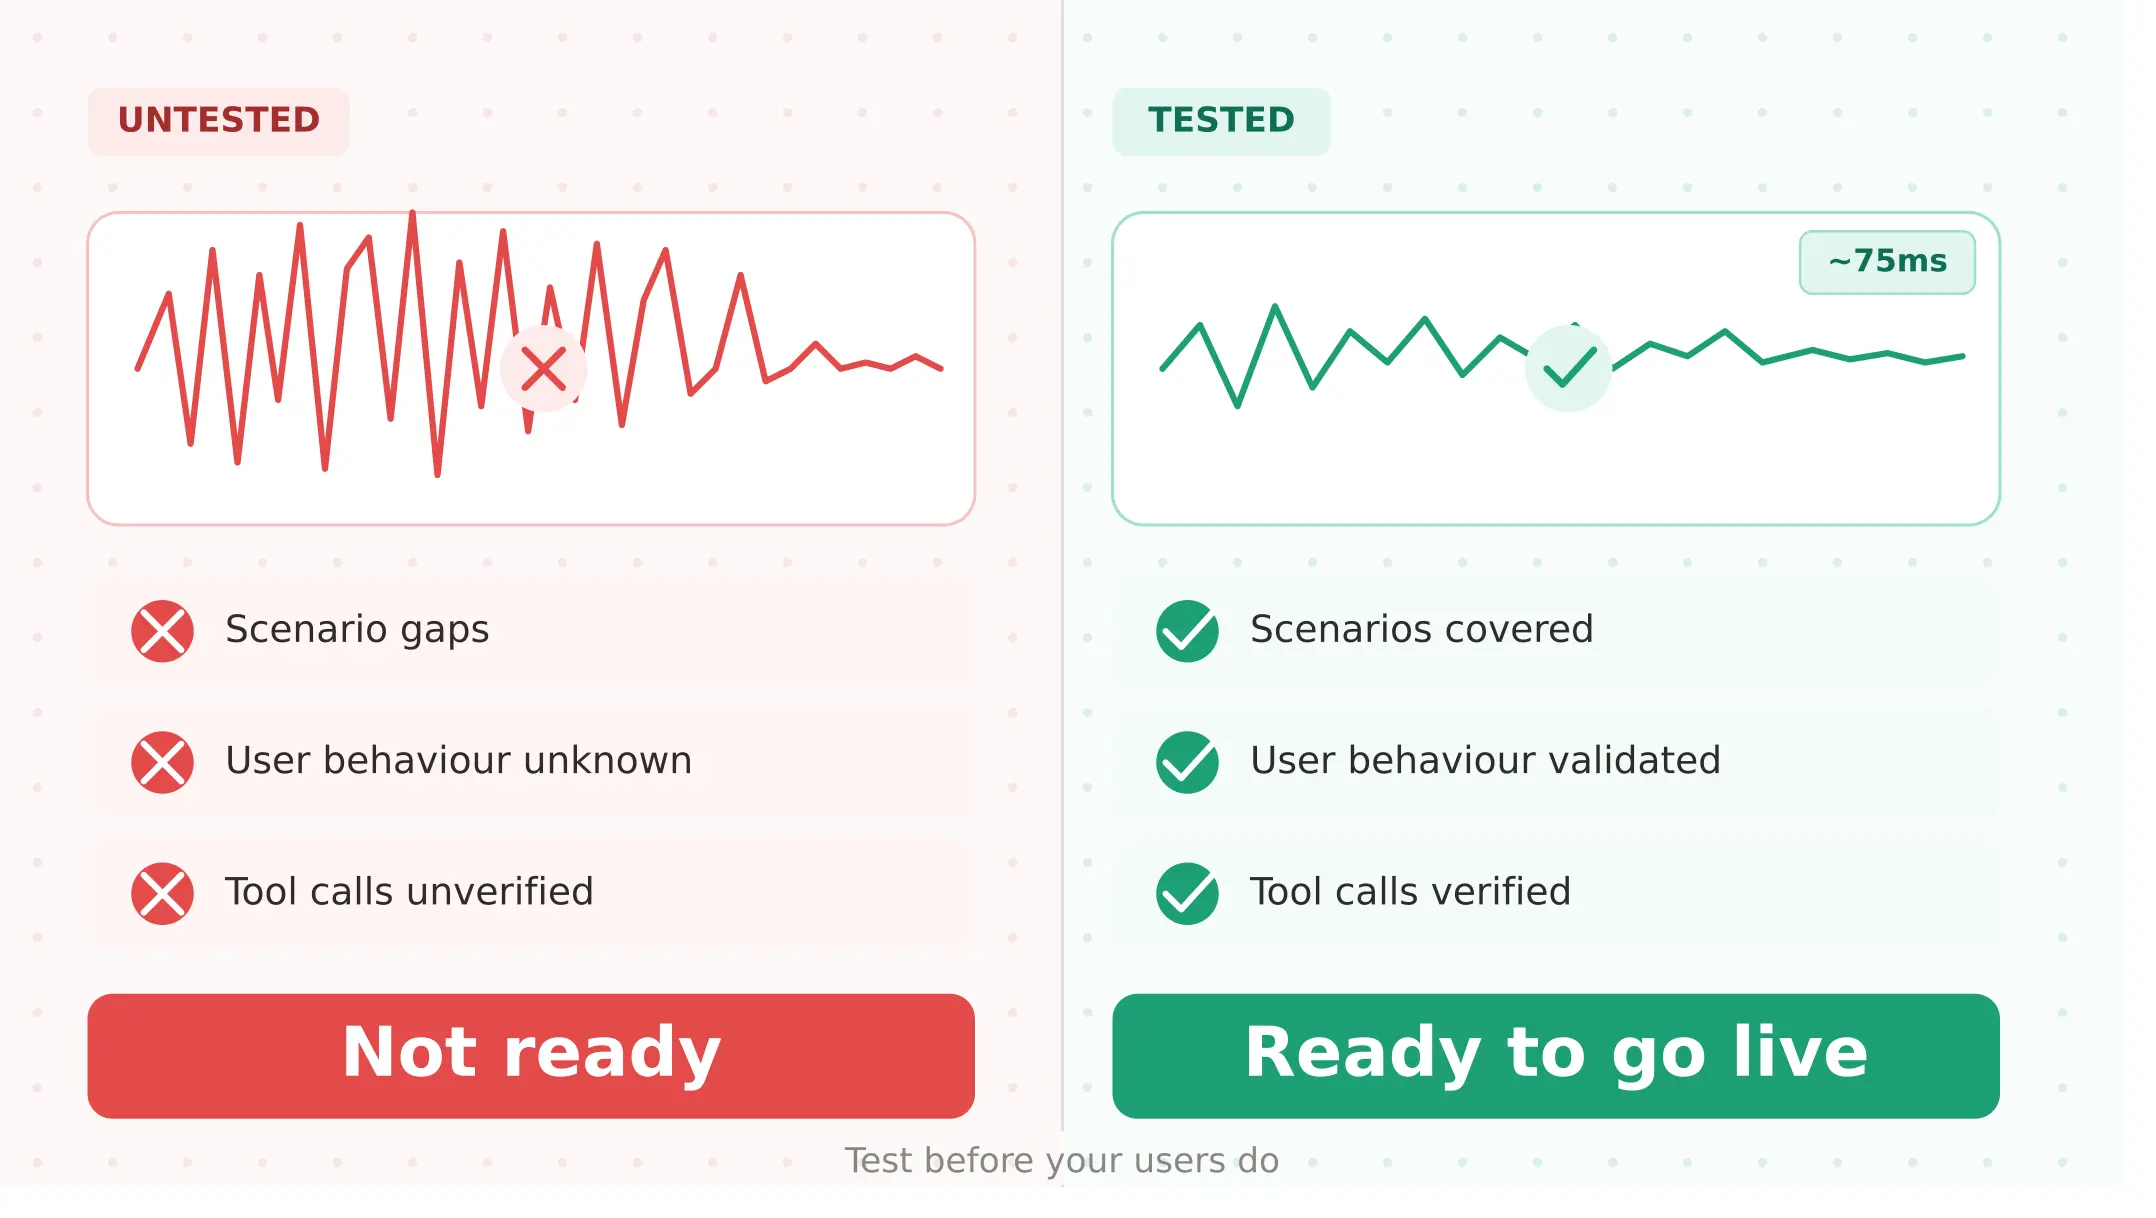
ElevenLabs voice agent testing guide: what to check before going live
Test your ElevenLabs voice agent before launch: scenario gaps, real user behaviour, tool calls, concurrency limits, and voice-quality regression.
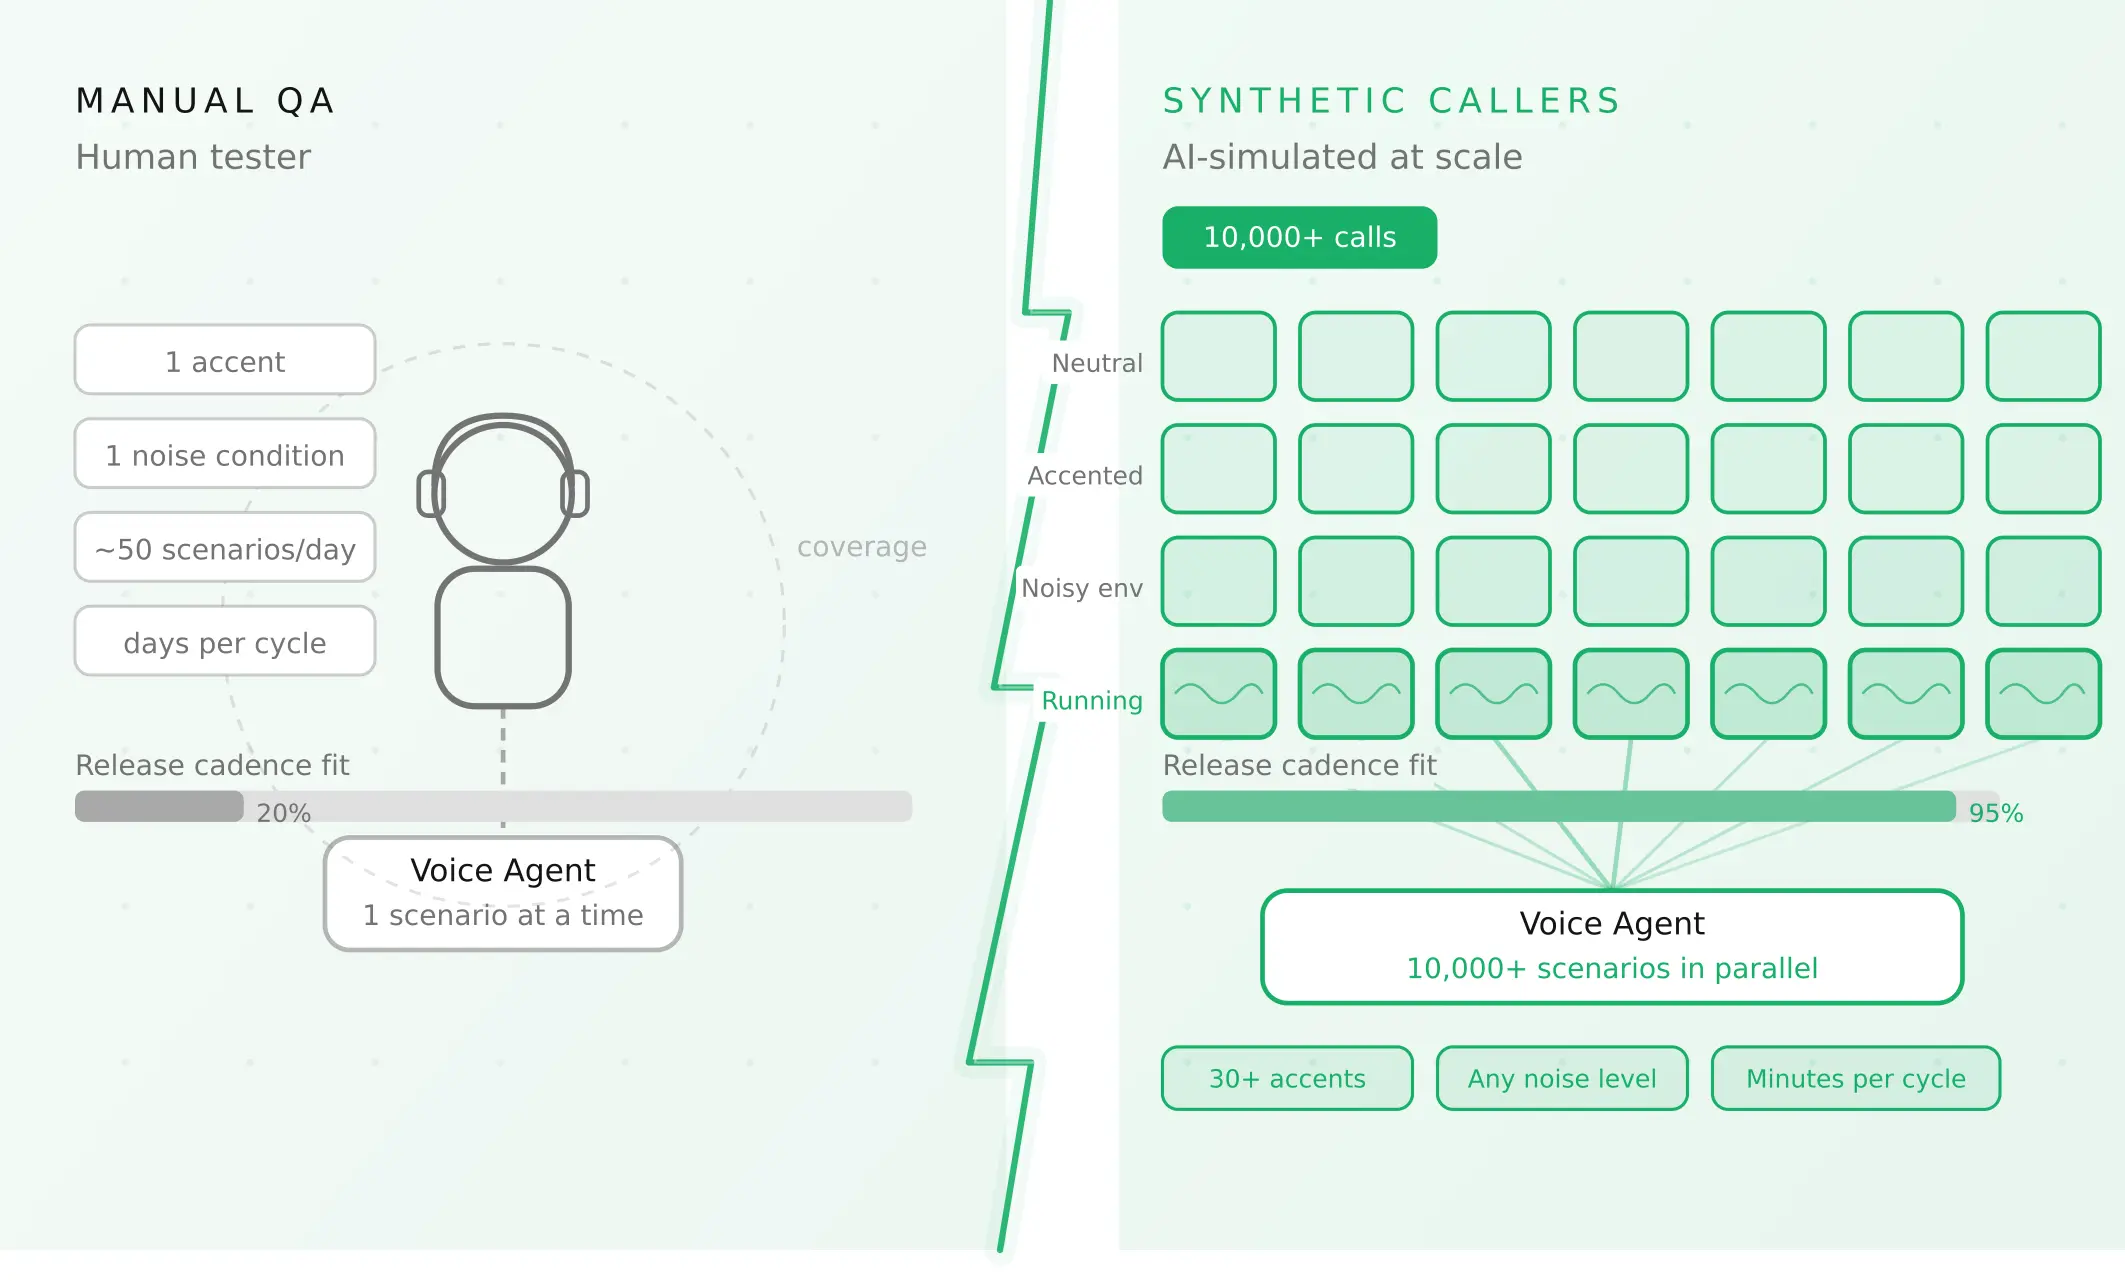
How to automate voice agent testing: synthetic callers vs manual QA
Learn how ai test automation replaces manual QA for voice agents. Compare synthetic callers vs human testers, with a 5-step framework to scale without hiring.

Voice agent regression testing: why LLM updates break production
LLM updates improve benchmarks but break voice agents in 5 predictable ways. How to detect and prevent regressions after every model or prompt change.
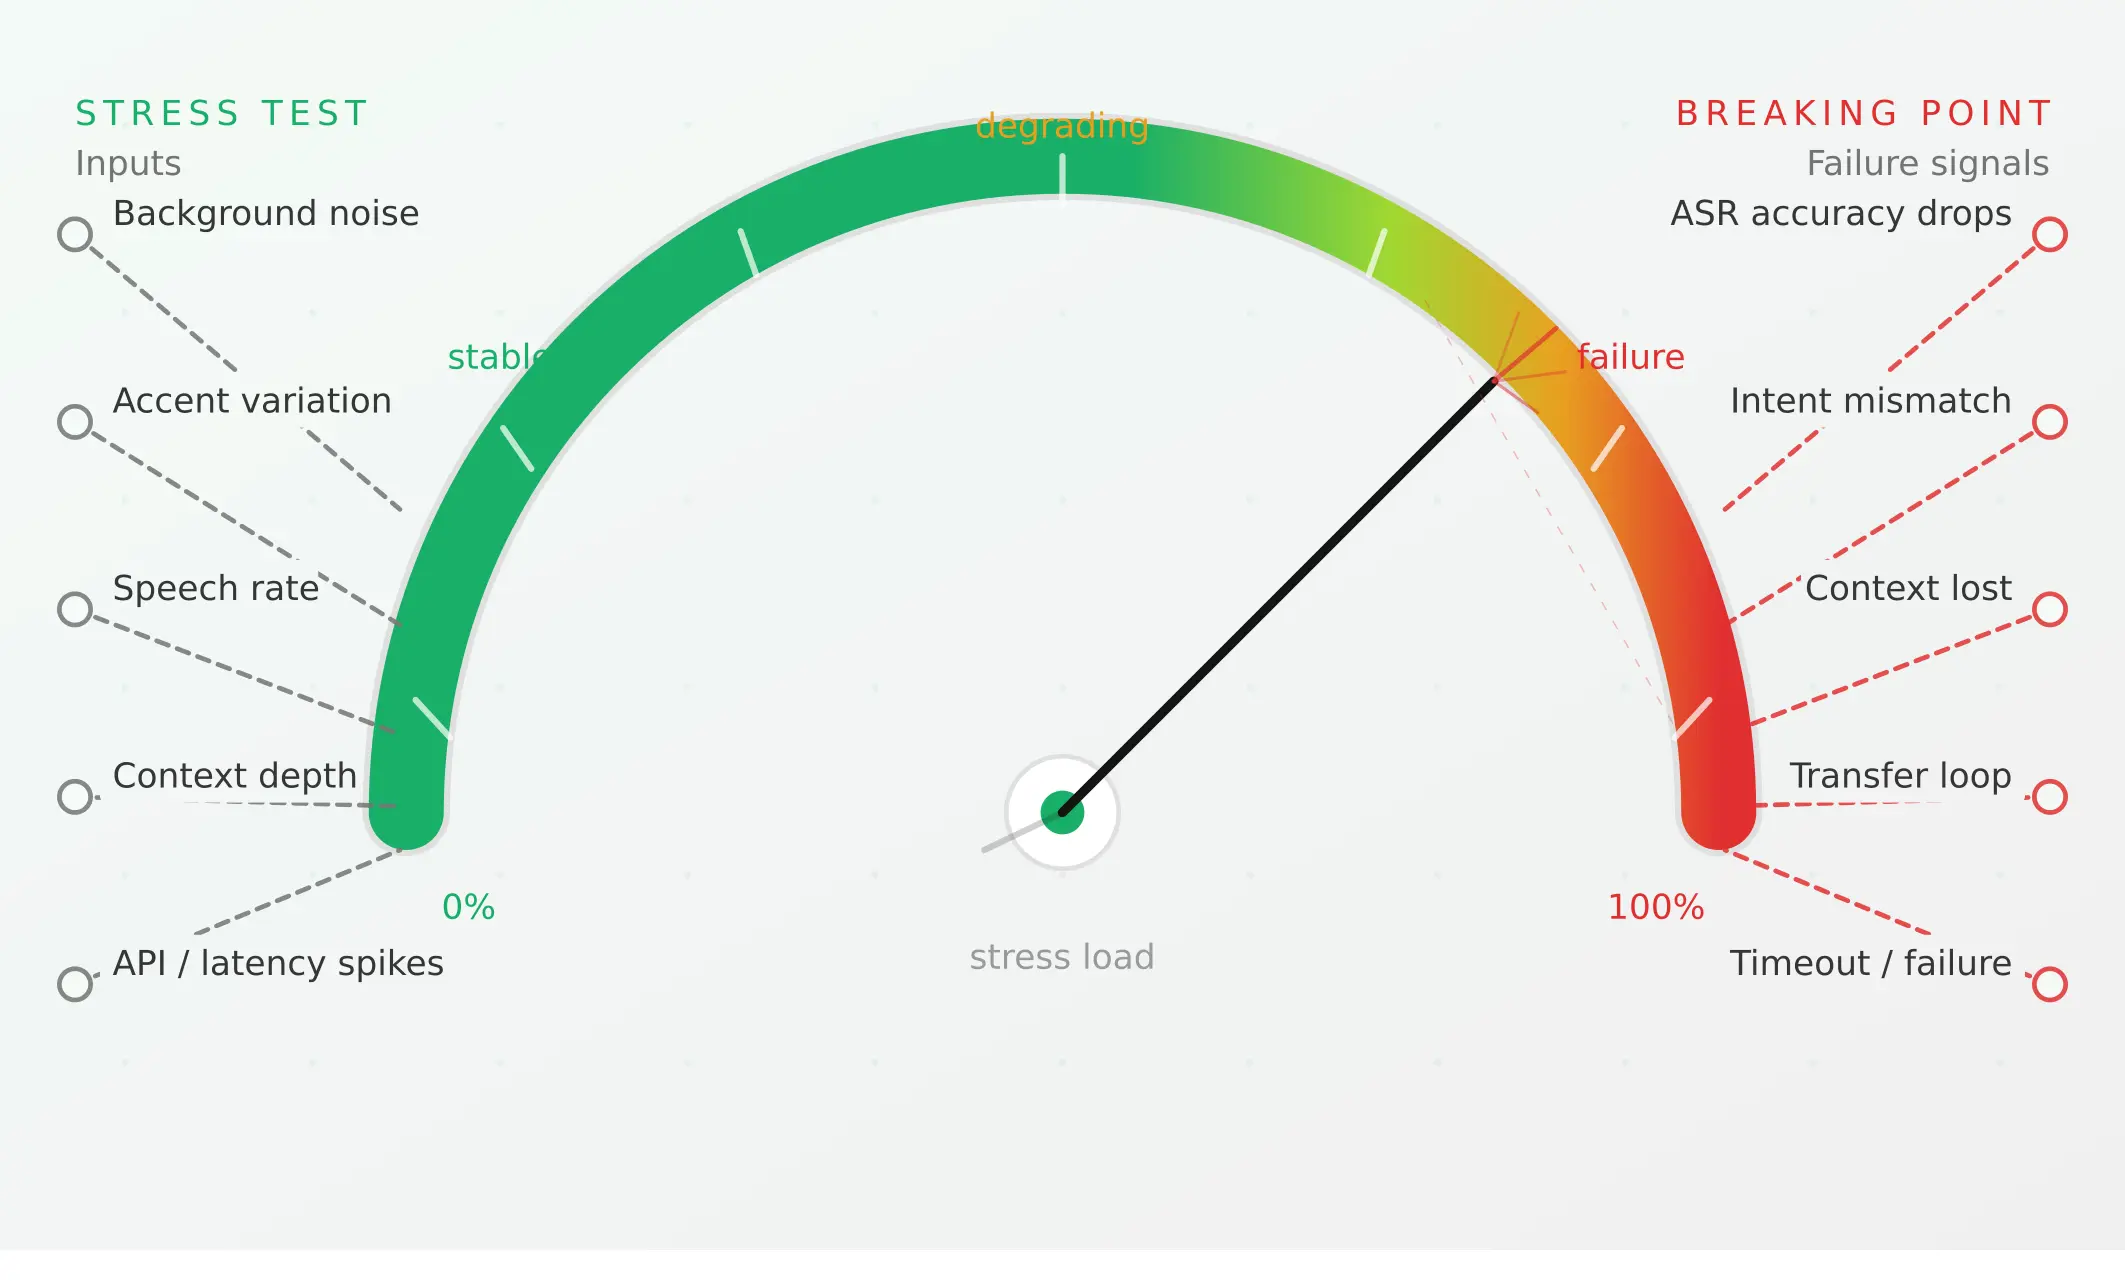
Conversational AI testing: the complete voice agent stress testing guide
Systematically stress-test voice agents to find breaking points across noise, accents, interruptions, and latency, before real users hit them.
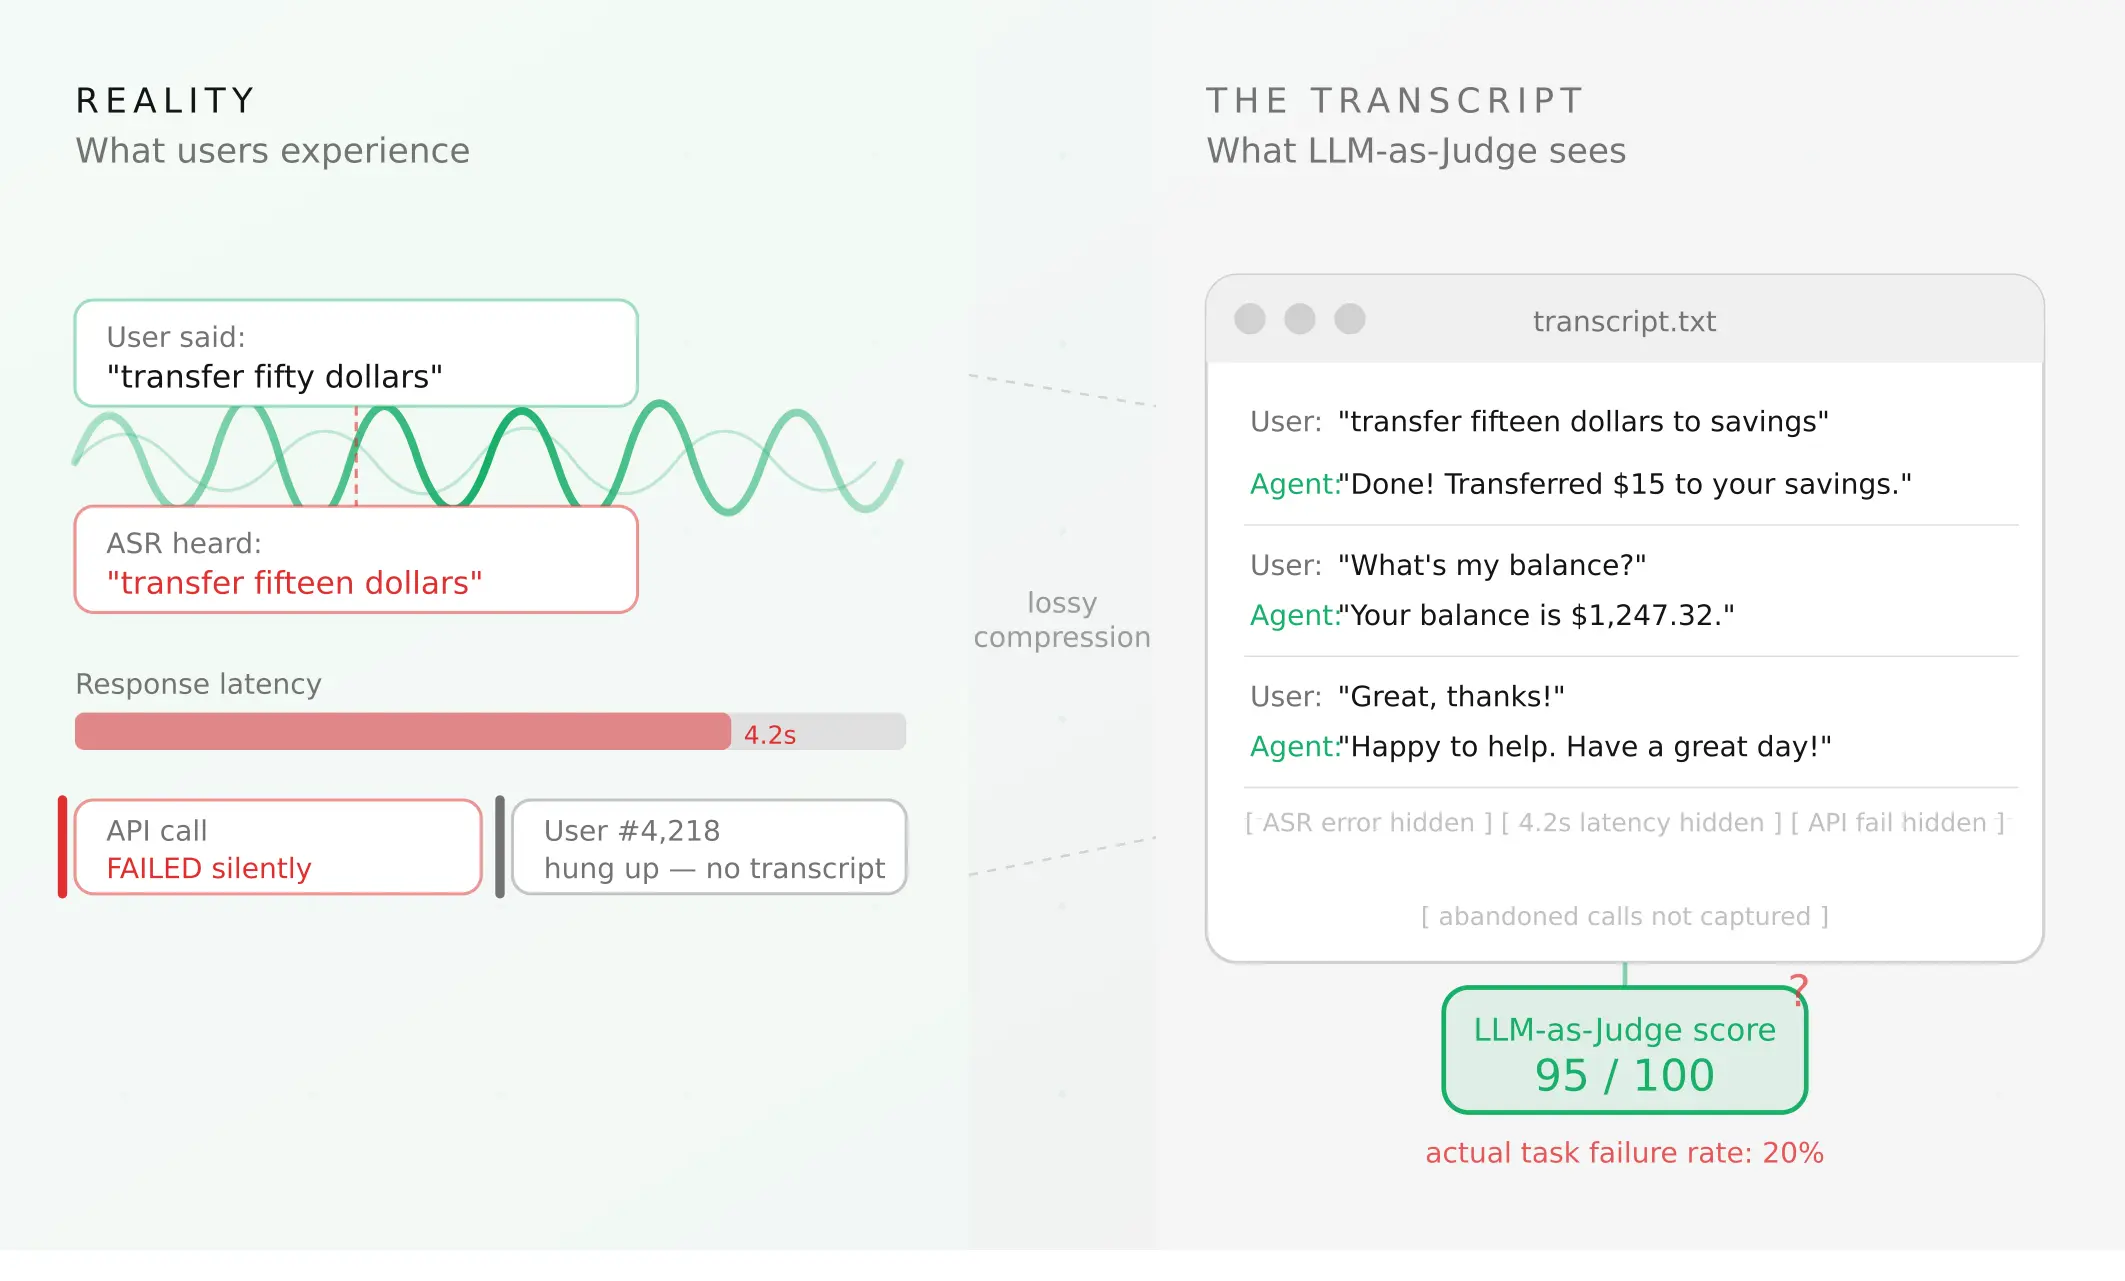
LLM as judge for voice agents: the hidden limits of transcript evaluation
LLM-as-judge scores voice agents high while real failures slip through. The 5 blind spots of transcript scoring, and what outcome-based evaluation looks like.